Recommended Models
 prunaai/flux-kontext-fast
Ultra fast flux kontext endpoint
Updated 2 days, 22 hours ago
24.3M runs
 prunaai/flux-fast
This is the fastest Flux endpoint in the world.
Updated 2 days, 22 hours ago
45.9M runs
prunaai/p-video-upscalePruna's video upscaler. Turn a low-resolution clip into a sharper 720p, 1080p, 2K, or 4K MP4 that keeps the original aspect ratio and audio, with optional frame interpolation up to 60 fps.
Updated 3 days ago
14.6K runs
 wan-video/wan-2.5-t2v
Alibaba Wan 2.5 text to video generation model
Updated 5 days, 12 hours ago
38.7K runs
 kwaivgi/kling-v3-motion-control
Kling 3.0 motion control: transfer motion from a reference video to any character image with improved consistency and quality.
Updated 5 days, 12 hours ago
553.5K runs
 google/gemini-4-carbon
Google's strongest reasoning model, built for complex coding, science, and long multi-step tasks
Updated 5 days, 12 hours ago
59.6K runs
wan-video/wan-2.6-i2vAlibaba Wan 2.6 image to video generation model
Updated 5 days, 12 hours ago
50.5K runs
 qwen/qwen3-7-plus
Qwen3.7-Plus is Alibaba's cost-effective multimodal model with vision-language understanding, a 1 million token context window, and strong agentic coding and tool use.
Updated 5 days, 13 hours ago
707.5K runs
 bytedance/omni-human-1.5
A film-grade digital human model that generates realistic video from a single image, audio clip, and optional text prompt.
Updated 5 days, 13 hours ago
70.5K runs
 minimax/music-2.6
Generate full-length songs or instrumentals from a text prompt, with optional auto-generated lyrics
Updated 5 days, 13 hours ago
111.6K runs
 minimax/music-cover
Reimagine any song in a different style — change voice, instruments, genre, and arrangement while keeping the original melody
Updated 5 days, 13 hours ago
14.9K runs
 minimax/music-2.5
Generate full-length songs with vocals, lyrics, and rich instrumentation from a text prompt
Updated 5 days, 13 hours ago
16.9K runs
 minimax/music-1.5
Music-1.5: Full-length songs (up to 4 mins) with natural vocals & rich instrumentation
Updated 5 days, 13 hours ago
134.7K runs
 qwen/qwen-image-2
A next-generation image generation and editing model from Alibaba's Qwen team. Supports text-to-image and image editing with strong text rendering, especially for Chinese.
Updated 5 days, 13 hours ago
101.9K runs
 minimax/image-01
Minimax's first image model, with character reference support
Updated 5 days, 13 hours ago
3.3M runs
 alibaba/qwen-image-3-pro
Qwen-Image-3.0-Pro generates and edits images with dense, accurate text rendering, complex multi-element layouts, and photographic detail.
Updated 5 days, 13 hours ago
62.7K runs
 recraft-ai/recraft-20b-svg
Affordable and fast vector images
Updated 5 days, 13 hours ago
140.1K runs
 recraft-ai/recraft-20b
Affordable and fast images
Updated 5 days, 13 hours ago
341K runs
 recraft-ai/recraft-v3
Recraft V3 (code-named red_panda) is a text-to-image model with the ability to generate long texts, and images in a wide list of styles. As of today, it is SOTA in image generation, proven by the Text-to-Image Benchmark by Artificial Analysis
Updated 5 days, 13 hours ago
8.8M runs
 recraft-ai/recraft-v3-svg
Recraft V3 SVG (code-named red_panda) is a text-to-image model with the ability to generate high quality SVG images including logotypes, and icons. The model supports a wide list of styles.
Updated 5 days, 13 hours ago
478.5K runs
 xai/grok-imagine-image
SOTA image model from xAI
Updated 5 days, 13 hours ago
7.1M runs
 wan-video/wan-2.7-image-pro
Generate and edit high-quality images with Alibaba's Wan 2.7 Pro with 4K output, thinking mode, text-to-image, multi-image editing, and image set generation
Updated 5 days, 13 hours ago
592.9K runs
 alibaba/qwen-image-3
Qwen-Image-3.0 generates and edits images with accurate text rendering, complex layouts, and photographic detail.
Updated 5 days, 13 hours ago
12.4K runs
 wan-video/wan-2.7-image
Generate and edit images with Alibaba's Wan 2.7
Updated 5 days, 13 hours ago
275.3K runs
 minimax/music-01
Quickly generate up to 1 minute of music with lyrics and vocals in the style of a reference track
Updated 5 days, 13 hours ago
563.5K runs
bytedance/omni-humanTurns your audio/video/images into professional-quality animated videos
Updated 5 days, 13 hours ago
170.4K runs
 xai/grok-text-to-speech
Convert text to natural-sounding speech with xAI's Grok TTS. 5 voices, 20 languages, expressive speech tags, and high-fidelity MP3 / WAV / telephony audio output.
Updated 5 days, 13 hours ago
2.1M runs
kwaivgi/kling-v2.6-motion-controlEnables precise control of character actions and expressions from a reference image.
Updated 5 days, 13 hours ago
1.2M runs
 bytedance/seedance-2.0
ByteDance's multimodal video generation model with native audio, multimodal reference inputs, and intelligent duration control.
Updated 5 days, 13 hours ago
1.7M runs
bytedance/seedance-2.0-fastA faster variant of Seedance 2.0 for quicker video generation with multimodal inputs and native audio.
Updated 5 days, 13 hours ago
845.8K runs
bytedance/dreamactor-m2.0Animate any character, humans, cartoons, animals, even non-humans, from a single image + driving video
Updated 5 days, 13 hours ago
51.8K runs
kwaivgi/kling-v3-videoKling Video 3.0: Generate cinematic videos up to 15 seconds with multi-shot control, native audio, and improved consistency
Updated 5 days, 13 hours ago
665.4K runs
kwaivgi/kling-v3-omni-videoKling Video 3.0 Omni: Unified multimodal video generation with reference images, video editing, native audio, and multi-shot control
Updated 5 days, 13 hours ago
897.5K runs
 minimax/video-01-director
Generate videos with specific camera movements
Updated 5 days, 13 hours ago
78.5K runs
 recraft-ai/recraft-v4-pro-svg
Generate detailed SVG vector graphics from text prompts. Recraft V4 Pro's design taste with more geometric detail and finer paths — clean layers, editable output, and scalable to any size.
Updated 5 days, 13 hours ago
12.1K runs
 bytedance/seedance-1-lite
A video generation model that offers text-to-video and image-to-video support for 5s or 10s videos, at 480p and 720p resolution
Updated 5 days, 13 hours ago
3.9M runs
 bytedance/seedance-2.5
ByteDance's flagship video model, with native audio, 30-second clips, and large sets of image, video, and audio references.
Updated 5 days, 13 hours ago
390.6K runs
wan-video/wan-2.5-i2vAlibaba Wan 2.5 Image to video generation with background audio
Updated 5 days, 13 hours ago
234.1K runs
 openai/gpt-oss-120b
120b open-weight language model from OpenAI
Updated 5 days, 13 hours ago
598.3K runs
xai/grok-imagine-r2vGenerate videos guided by reference images using xAI's Grok Imagine Video model
Updated 5 days, 13 hours ago
69.9K runs
kwaivgi/kling-v4.0Kling 4.0: generate 3 to 30 second videos at up to 1080p from text, keyframes, reference images, or reference videos, and edit existing videos
Updated 5 days, 13 hours ago
26.8K runs
kwaivgi/kling-avatar-v2Create avatar videos with realistic humans, animals, cartoons, or stylized characters
Updated 5 days, 13 hours ago
46.7K runs
kwaivgi/kling-v2.5-turbo-proKling 2.5 Turbo Pro: Unlock pro-level text-to-video and image-to-video creation with smooth motion, cinematic depth, and remarkable prompt adherence.
Updated 5 days, 13 hours ago
3.2M runs
xai/grok-imagine-video-extensionExtend videos with xAI's Grok Imagine Video model. Provide a source video and describe what happens next.
Updated 5 days, 13 hours ago
8.7K runs
xai/grok-imagine-videoxAI's video model. Generate short videos with synchronized sound from text, animate an image, or edit a video.
Updated 5 days, 13 hours ago
2.2M runs
xai/grok-imagine-video-1.5Image-to-video with synchronized audio using xAI's Grok Imagine Video 1.5 preview model
Updated 5 days, 13 hours ago
395.4K runs
kwaivgi/kling-v2.6Kling 2.6 Pro: Top-tier image-to-video with cinematic visuals, fluid motion, and native audio generation
Updated 5 days, 13 hours ago
1M runs
 recraft-ai/recraft-v4.1-utility-pro
A faster, lighter Recraft image generation model at ~2048px resolution, optimized for high-volume production. Design taste and prompt accuracy at high resolution with better throughput.
Updated 5 days, 13 hours ago
3.5K runs
 minimax/video-01
Generate 6s videos with prompts or images. (Also known as Hailuo). Use a subject reference to make a video with a character and the S2V-01 model.
Updated 5 days, 13 hours ago
774.3K runs
 recraft-ai/recraft-v4.1-pro-svg
Generate detailed SVG vector graphics from text prompts. Recraft V4.1 Pro's design taste with more geometric detail and finer paths — clean layers, editable output, and scalable to any size.
Updated 5 days, 13 hours ago
4.4K runs
 minimax/h3
Generate videos with MiniMax H3, a multimodal video model from MiniMax that supports text-to-video, first- and last-frame image-to-video, and reference-based video generation.
Updated 5 days, 13 hours ago
114.8K runs
minimax/hailuo-2.3A high-fidelity video generation model optimized for realistic human motion, cinematic VFX, expressive characters, and strong prompt and style adherence across both text-to-video and image-to-video workflows
Updated 5 days, 13 hours ago
147.5K runs
 recraft-ai/recraft-v4-styles-pro-svg
Recraft V4 Styles Pro SVG generates high-quality editable vector images that match a reusable style or attached reference images.
Updated 5 days, 13 hours ago
878 runs
 recraft-ai/recraft-v4.1-utility
A faster, lighter Recraft image generation model optimized for high-volume and production pipelines. Same design taste as V4.1, built for speed and throughput.
Updated 5 days, 13 hours ago
69.2K runs
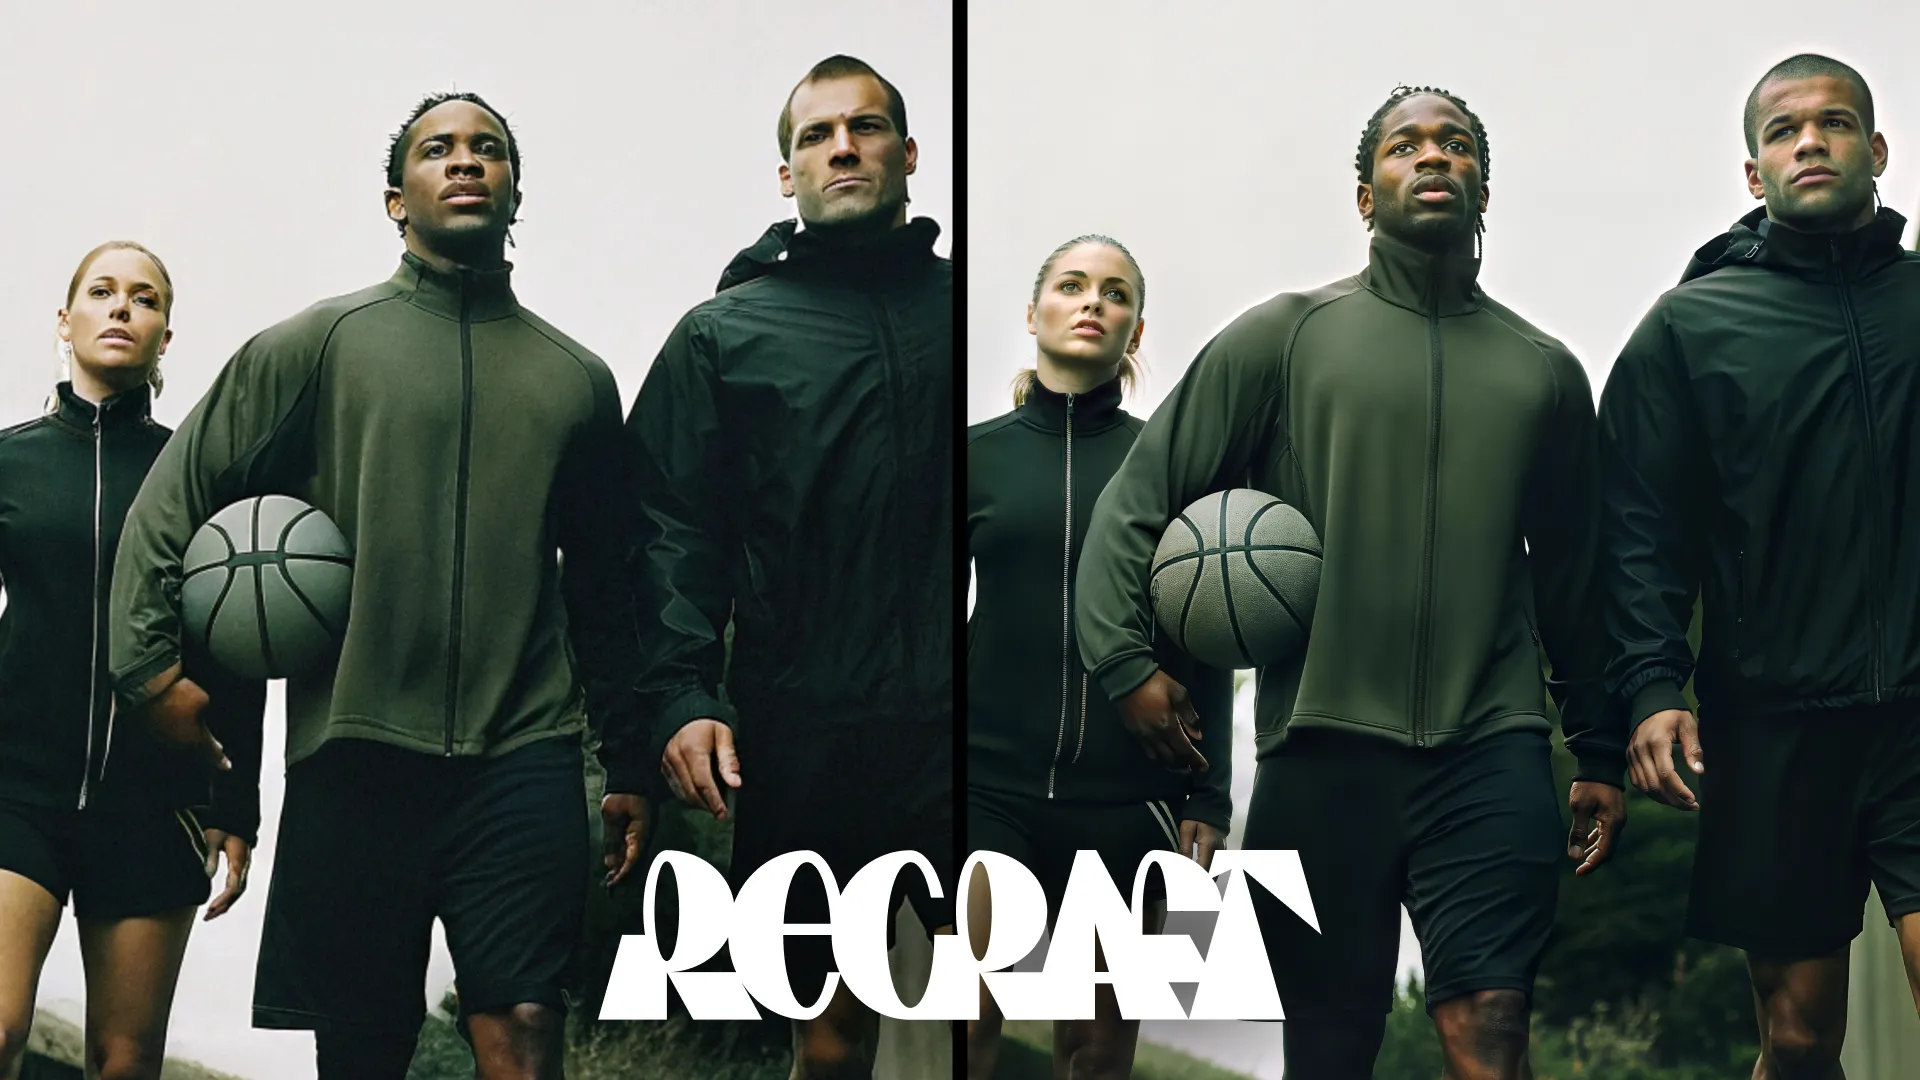 recraft-ai/recraft-creative-upscale
Creative Upscale focuses on enhancing details and refining complex elements in the image. It doesn’t just increase resolution but adds depth by improving textures, fine details, and facial features.
Updated 5 days, 13 hours ago
19.1K runs
 recraft-ai/recraft-v4.1-pro
Recraft's latest image generation model at ~2048px resolution. Same design taste and prompt accuracy as V4.1, with higher resolution for print-ready and large-scale work.
Updated 5 days, 13 hours ago
24.2K runs
minimax/hailuo-2.3-fastA lower-latency image-to-video version of Hailuo 2.3 that preserves core motion quality, visual consistency, and stylization performance while enabling faster iteration cycles.
Updated 5 days, 13 hours ago
340.5K runs
wan-video/wan-2.7-videoeditEdit videos with natural language instructions using Alibaba's Wan 2.7 VideoEdit model
Updated 5 days, 13 hours ago
20.8K runs
 bytedance/seedream-5-pro
ByteDance's flagship text-to-image and image editing model, generating sharp 1K and 2K images from text or up to 10 reference images
Updated 5 days, 13 hours ago
859.3K runs
alibaba/happyhorse-1.0Alibaba's Happy Horse 1.0 generates videos from text prompts or animates a single image into video. Supports 720p and 1080p, 3-15 second durations, and five aspect ratios.
Updated 5 days, 13 hours ago
35.1K runs
 openai/gpt-oss-20b
20b open-weight language model from OpenAI
Updated 5 days, 13 hours ago
696.2K runs
 xai/grok-imagine-image-quality
xAI's Grok Imagine Image Quality, now served by Grok Imagine Image 2.0 at low quality, with output up to 2k
Updated 5 days, 13 hours ago
1.2M runs
 bytedance/seedream-4.5
Seedream 4.5: Upgraded Bytedance image model with stronger spatial understanding and world knowledge
Updated 5 days, 13 hours ago
37.7M runs
 minimax/video-01-live
An image-to-video (I2V) model specifically trained for Live2D and general animation use cases
Updated 5 days, 13 hours ago
191.9K runs
minimax/hailuo-02Hailuo 2 is a text-to-video and image-to-video model that can make 6s or 10s videos at 768p (standard) or 1080p (pro). It excels at real world physics.
Updated 5 days, 13 hours ago
478.5K runs
wan-video/wan-2.7-t2vGenerate videos with audio from text prompts using Alibaba's Wan 2.7 model. 1080p, up to 15 seconds, with audio synchronization.
Updated 5 days, 13 hours ago
24.3K runs
alibaba/happyhorse-1.1Alibaba's Happy Horse 1.1 generates videos from text, animates a single image, or builds a video from multiple reference images. Supports 720p and 1080p, 3-15 second durations, and five aspect ratios.
Updated 5 days, 13 hours ago
31.2K runs
 recraft-ai/recraft-v4-svg
Generate production-ready SVG vector images from text prompts. Recraft V4's design taste applied to vector output — clean geometry, structured layers, and editable paths.
Updated 5 days, 13 hours ago
67.8K runs
 recraft-ai/recraft-v4-pro
Recraft's latest image generation model at ~2048px resolution. Same design taste and prompt accuracy as V4, with higher resolution for print-ready and large-scale work.
Updated 5 days, 13 hours ago
25.5K runs
 recraft-ai/recraft-v4
Recraft's latest image generation model, built around design taste. Strong prompt accuracy, art-directed composition, and integrated text rendering. Fast and cost-efficient at standard resolution.
Updated 5 days, 13 hours ago
1.1M runs
alibaba/wan-3Wan 3.0 generates video from a text prompt or a starting image, with cinematic motion and support for 480p, 720p, and 1080p output up to 30 seconds.
Updated 5 days, 13 hours ago
85.8K runs
 bria/image-3.2
Commercial-ready, trained entirely on licensed data, text-to-image model. With only 4B parameters provides exceptional aesthetics and text rendering. Evaluated to be on par to other leading models in the market
Updated 5 days, 13 hours ago
173.4K runs
 xai/grok-imagine-image-2
xAI's Grok Imagine Image 2.0 — text-to-image generation and editing with a quality control and output up to 2k
Updated 5 days, 13 hours ago
581.3K runs
 recraft-ai/recraft-v4.1
Recraft's latest image generation model, built around design taste. Strong prompt accuracy, art-directed composition, and integrated text rendering. Fast and cost-efficient at standard resolution.
Updated 5 days, 13 hours ago
255K runs
 recraft-ai/recraft-v4.1-svg
Generate production-ready SVG vector images from text prompts. Recraft V4.1's design taste applied to vector output — clean geometry, structured layers, and editable paths.
Updated 5 days, 13 hours ago
32.7K runs
 minimax/h3-highspeed
Generate videos with MiniMax H3 Highspeed, a faster version of MiniMax H3 that balances quality and speed. Supports text-to-video, first- and last-frame image-to-video, and reference-based video generation at 768P.
Updated 5 days, 13 hours ago
21K runs
 minimax/h3-lite
Generate videos with MiniMax H3 Lite, the lower-cost version of MiniMax H3. Supports text-to-video, first- and last-frame image-to-video, and reference-based video generation at 480P or 768P.
Updated 5 days, 13 hours ago
26.8K runs
 wan-video/wan-2.7-r2v
Generate videos from reference images or clips while preserving subject identity using Alibaba's Wan 2.7 reference-to-video model
Updated 5 days, 13 hours ago
8.3K runs
minimax/hailuo-02-fastA low cost and fast version of Hailuo 02. Generate 6s and 10s videos in 512p
Updated 5 days, 13 hours ago
70.7K runs
wan-video/wan2.6-i2v-flashImage-to-video generation with optional audio, multi-shot narrative support, and faster inference
Updated 5 days, 13 hours ago
97.5K runs
 bria/generate-background
Bria Background Generation allows for efficient swapping of backgrounds in images via text prompts or reference image, delivering realistic and polished results. Trained exclusively on licensed data for safe and risk-free commercial use
Updated 5 days, 13 hours ago
92.4K runs
 recraft-ai/recraft-crisp-upscale
Designed to make images sharper and cleaner, Crisp Upscale increases overall quality, making visuals suitable for web use or print-ready materials.
Updated 5 days, 13 hours ago
6.1M runs
 bria/expand-image
Bria Expand expands images beyond their borders in high quality. Resizing the image by generating new pixels to expand to the desired aspect ratio. Trained exclusively on licensed data for safe and risk-free commercial use
Updated 5 days, 13 hours ago
503.3K runs
 recraft-ai/recraft-vectorize
Convert raster images to high-quality SVG format with precision and clean vector paths, perfect for logos, icons, and scalable graphics.
Updated 5 days, 13 hours ago
1.3M runs
 alibaba/wan-3-prime
Generate videos from text prompts using Alibaba's Wan 3.0 Prime model. Up to 1080p and 30 seconds, with 480p, 720p, and 1080p output.
Updated 5 days, 13 hours ago
2.2K runs
 recraft-ai/recraft-remove-background
Automated background removal for images. Tuned for AI-generated content, product photos, portraits, and design workflows
Updated 5 days, 13 hours ago
1.7M runs
 wan-video/wan-2.7-i2v
Generate videos from images, with support for first-and-last-frame control, clip continuation, and audio synchronization using Alibaba's Wan 2.7 model
Updated 5 days, 13 hours ago
99.6K runs
 google/lyria-3.5
Generate full-length songs with vocals and lyrics from text prompts or images with Lyria 3.5, Google's most capable music generation model
Updated 5 days, 13 hours ago
1.1K runs
 google/lyria-3-pro
Generate full-length songs up to 3 minutes from text prompts or images with Lyria 3 Pro, Google's most capable music generation model
Updated 5 days, 13 hours ago
59.2K runs
 google/lyria-3
Generate 30-second music clips from text prompts or images with Lyria 3, Google's music generation model
Updated 5 days, 13 hours ago
646.2K runs
 openai/gpt-5.1
The best model for coding and agentic tasks with configurable reasoning effort.
Updated 5 days, 14 hours ago
290.4K runs
 openai/gpt-5-pro
The smartest, fastest, most useful model yet, with built-in thinking that puts expert-level intelligence in everyone’s hands
Updated 5 days, 14 hours ago
4.9K runs
 openai/gpt-5.2
The best model for coding and agentic tasks across industries
Updated 5 days, 14 hours ago
996.5K runs
 openai/gpt-4.1
OpenAI's Flagship GPT model for complex tasks.
Updated 5 days, 15 hours ago
412.4K runs
 openai/gpt-4o
OpenAI's high-intelligence chat model
Updated 5 days, 15 hours ago
1.1M runs
 openai/gpt-5
OpenAI's new model excelling at coding, writing, and reasoning.
Updated 5 days, 15 hours ago
2.8M runs
 openai/gpt-4o-mini
Low latency, low cost version of OpenAI's GPT-4o model
Updated 5 days, 15 hours ago
42.3M runs
 openai/gpt-5-nano
Fastest, most cost-effective GPT-5 model from OpenAI
Updated 5 days, 15 hours ago
24.9M runs
 openai/gpt-5.4
OpenAI's most capable frontier model for complex professional work, coding, and multi-step reasoning.
Updated 5 days, 15 hours ago
571K runs
 openai/gpt-5.6-luna
OpenAI's GPT-5.6 cost-optimized tier, built for fast, high-volume, latency-sensitive workloads.
Updated 5 days, 15 hours ago
305.7K runs
 openai/gpt-5.6-sol
OpenAI's GPT-5.6 flagship tier, built for complex professional work, coding, and deep multi-step reasoning.
Updated 5 days, 15 hours ago
166.5K runs
 openai/gpt-5.6-terra
OpenAI's GPT-5.6 balanced tier, tuned for everyday production work at roughly half the cost of the flagship.
Updated 5 days, 15 hours ago
306.6K runs
 openai/gpt-4.1-mini
Fast, affordable version of GPT-4.1
Updated 5 days, 15 hours ago
4.5M runs
 openai/gpt-5-mini
Faster version of OpenAI's flagship GPT-5 model
Updated 5 days, 15 hours ago
4.3M runs
 openai/gpt-5-structured
GPT-5 with support for structured outputs, web search and custom tools
Updated 5 days, 15 hours ago
1.1M runs
 openai/gpt-image-2.6-sunburst
OpenAI's image model for detailed compositions and precise edits. Generate and edit images from text and image inputs, with a complexity setting that controls how much the model plans before it renders.
Updated 5 days, 15 hours ago
57.2K runs
 openai/gpt-image-2
OpenAI's image generation and editing model. Create and edit images from text with close instruction following, sharp text rendering, and detailed edits.
Updated 5 days, 16 hours ago
35.8M runs
 openai/gpt-image-2.6-flare
OpenAI's fast image model for generating and editing images from text and image inputs. Adds a complexity setting that controls how much the model plans before it renders.
Updated 5 days, 16 hours ago
29.4K runs
 openai/gpt-image-2.5-sunburst
OpenAI's most capable image model, built for workflows where editing precision matters most. Generate and edit images from text and image inputs with strong instruction following, sharp text rendering, and detailed control.
Updated 5 days, 16 hours ago
4.5M runs
 openai/gpt-image-2.5-flare
OpenAI's fastest model for high-quality, everyday image generation. Generate and edit images from text and image inputs with strong instruction following and sharp text rendering.
Updated 5 days, 16 hours ago
5.9M runs
 openai/gpt-image-1.5
OpenAI's latest image generation model with better instruction following and adherence to prompts
Updated 5 days, 16 hours ago
16.3M runs
 anthropic/claude-fable-5.2
Anthropic's model for the most demanding reasoning and long-horizon agentic work, at 20% less per token than Fable 5
Updated 6 days, 11 hours ago
585 runs
kwaivgi/kling-v4-flashKling 4.0 Flash: a faster, cheaper Kling 4.0 that makes 3 to 20 second 720p videos with sound from text, a first frame, reference images, or reference videos, and edits existing videos
Updated 6 days, 12 hours ago
1.2K runs
 ideogram-ai/ideogram-4-5
Generate and edit images with Ideogram 4.5, the latest for precise image generation.
Updated 6 days, 14 hours ago
7.8K runs
 ideogram-ai/ideogram-4-5-precise-edit
Precisely edit source images with Ideogram 4.5.
Updated 6 days, 16 hours ago
24.6K runs
 anthropic/claude-opus-5.5
Anthropic's Opus model for long-running agentic coding and knowledge work, at a lower price than Opus 5
Updated 6 days, 17 hours ago
21.6K runs
prunaai/p-video-2-pro-replacePruna's person-swap model. Put the person from a picture into a source video, keep the camera, motion, and soundtrack, from 1 to 120 seconds and 480p to 4K.
Updated 6 days, 18 hours ago
5.3K runs
 google/gemini-omni-1.2-flash
Google's video generation and editing model with native audio. Makes 3 to 15 second clips from text, images, reference images, or an existing video.
Updated 1 week, 3 days ago
3.7K runs
 openai/gpt-image-1-mini
A cost-efficient version of GPT Image 1
Updated 1 week, 3 days ago
673.2K runs
 prunaai/p-video-2-pro
Pruna's highest-quality video model. Generate video from text or images with speed and quality modes, first- and last-frame control, and durations up to 15 seconds.
Updated 1 week, 4 days ago
881K runs
prunaai/p-videoFast video generation with built-in draft mode for rapid creative iteration. Text-to-video, image-to-video, and audio-to-video in a single endpoint.
Updated 1 week, 4 days ago
5.4M runs
prunaai/p-video-2-pro-avatarPruna's talking-avatar model. Turn a portrait and an audio file or script into a talking video with synced lips and expressions, from 1 second to 3 minutes long.
Updated 1 week, 4 days ago
47.7K runs
prunaai/p-video-avatarp-video-avatar is the fastest and cheapest avatar/lipsync video model on the market.
Updated 1 week, 4 days ago
674.2K runs
prunaai/p-video-animatep-video-animate animates a reference image with the motion and audio of a source video. Optimized for speed and cost — 5.24s per 1s of video.
Updated 1 week, 4 days ago
34.7K runs
prunaai/p-video-editEdit videos with a text prompt and optional reference images.
Updated 1 week, 4 days ago
26.7K runs
prunaai/p-video-2P-Video-2 is the quality-focused successor to P-Video from $0.025/s
Updated 1 week, 4 days ago
1.2M runs
prunaai/p-video-replacep-video-replace swaps the person in a video with one from a reference image, keeping motion, timing, camera, and scene exactly as they were. 3.58s per 1s of video generated.
Updated 1 week, 4 days ago
36K runs
 google/nano-banana-pro
Google's state of the art image generation and editing model 🍌🍌
Updated 1 week, 4 days ago
37.9M runs
 google/nano-banana-2.1
Google's fast image generation and editing model, with sharp text rendering, multi-image editing, and up to 4K output.
Updated 1 week, 4 days ago
1.6M runs
 krea/krea-3
Krea 3 is a fast image editing model that follows plain-language instructions. It also generates images from text.
Updated 1 week, 5 days ago
28.2K runs
prunaai/p-video-2-pro-referencePruna's reference-to-video model, built on MiniMax H3. Generate 5 to 15 second video from a prompt plus up to 9 images, 3 videos, and 3 audio clips, with speed and cost modes.
Updated 1 week, 5 days ago
197.9K runs
bria/video-erase-objectA high-fidelity capability for erasing unwanted objects, people, or visual elements from videos while maintaining aesthetic quality and temporal consistency
Updated 1 week, 5 days ago
2.9K runs
 heygen/video-translate
Translate videos into over 150 languages
Updated 1 week, 5 days ago
25.2K runs
 lightricks/ltx-2-retake
Take any shot and edit specific sections. Rephrase, change the action, camera angles and more
Updated 1 week, 5 days ago
4.3K runs
 lightricks/ltx-2.5-fast
Fast video generation with text-to-video and image-to-video, portrait and landscape support, synchronized audio, and frame interpolation. Up to 20 seconds at 1080p, and 4K resolution.
Updated 1 week, 5 days ago
24.3K runs
lightricks/ltx-2-proDelivers high visual fidelity with fast turnaround. Great for daily content creation, marketing teams, and iterative creative workflows.
Updated 1 week, 5 days ago
25.4K runs
lightricks/ltx-2-fastIdeal for rapid ideation and mobile workflows. Perfect for creators who need instant feedback, real-time previews, or high-throughput content.
Updated 1 week, 5 days ago
91.4K runs
lightricks/audio-to-videoUse audio input with an image or prompt to generate videos
Updated 1 week, 5 days ago
2.5K runs
lightricks/ltx-2.3-proHigh-fidelity video generation with portrait support, audio-to-video, retake, and extend. Text, image, and audio-driven creation up to 4K at 50 FPS.
Updated 1 week, 5 days ago
59.7K runs
lightricks/ltx-2.3-fastLightning-fast video generation with portrait support, camera controls, and synchronized audio. Up to 20 seconds at 1080p, 4K at 50 FPS.
Updated 1 week, 5 days ago
74.8K runs
 prunaai/p-image-ideogram
P-Image-Ideogram is Pruna AI’s text-to-image model starting from 0,003$ per generation.
Updated 1 week, 6 days ago
1.8M runs
 prunaai/p-image-upscale
Fastest image upscaler in the world (<1s) supporting outputs up to 128 MP. contact Pruna AI for dedicated endpoints.
Updated 1 week, 6 days ago
4M runs
 prunaai/z-image-turbo
Z-Image Turbo is a super fast text-to-image model of 6B parameters developed by Tongyi-MAI.
Updated 1 week, 6 days ago
60.2M runs
 prunaai/p-image-edit
A sub 1 second 0.01$ multi-image editing model built for production use cases. For image generation, check out p-image here: https://replicate.com/prunaai/p-image
Updated 1 week, 6 days ago
46.8M runs
 prunaai/p-image
A sub 1 second text-to-image model built for production use cases.
Updated 1 week, 6 days ago
25M runs
 google/gemini-3.8-flash-lite-tts
Google's fast, low-cost text-to-speech model with line-by-line delivery direction, vocal bursts, and two-speaker dialogue in 100+ languages
Updated 2 weeks, 6 days ago
13.5K runs
 google/gemini-3.8-flash-tts
Google's most expressive text-to-speech model, with line-by-line delivery direction, vocal bursts, two-speaker dialogue, and 130+ languages
Updated 2 weeks, 6 days ago
56K runs
bytedance/video-upscalerUpscale and enhance video up to 4K at 60fps, with scene-aware presets for AI-generated content, short dramas, UGC, and film restoration.
Updated 3 weeks, 2 days ago
56.9K runs
 pixverse/pixverse-v6-max
PixVerse's highest-quality video model. Generate up to 15 seconds of 1080p video with synchronized audio, from text or an image.
Updated 3 weeks, 4 days ago
298 runs
 google/gemini-3-flash
Google's most intelligent model built for speed with frontier intelligence, superior search, and grounding
Updated 1 month, 1 week ago
9.4M runs
 google/gemini-3.5-flash
Google's fast multimodal model with frontier reasoning across agents, coding, and long-context tasks
Updated 1 month, 1 week ago
1.1M runs
 google/gemini-2.5-flash
Google’s hybrid “thinking” AI model optimized for speed and cost-efficiency
Updated 1 month, 1 week ago
12.2M runs
 elevenlabs/v3
The most expressive Text to Speech model
Updated 1 month, 1 week ago
212.3K runs
 black-forest-labs/flux-3-image
FLUX 3 is Black Forest Labs' text-to-image and image-editing model. Generate images from a prompt, or edit with up to 10 reference images.
Updated 1 month, 2 weeks ago
333.9K runs
 google/gemini-3.1-pro
Google's most intelligent model, with improved reasoning and a new medium thinking level
Updated 1 month, 4 weeks ago
2.9M runs
 topazlabs/video-upscale
Video Upscaling from Topaz Labs
Updated 1 month, 4 weeks ago
1.1M runs
 tencent/hunyuan-3d-3.1
3D models with texture fidelity and geometry precision
Updated 1 month, 4 weeks ago
146.1K runs
 prunaai/p-image-edit-lora
Use trained LoRAs from the https://replicate.com/prunaai/p-image-edit-trainer. Find or contribute LoRAs here: https://huggingface.co/collections/PrunaAI/p-image-edit-loras.
Updated 2 months, 1 week ago
391.7K runs
 prunaai/p-image-lora
Use trained LoRAs from the https://replicate.com/prunaai/p-image-trainer. Find or contribute LoRAs here https://huggingface.co/collections/PrunaAI/p-image-loras
Updated 2 months, 1 week ago
347.4K runs
 ibm-granite/granite-4.2-8b
Granite-4.2-8B is the mid-size reasoning model in the Granite 4.2 family. It delivers strong performance on reasoning-intensive tasks by leveraging built-in <think>...</think> chain-of-thought.
Updated 2 months, 1 week ago
197.5K runs
 google/gemini-omni-1.1
Google's fast multimodal video generation and editing model with native audio, using the Interactions API
Updated 2 months, 2 weeks ago
28K runs
 recraft-ai/recraft-v4-styles-pro
Recraft V4 Styles Pro generates 2K raster images that match a reusable style or attached reference images. Built for print-ready, style-consistent assets.
Updated 2 months, 2 weeks ago
326 runs
 black-forest-labs/flux-video-upscale
Upscale videos to higher resolution with FLUX super-resolution. Precise mode sharpens and stays faithful to the source; creative mode restores and invents fine detail.
Updated 2 months, 3 weeks ago
935 runs
 prunaai/p-image-try-on
Virtual try-on. Put one or more garments onto a person photo while keeping their face, pose, and body.
Updated 3 months ago
216.9K runs
 anthropic/claude-sonnet-5
Anthropic's most agentic Sonnet model, bringing frontier-level coding and tool use at Sonnet's speed and price
Updated 3 months ago
532.8K runs
black-forest-labs/flux-3Generate video with synchronized audio from text, images, or video. FLUX 3 is Black Forest Labs' multimodal model (early access preview).
Updated 3 months ago
52.5K runs
 elevenlabs/dubbing
Translate audio and video into 90+ languages while preserving each speaker's voice, emotion, and timing
Updated 3 months, 1 week ago
1.1K runs
 google/nano-banana-2
Google's fast image generation model with conversational editing, multi-image fusion, and character consistency
Updated 3 months, 3 weeks ago
22.4M runs
 leonardoai/lucid-origin
Artistic and high-quality visuals with improved prompt adherence, diversity, and definition
Updated 3 months, 4 weeks ago
301.6K runs
 sync/lipsync-2-pro
Studio-grade lipsync in minutes, not weeks
Updated 4 months ago
97.5K runs
sync/lipsync-2Generate realistic lipsyncs with Sync Labs' 2.0 model
Updated 4 months ago
65.2K runs
 google/nano-banana-2-lite
Google's fastest image generation model — the lightweight, low-cost version of Nano Banana 2, for rapid creation and editing
Updated 4 months, 1 week ago
2.3M runs
 veed/fabric-1.0
VEED Fabric 1.0 is an image-to-video API that turns any image into a talking video
Updated 4 months, 3 weeks ago
75.6K runs
bytedance/seedance-2.0-miniA lower-cost variant of Seedance 2.0 for high-volume video generation with multimodal inputs and native audio.
Updated 4 months, 3 weeks ago
125.6K runs
 google/gemini-3.1-flash-tts
Google's fast, expressive text-to-speech model with 30 voices and 70+ language support
Updated 4 months, 3 weeks ago
2.1M runs
 google/gemini-3-pro
Google's most advanced reasoning Gemini model
Updated 4 months, 3 weeks ago
1.4M runs
 sourceful/riverflow-v2.5-pro
Top-quality agentic image model with multi-step reasoning, candidate scoring, and adjustable thinking effort
Updated 5 months ago
5.4K runs
 sourceful/riverflow-v2.5-fast
Speed-optimized variant of Riverflow 2.5 for production and latency-sensitive workflows
Updated 5 months ago
2.5K runs
 luma/ray-3.2
Luma's reasoning video model. Generates cinematic 5s or 10s video from text or images, with native HDR and EXR export for professional production pipelines.
Updated 5 months ago
5.6K runs
 anthropic/claude-fable-5
Claude Fable 5 from Anthropic: the next generation of intelligence for the hardest knowledge work and coding problems.
Updated 5 months ago
43.5K runs
 ideogram-ai/ideogram-v4-balanced
Balance speed, quality and cost. Ideogram v4 creates images with stunning realism, creative designs, and consistent styles
Updated 5 months, 1 week ago
12.3K runs
 ideogram-ai/ideogram-v4-quality
The highest quality Ideogram v4 model. v4 creates images with stunning realism, creative designs, and consistent styles
Updated 5 months, 1 week ago
28.9K runs
 runwayml/aleph-2
Edit one frame to update an entire video. Aleph 2.0 is Runway's in-context video editor: longer clips (up to 30s), multi-shot edits, and image-level precision via keyframe references.
Updated 5 months, 1 week ago
10.8K runs
 krea/krea-2-large
Krea's flagship foundation image model. Larger and more flexible than Krea 2 Medium, with particular strength in photorealism and expressive artistic styles.
Updated 5 months, 2 weeks ago
35.9K runs
 krea/krea-2-medium
Krea's foundation image model, tuned for expressive illustration, anime, and painterly styles, with consistent results across artistic directions.
Updated 5 months, 2 weeks ago
44.2K runs
 anthropic/claude-sonnet-4.6
Claude Sonnet 4.6 from Anthropic: a full upgrade to coding, computer use, long-context reasoning, agent planning, knowledge work, and design, with a 1 million token context window in beta.
Updated 5 months, 2 weeks ago
225.9K runs
 ibm-granite/granite-vision-4.1-4b
Granite Vision 4.1 4B is a vision-language model (VLM) that delivers frontier-level performance on structured document extraction tasks — chart extraction, table extraction, and semantic key-value pair extraction — in a compact 4B parameter footprint
Updated 5 months, 2 weeks ago
45.4K runs
 ibm-granite/granite-speech-4.1-2b
Granite Speech 4.1 2B is a compact and efficient speech-language model, specifically designed for multilingual automatic speech recognition (ASR) and bidirectional automatic speech translation (AST) for English, French, German, Spanish, Portuguese and Jap
Updated 5 months, 2 weeks ago
2.6K runs
 ibm-granite/granite-4.1-8b
Granite-4.1-8B is a 8B parameter long-context instruct model finetuned from Granite-4.1-8B-Base using a combination of open source instruction datasets with permissive license and internally collected synthetic datasets.
Updated 5 months, 2 weeks ago
213.1K runs
 heygen/avatar-v
Create realistic talking avatar videos from text with HeyGen's Avatar V engine — the newest, highest-quality avatar engine with cross-reference-driven animation.
Updated 5 months, 4 weeks ago
404 runs
 qwen/qwen3-tts
A unified Text-to-Speech demo featuring three powerful modes: Voice, Clone and Design
Updated 6 months, 1 week ago
3.2M runs
 elevenlabs/scribe-v2
Transcribe speech with ElevenLabs Scribe v2. 90+ languages, word-level timestamps, speaker diarization for up to 32 speakers, audio event tagging, and keyterm biasing. Files up to 3 GB and 10 hours.
Updated 6 months, 1 week ago
951.8K runs
 inworld/realtime-tts-2
Inworld's most expressive text-to-speech model, with natural-language steering, real-time latency, and support for more than 100 languages.
Updated 6 months, 1 week ago
125.5K runs
 black-forest-labs/flux-1.1-pro-ultra
FLUX1.1 [pro] in ultra and raw modes. Images are up to 4 megapixels. Use raw mode for realism.
Updated 6 months, 1 week ago
21.5M runs
 black-forest-labs/flux-2-flex
Max-quality image generation and editing with support for ten reference images
Updated 6 months, 1 week ago
504K runs
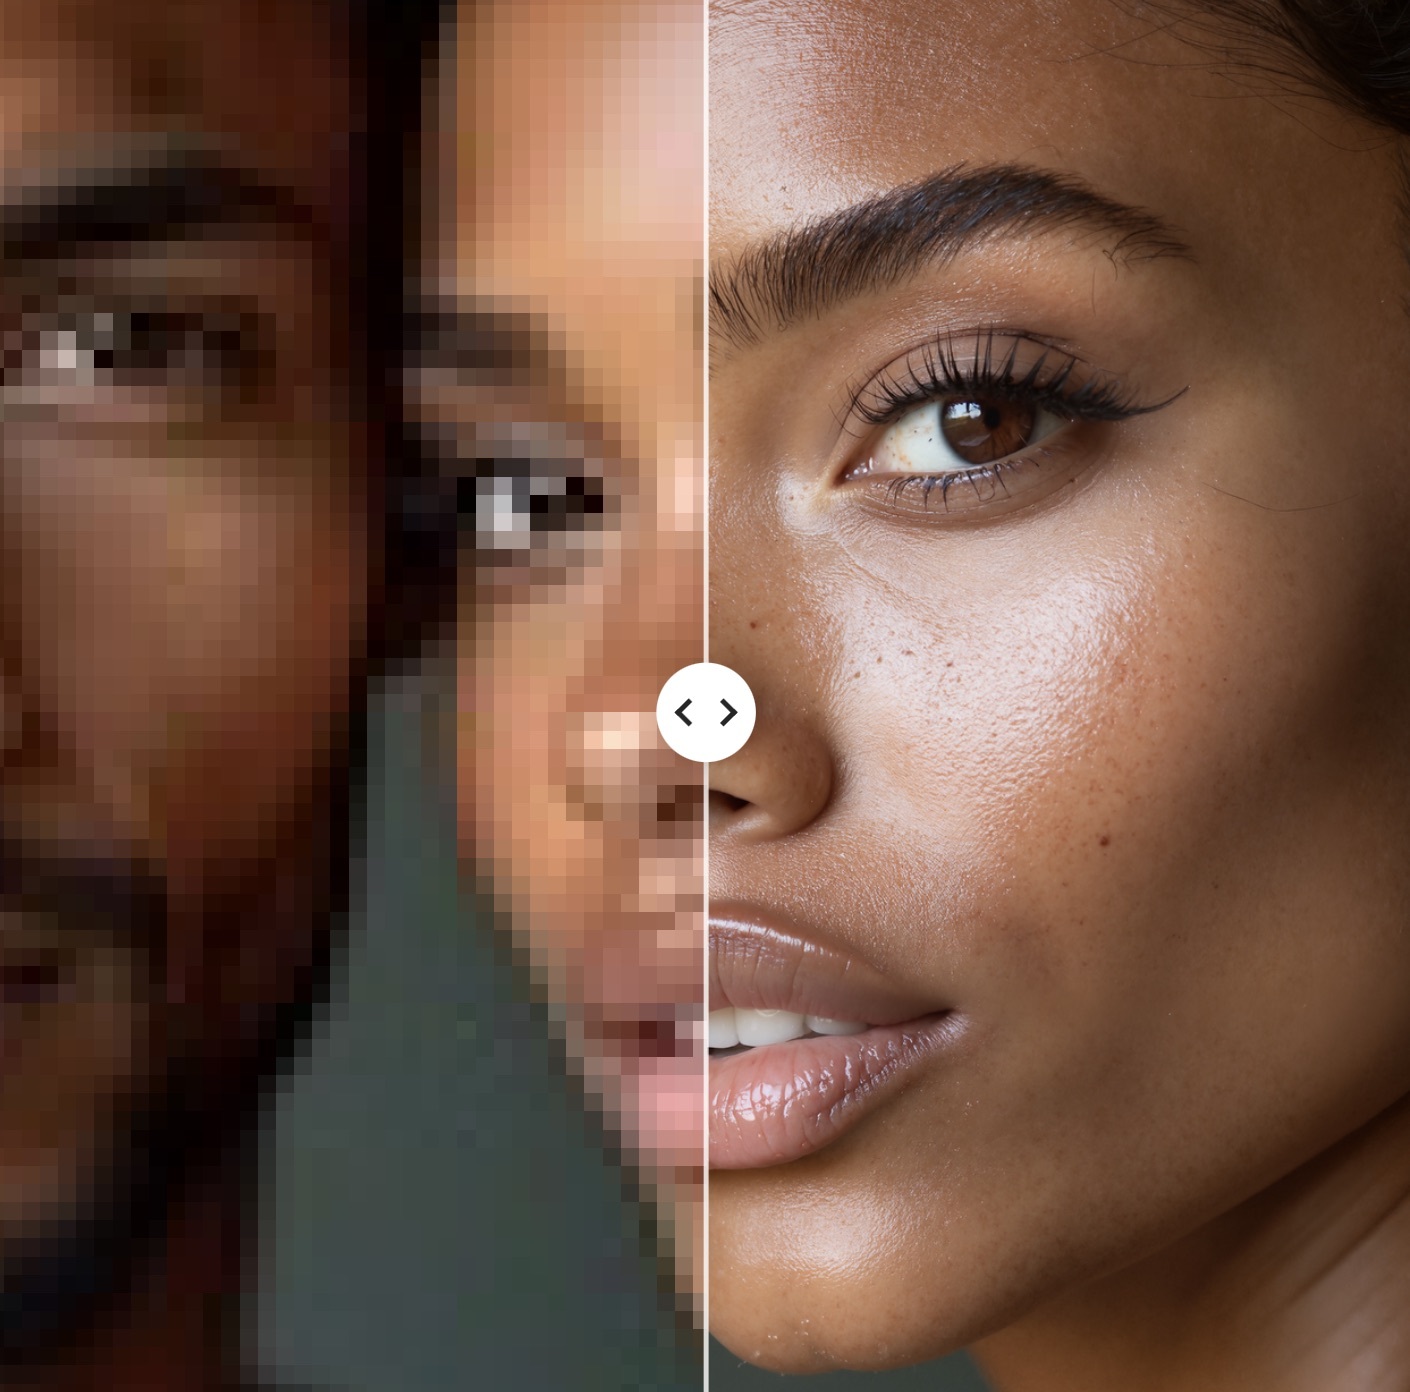
 philz1337x/clarity-pro-upscaler
The first creative upscaler which keeps identity. Stunning photorealistic results, realistic skin, and full creative control.
Updated 6 months, 2 weeks ago
44.7K runs
 xai/grok-speech-to-text
Transcribe audio to text with xAI's Grok. Handles 25 languages, word-level timestamps, speaker diarization, multichannel audio, and files up to 500 MB.
Updated 6 months, 2 weeks ago
23.2K runs
 ibm-granite/granite-embedding-small-english-r2
Granite-embedding-small-english-r2 is a 47M parameter dense biencoder embedding model from the Granite Embeddings collection that can be used to generate high quality text embeddings.
Updated 6 months, 3 weeks ago
474 runs
 moonshotai/kimi-k2.6
Moonshot AI's frontier open model, built for long-horizon coding, agent swarms, and autonomous software engineering. 1 trillion parameters, 262k context window, vision and tool use.
Updated 6 months, 3 weeks ago
99.3K runs
pixverse/pixverse-v6PixVerse's flagship video generation model. Generate cinematic videos with synchronized audio, multi-shot sequences, and precise camera control.
Updated 6 months, 3 weeks ago
139.2K runs
Generate high-fidelity SVG graphics from text prompts with Quiver's Arrow 1.1 Max model. Tuned for dense illustrations, detailed logos, and technical diagrams.
Updated 6 months, 3 weeks ago
342 runs
Generate editable SVG graphics from text prompts with Quiver's Arrow 1.1 model. Great for icons, logos, and illustrations.
Updated 6 months, 3 weeks ago
298 runs
Convert raster images (PNG, JPEG, WebP) into clean SVGs with Quiver's Arrow 1.1 vectorization model. Great for turning logos and icons into editable vectors.
Updated 6 months, 3 weeks ago
106 runs
Convert complex raster images into high-fidelity SVGs with Quiver's Arrow 1.1 Max vectorization model. Tuned for detailed images where fine structure and alignment matter.
Updated 6 months, 3 weeks ago
162 runs
 minimax/speech-02-hd
Text-to-Audio (T2A) that offers voice synthesis, emotional expression, and multilingual capabilities. Optimized for high-fidelity applications like voiceovers and audiobooks.
Updated 6 months, 3 weeks ago
3.3M runs
 minimax/speech-2.6-hd
MiniMax Speech 2.6 HD delivers studio-quality multilingual text-to-audio on Replicate with nuanced prosody, subtitle export, and premium voices
Updated 6 months, 3 weeks ago
266.1K runs
 minimax/speech-02-turbo
Text-to-Audio (T2A) that offers voice synthesis, emotional expression, and multilingual capabilities. Designed for real-time applications with low latency
Updated 6 months, 3 weeks ago
13.2M runs
 minimax/speech-2.8-hd
Minimax Speech 2.8 HD focuses on high-fidelity audio generation with features like studio-grade quality, flexible emotion control, multilingual support, and voice cloning capabilities
Updated 6 months, 3 weeks ago
526.4K runs
 minimax/speech-2.6-turbo
Low‑latency MiniMax Speech 2.6 Turbo brings multilingual, emotional text-to-speech to Replicate with 300+ voices and real-time friendly pricing
Updated 6 months, 3 weeks ago
1.4M runs
 minimax/speech-2.8-turbo
Minimax Speech 2.8 Turbo: Turn text into natural, expressive speech with voice cloning, emotion control, and support for 40+ languages
Updated 6 months, 3 weeks ago
2.4M runs
 google/gemini-2.5-flash-image
Google's latest image generation model in Gemini 2.5
Updated 6 months, 4 weeks ago
1.4M runs
 uthana/text-to-motion-diffusion-v2
Generate 3D character animation data from a text prompt
Updated 6 months, 4 weeks ago
1.4K runs
 uthana/text-to-motion-vqvae-v1
Generate 3D character animation data from a text prompt
Updated 6 months, 4 weeks ago
88 runs
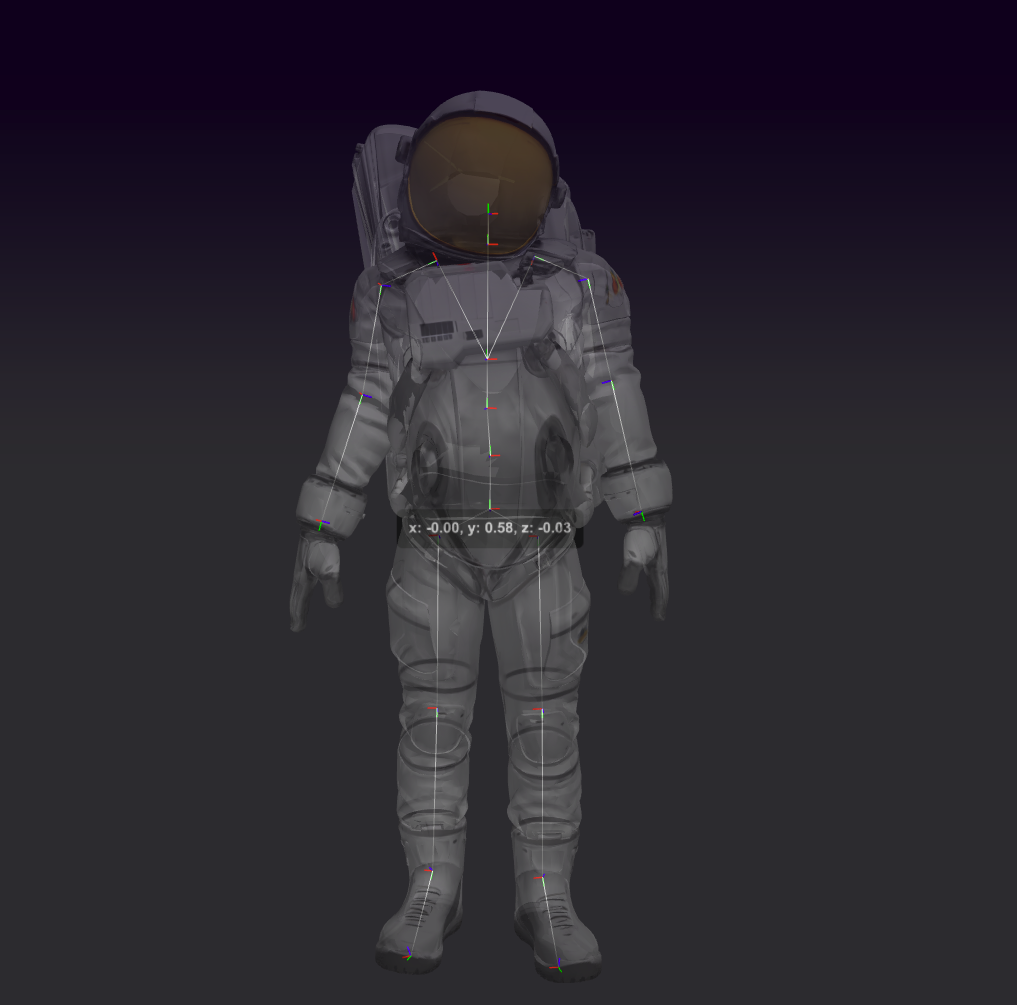 uthana/create-character-v1
Rig any 3D bipedal character mesh
Updated 6 months, 4 weeks ago
1.3K runs
heygen/video-agentTurn a text prompt into a complete, polished video with AI-generated script, avatar presenter, voiceover, visuals, and editing.
Updated 6 months, 4 weeks ago
1.5K runs
 heygen/lipsync-speed
Fast lip-sync: replace or dub audio on any video with quick audio-driven lip sync
Updated 6 months, 4 weeks ago
3.2K runs
 heygen/lipsync-precision
High-accuracy lip-sync: replace or dub audio on any video with avatar-inference lip sync
Updated 6 months, 4 weeks ago
19.1K runs
heygen/avatar-ivCreate realistic talking avatar videos from text with HeyGen's Avatar IV engine
Updated 6 months, 4 weeks ago
727 runs
 anthropic/claude-opus-4.7
Anthropic's most capable model, with large gains in agentic coding, better vision, and stronger multi-step reasoning.
Updated 6 months, 4 weeks ago
626.1K runs
 inworld/realtime-tts-1.5-max
Highest-quality realtime text-to-speech with <200ms latency, emotion control, and 15-language support
Updated 6 months, 4 weeks ago
333K runs
 inworld/realtime-tts-1.5-mini
Ultra-fast, cost-efficient realtime text-to-speech with ~120ms latency and 15-language support
Updated 6 months, 4 weeks ago
188.4K runs
 black-forest-labs/flux-fill-pro
Professional inpainting and outpainting model with state-of-the-art performance. Edit or extend images with natural, seamless results.
Updated 7 months ago
4.3M runs
 vidu/q3-pro
High-fidelity video generation with text-to-video, image-to-video, and start-end-to-video modes. Up to 16 seconds at 1080p with synchronized audio.
Updated 7 months ago
7K runs
vidu/q3-turboFast video generation with text-to-video, image-to-video, and start-end-to-video modes. Up to 16 seconds at 1080p with synchronized audio.
Updated 7 months ago
6K runs
 luma/reframe-image
Change the aspect ratio of any photo using AI (not cropping)
Updated 7 months ago
354.7K runs
 decart/lucy-edit-2
Edit and transform videos with text prompts and reference images. Style transfers, object replacement, character transformation, and more.
Updated 7 months ago
756 runs
 prunaai/hidream-l1-fast
This is an optimised version of the hidream-l1 model using the pruna ai optimisation toolkit!
Updated 7 months, 1 week ago
8.6M runs
 ideogram-ai/layerize
Take a flat graphic, remove text, and get structured text layers back for editing and recomposing
Updated 7 months, 1 week ago
7.1K runs
google/veo-3.1-fastNew and improved version of Veo 3 Fast, with higher-fidelity video, context-aware audio and last frame support
Updated 7 months, 3 weeks ago
895.8K runs
google/veo-3.1New and improved version of Veo 3, with higher-fidelity video, context-aware audio, reference image and last frame support
Updated 7 months, 3 weeks ago
683.5K runs
 black-forest-labs/flux-2-pro
High-quality image generation and editing with support for eight reference images
Updated 7 months, 3 weeks ago
12.6M runs
 black-forest-labs/flux-2-max
The highest fidelity image model from Black Forest Labs
Updated 7 months, 4 weeks ago
4.3M runs
 qwen/qwen-image-2-pro
The pro version of Qwen Image 2 from Alibaba's Qwen team. Enhanced text rendering, realism, and semantic adherence for high-quality image generation and editing.
Updated 8 months, 1 week ago
75.2K runs
 ibm-granite/granite-4.0-h-small
Granite-4.0-H-Small is a 32B parameter long-context instruct model finetuned from Granite-4.0-H-Small-Base using a combination of open source instruction datasets with permissive license and internally collected synthetic datasets.
Updated 8 months, 3 weeks ago
252.1K runs
 bytedance/seedream-5-lite
Seedream 5.0 lite is ByteDance's image model with built-in reasoning, example-based editing, and deep domain knowledge.
Updated 8 months, 3 weeks ago
3.6M runs
runwayml/gen-4.5State-of-the-art video motion quality, prompt adherence and visual fidelity
Updated 8 months, 4 weeks ago
499.5K runs
kwaivgi/kling-o1Modify an existing video through natural-language commands, changing subjects, environments, and visual style while preserving the original motion and timing.
Updated 9 months ago
24K runs
 prunaai/p-image-trainer
Fast LoRA trainer for p-image, a super fast text-to-image model developed by Pruna AI. Use LoRAs here: https://replicate.com/prunaai/p-image-lora. Find or contribute LoRAs here: https://huggingface.co/collections/PrunaAI/p-image
Updated 9 months ago
537 runs
bria/video-remove-backgroundAutomatically remove backgrounds from videos -perfect for creating clean, professional content without a green screen.
Updated 9 months ago
8.3K runs
bria/video-increase-resolutionUpscale videos up to 8K output resolution. Trained on fully licensed and commercially safe data.
Updated 9 months ago
427 runs
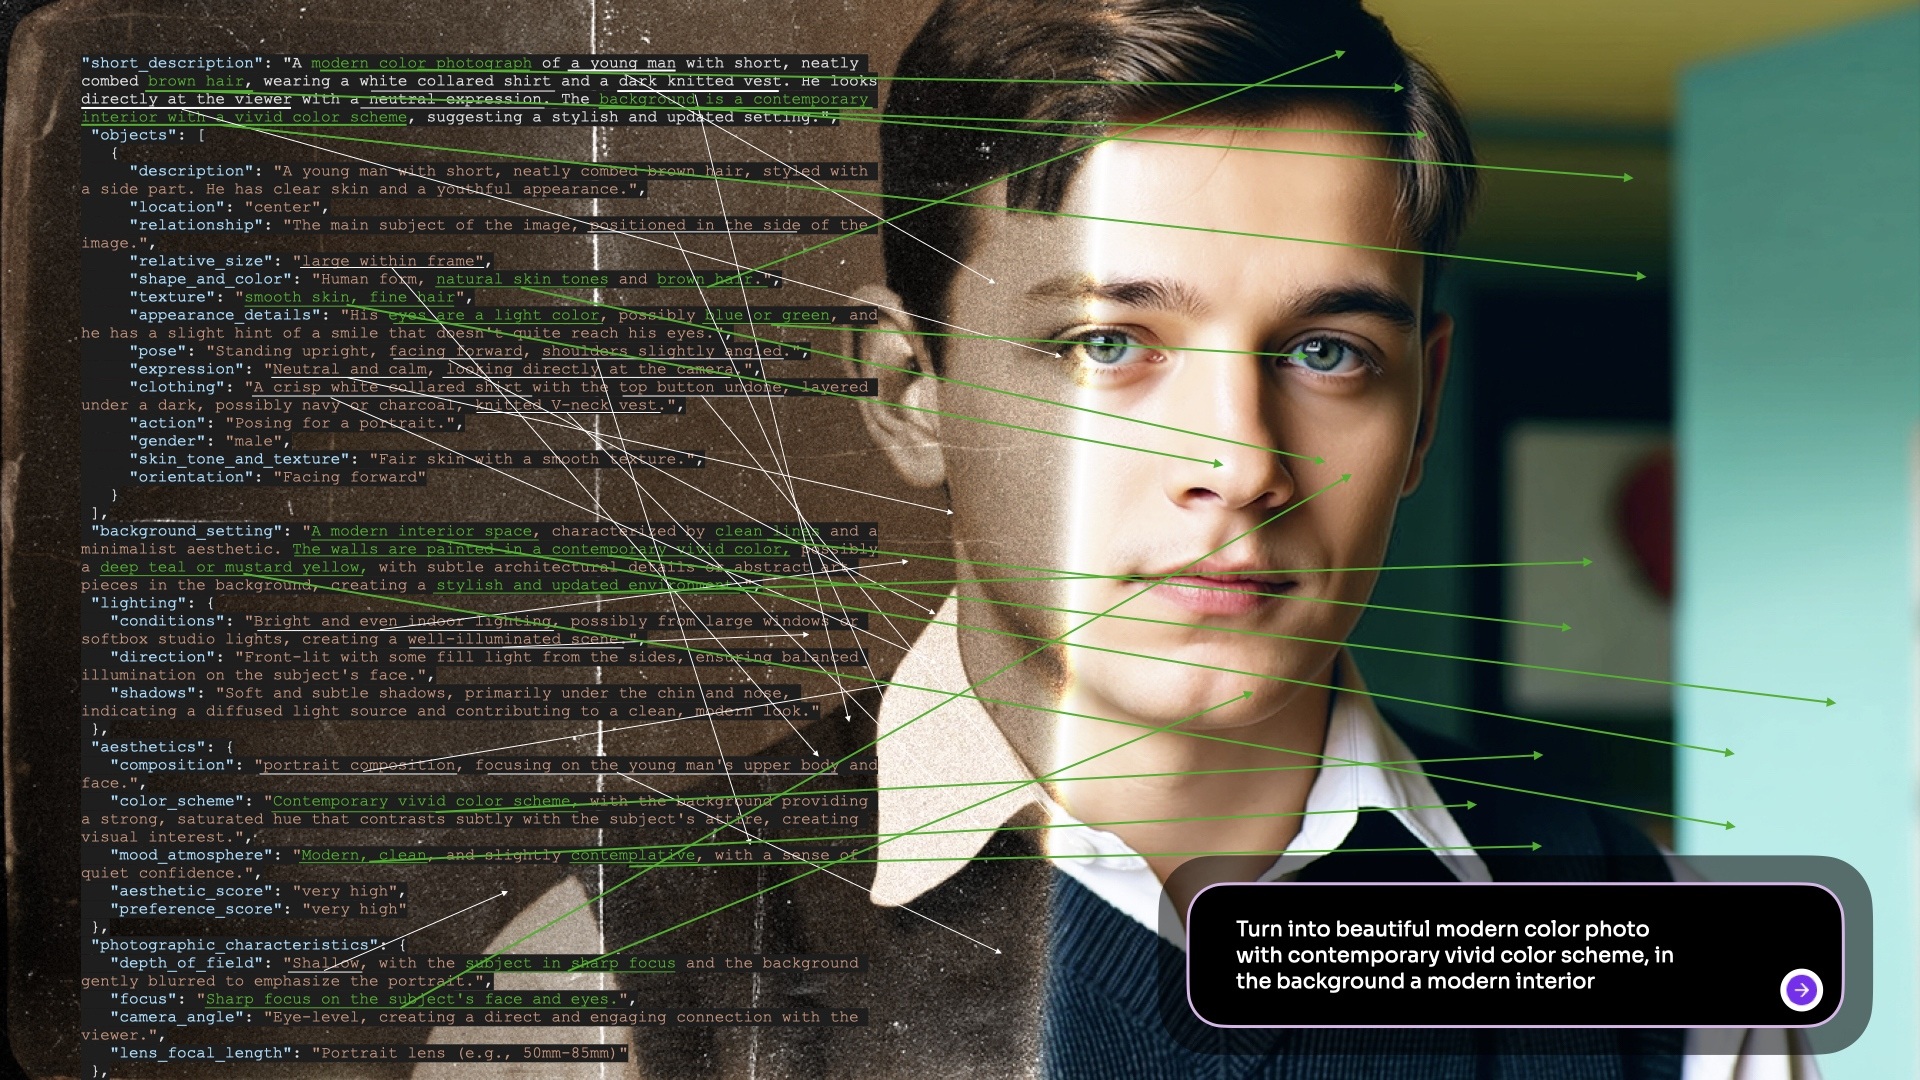 bria/fibo-edit
FIBO-Edit brings the power of structured prompt generation to image editing
Updated 9 months ago
14.4K runs
 topazlabs/dust-and-scratch-v2
Remove dust and scratches from old photos
Updated 9 months, 1 week ago
3K runs
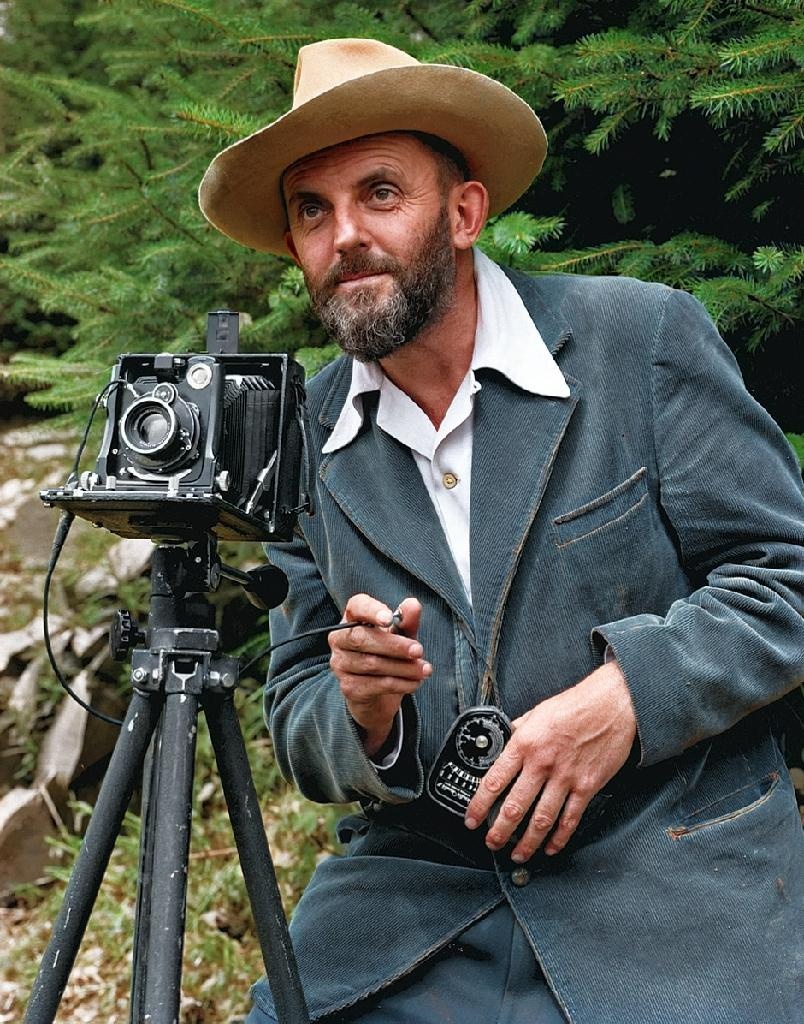 topazlabs/image-colorization
Image colorization model from Topaz Labs
Updated 9 months, 1 week ago
3.3K runs
 google/nano-banana
Google's latest image editing model in Gemini 2.5
Updated 9 months, 1 week ago
123.8M runs
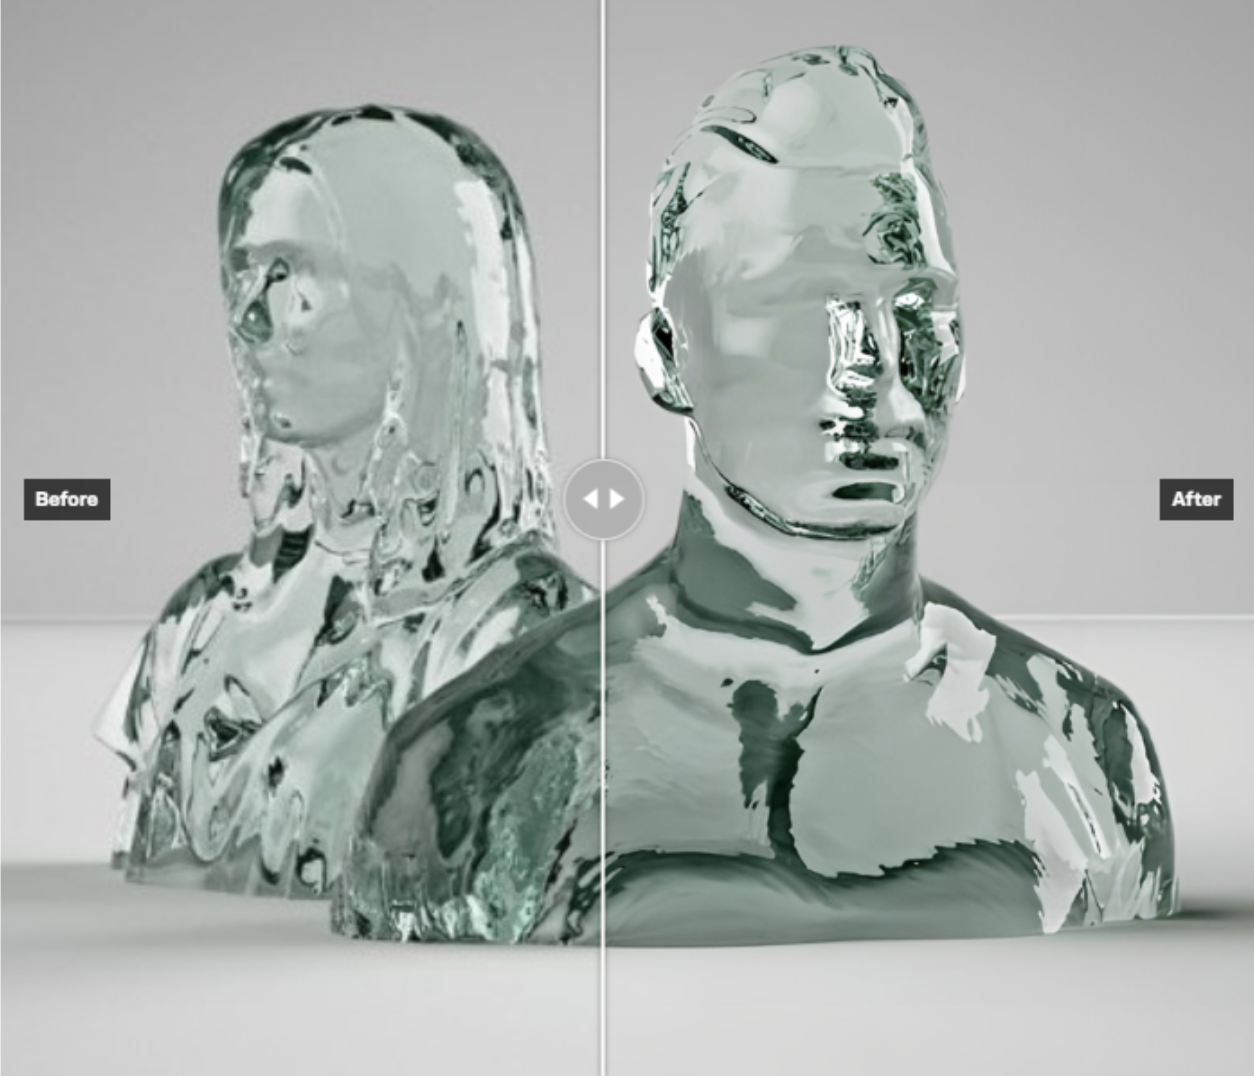 bria/increase-resolution
Bria Increase resolution upscales the resolution of any image. It increases resolution using a dedicated upscaling method that preserves the original image content without regeneration.
Updated 9 months, 1 week ago
154.8K runs
 bria/fibo
SOTA Open source model trained on licensed data, transforming intent into structured control for precise, high-quality AI image generation in enterprise and agentic workflows.
Updated 9 months, 1 week ago
15.9K runs
 bria/eraser
SOTA Object removal, enables precise removal of unwanted objects from images while maintaining high-quality outputs. Trained exclusively on licensed data for safe and risk-free commercial use
Updated 9 months, 1 week ago
671.5K runs
 bria/genfill
Bria GenFill enables high-quality object addition or visual transformation. Trained exclusively on licensed data for safe and risk-free commercial use.
Updated 9 months, 1 week ago
29.9K runs
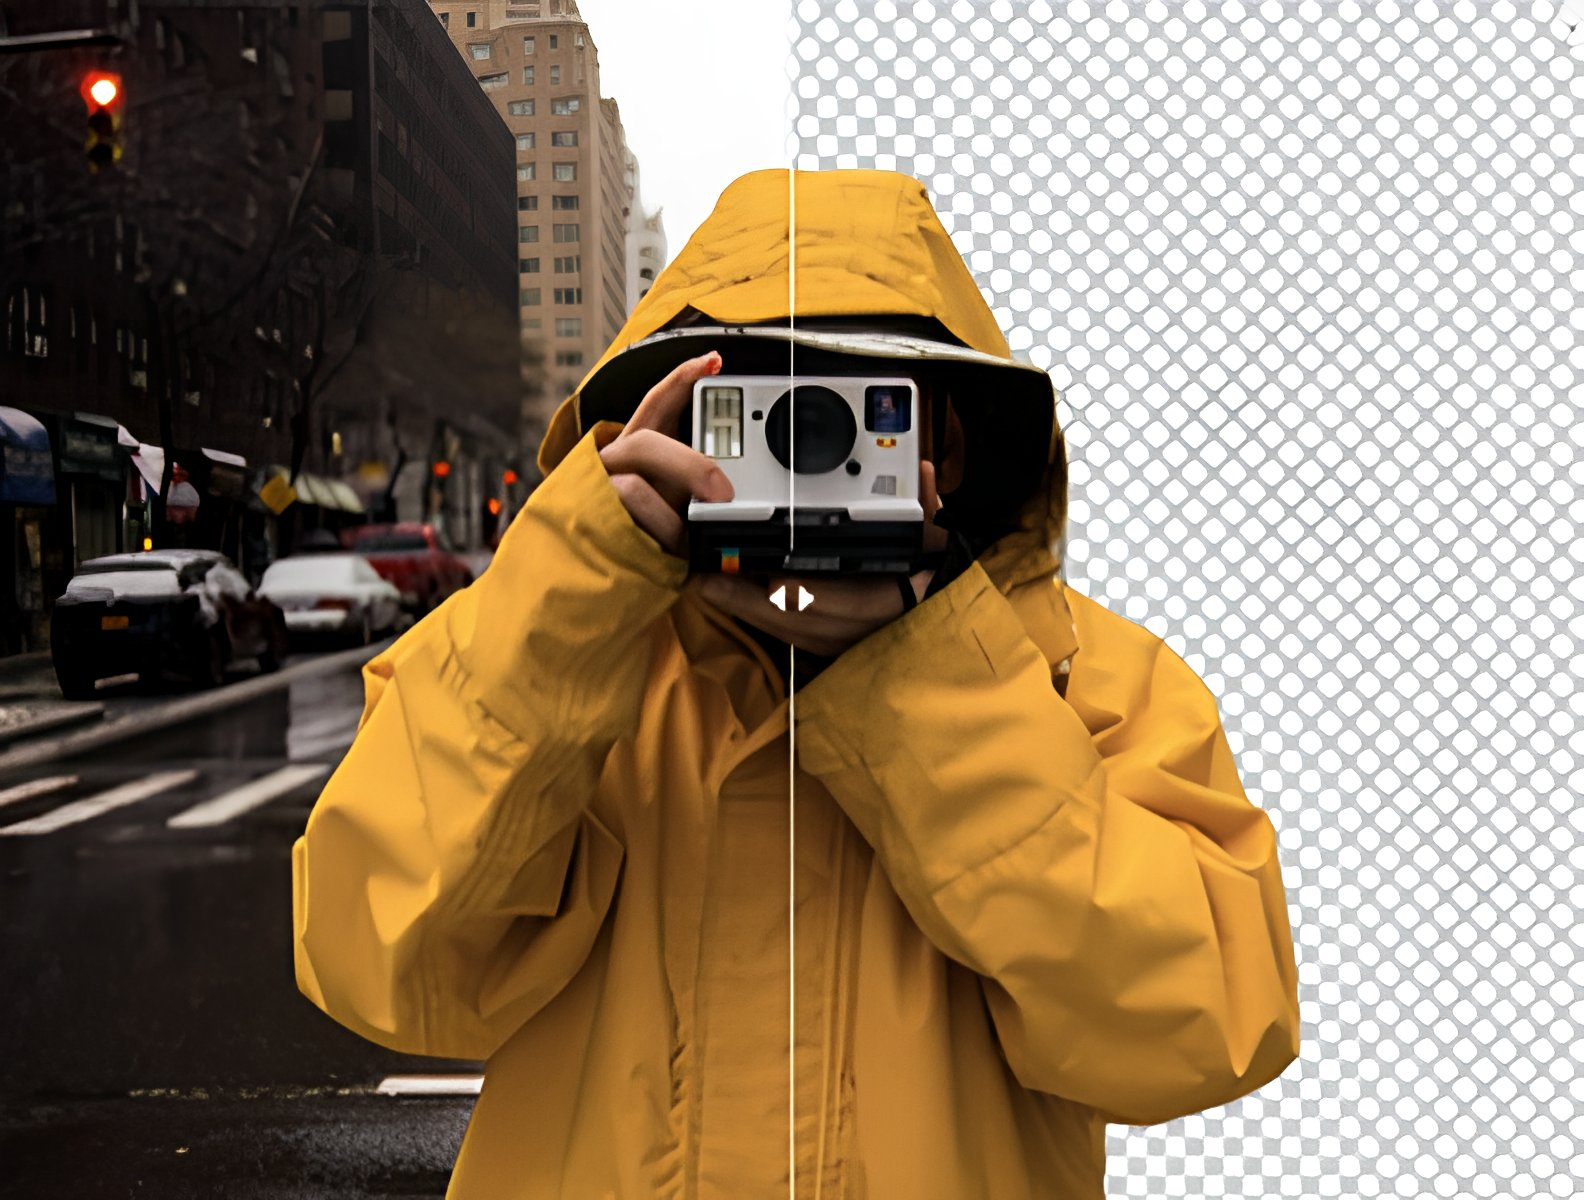 bria/remove-background
Bria AI's remove background model
Updated 9 months, 1 week ago
3.4M runs
 anthropic/claude-opus-4.6
Anthropic's most intelligent model with state-of-the-art coding, reasoning, and agentic capabilities
Updated 9 months, 1 week ago
257.3K runs
 sourceful/riverflow-2.0-pro
Agentic image model optimized for robust, high-precision generations supporting font control
Updated 9 months, 1 week ago
26.9K runs
 sourceful/riverflow-2.0-fast
Agentic image model optimized for high-quality, fast generations supporting font control
Updated 9 months, 1 week ago
11.6K runs
 sourceful/riverflow-2.0-refsr
Render product images with 100% accuracy and environmental blending
Updated 9 months, 2 weeks ago
2K runs
pixverse/pixverse-v5.6Latest video model from Pixverse with astonishing physics
Updated 9 months, 2 weeks ago
42.4K runs
wan-video/wan-2.2-animate-replaceUse Wan 2.2 Animate to replace a character in a video scene
Updated 9 months, 2 weeks ago
85.5K runs
 black-forest-labs/flux-2-klein-4b-base-lora
A version of FLUX.2 [klein] 4B-base that supports fast fine-tuned lora inference
Updated 9 months, 2 weeks ago
2.3K runs
 black-forest-labs/flux-2-klein-9b-base-lora
A version of FLUX.2 [klein] 9B-base that supports fast fine-tuned lora inference
Updated 9 months, 2 weeks ago
28.1K runs
 black-forest-labs/flux-2-klein-9b
4 step distilled version of FLUX.2 [klein]. A foundation model for maximum flexibility and control
Updated 9 months, 3 weeks ago
4.6M runs
 qwen/qwen-image
An image generation foundation model in the Qwen series that achieves significant advances in complex text rendering.
Updated 9 months, 3 weeks ago
2.1M runs
wan-video/wan-2.2-t2v-fastA very fast and cheap PrunaAI optimized version of Wan 2.2 A14B text-to-video
Updated 9 months, 4 weeks ago
363.5K runs
wan-video/wan-2.2-i2v-fastA very fast and cheap PrunaAI optimized version of Wan 2.2 A14B image-to-video
Updated 9 months, 4 weeks ago
15.3M runs
 black-forest-labs/flux-2-klein-9b-base
Un-distilled version of FLUX.2 [klein]. A foundation model for maximum flexibility and control
Updated 10 months ago
140.4K runs
 black-forest-labs/flux-2-klein-4b-base
Un-distilled version of FLUX.2 [klein]. Optimized for fine-tuning, customization, and post-training workflows
Updated 10 months ago
76.2K runs
 black-forest-labs/flux-2-klein-4b
Very fast image generation and editing model. 4 steps distilled, sub-second inference for production and near real-time applications.
Updated 10 months ago
38M runs
philz1337x/crystal-video-upscalerHigh-precision video upscaler optimized for portraits, faces and products. One of the upscale modes powered by Clarity AI. X:https://x.com/philz1337x
Updated 10 months, 1 week ago
6K runs
lightricks/ltx-2-distilledLTX-2: The first open source audio-video model
Updated 10 months, 1 week ago
35.6K runs
 qwen/qwen-image-2512
Qwen Image 2512 is an improved version of Qwen Image with more realistic human generation, finer textures, and stronger text rendering
Updated 10 months, 2 weeks ago
245.7K runs
 qwen/qwen-image-edit-2511
An enhanced version over Qwen-Image-Edit-2509, featuring multiple improvements including notably better consistency
Updated 10 months, 3 weeks ago
4.9M runs
wan-video/wan-2.6-t2vAlibaba Wan 2.6 text to video generation model
Updated 11 months ago
38.2K runs
 resemble-ai/chatterbox-turbo
The fastest open source TTS model without sacrificing quality.
Updated 11 months ago
1.5M runs
sync/react-1Realistic lipsync with refined human emotion capabilities
Updated 11 months ago
11.5K runs
 google/lyria-2
Lyria 2 is a music generation model that produces 48kHz stereo audio through text-based prompts
Updated 11 months, 3 weeks ago
177.3K runs
 black-forest-labs/flux-2-dev
Quality image generation and editing with support for reference images
Updated 11 months, 3 weeks ago
4.9M runs
 pixverse/pixverse-v4
Quickly generate smooth 5s or 8s videos at 540p, 720p or 1080p
Updated 11 months, 3 weeks ago
47.8K runs
 pixverse/pixverse-v4.5
Quickly make 5s or 8s videos at 540p, 720p or 1080p. It has enhanced motion, prompt coherence and handles complex actions well.
Updated 11 months, 3 weeks ago
275.5K runs
 pixverse/pixverse-v5
Create 5s-8s videos with enhanced character movement, visual effects, and exclusive 1080p-8s support. Optimized for anime characters and complex actions
Updated 11 months, 3 weeks ago
791.7K runs
 pixverse/pixverse-v3.5
Create videos in as little as 10 seconds. 5s or 8s videos at 360p, 540p, 720p or 1080p.
Updated 11 months, 3 weeks ago
3.3K runs
pixverse/lipsyncGenerate realistic lipsync animations from audio for high-quality synchronization
Updated 11 months, 3 weeks ago
589K runs
wan-video/wan-2.5-t2v-fastWan 2.5 text-to-video, optimized for speed
Updated 11 months, 3 weeks ago
53.5K runs
 wavespeedai/wan-2.1-t2v-720p
Accelerated inference for Wan 2.1 14B text to video with high resolution, a comprehensive and open suite of video foundation models that pushes the boundaries of video generation.
Updated 11 months, 3 weeks ago
37.7K runs
 wavespeedai/wan-2.1-i2v-720p
Accelerated inference for Wan 2.1 14B image to video with high resolution, a comprehensive and open suite of video foundation models that pushes the boundaries of video generation.
Updated 11 months, 3 weeks ago
90.5K runs
 wavespeedai/wan-2.1-i2v-480p
Accelerated inference for Wan 2.1 14B image to video, a comprehensive and open suite of video foundation models that pushes the boundaries of video generation.
Updated 11 months, 3 weeks ago
459.2K runs
 wavespeedai/qwen-image
A 20B MMDiT model for next-gen text-to-image generation
Updated 11 months, 3 weeks ago
12.3K runs
 bytedance/dreamina-3.1
4MP text-to-image generation with enhanced cinematic-quality image generation with precise style control, improved text rendering, and commercial design optimization.
Updated 11 months, 3 weeks ago
124.3K runs
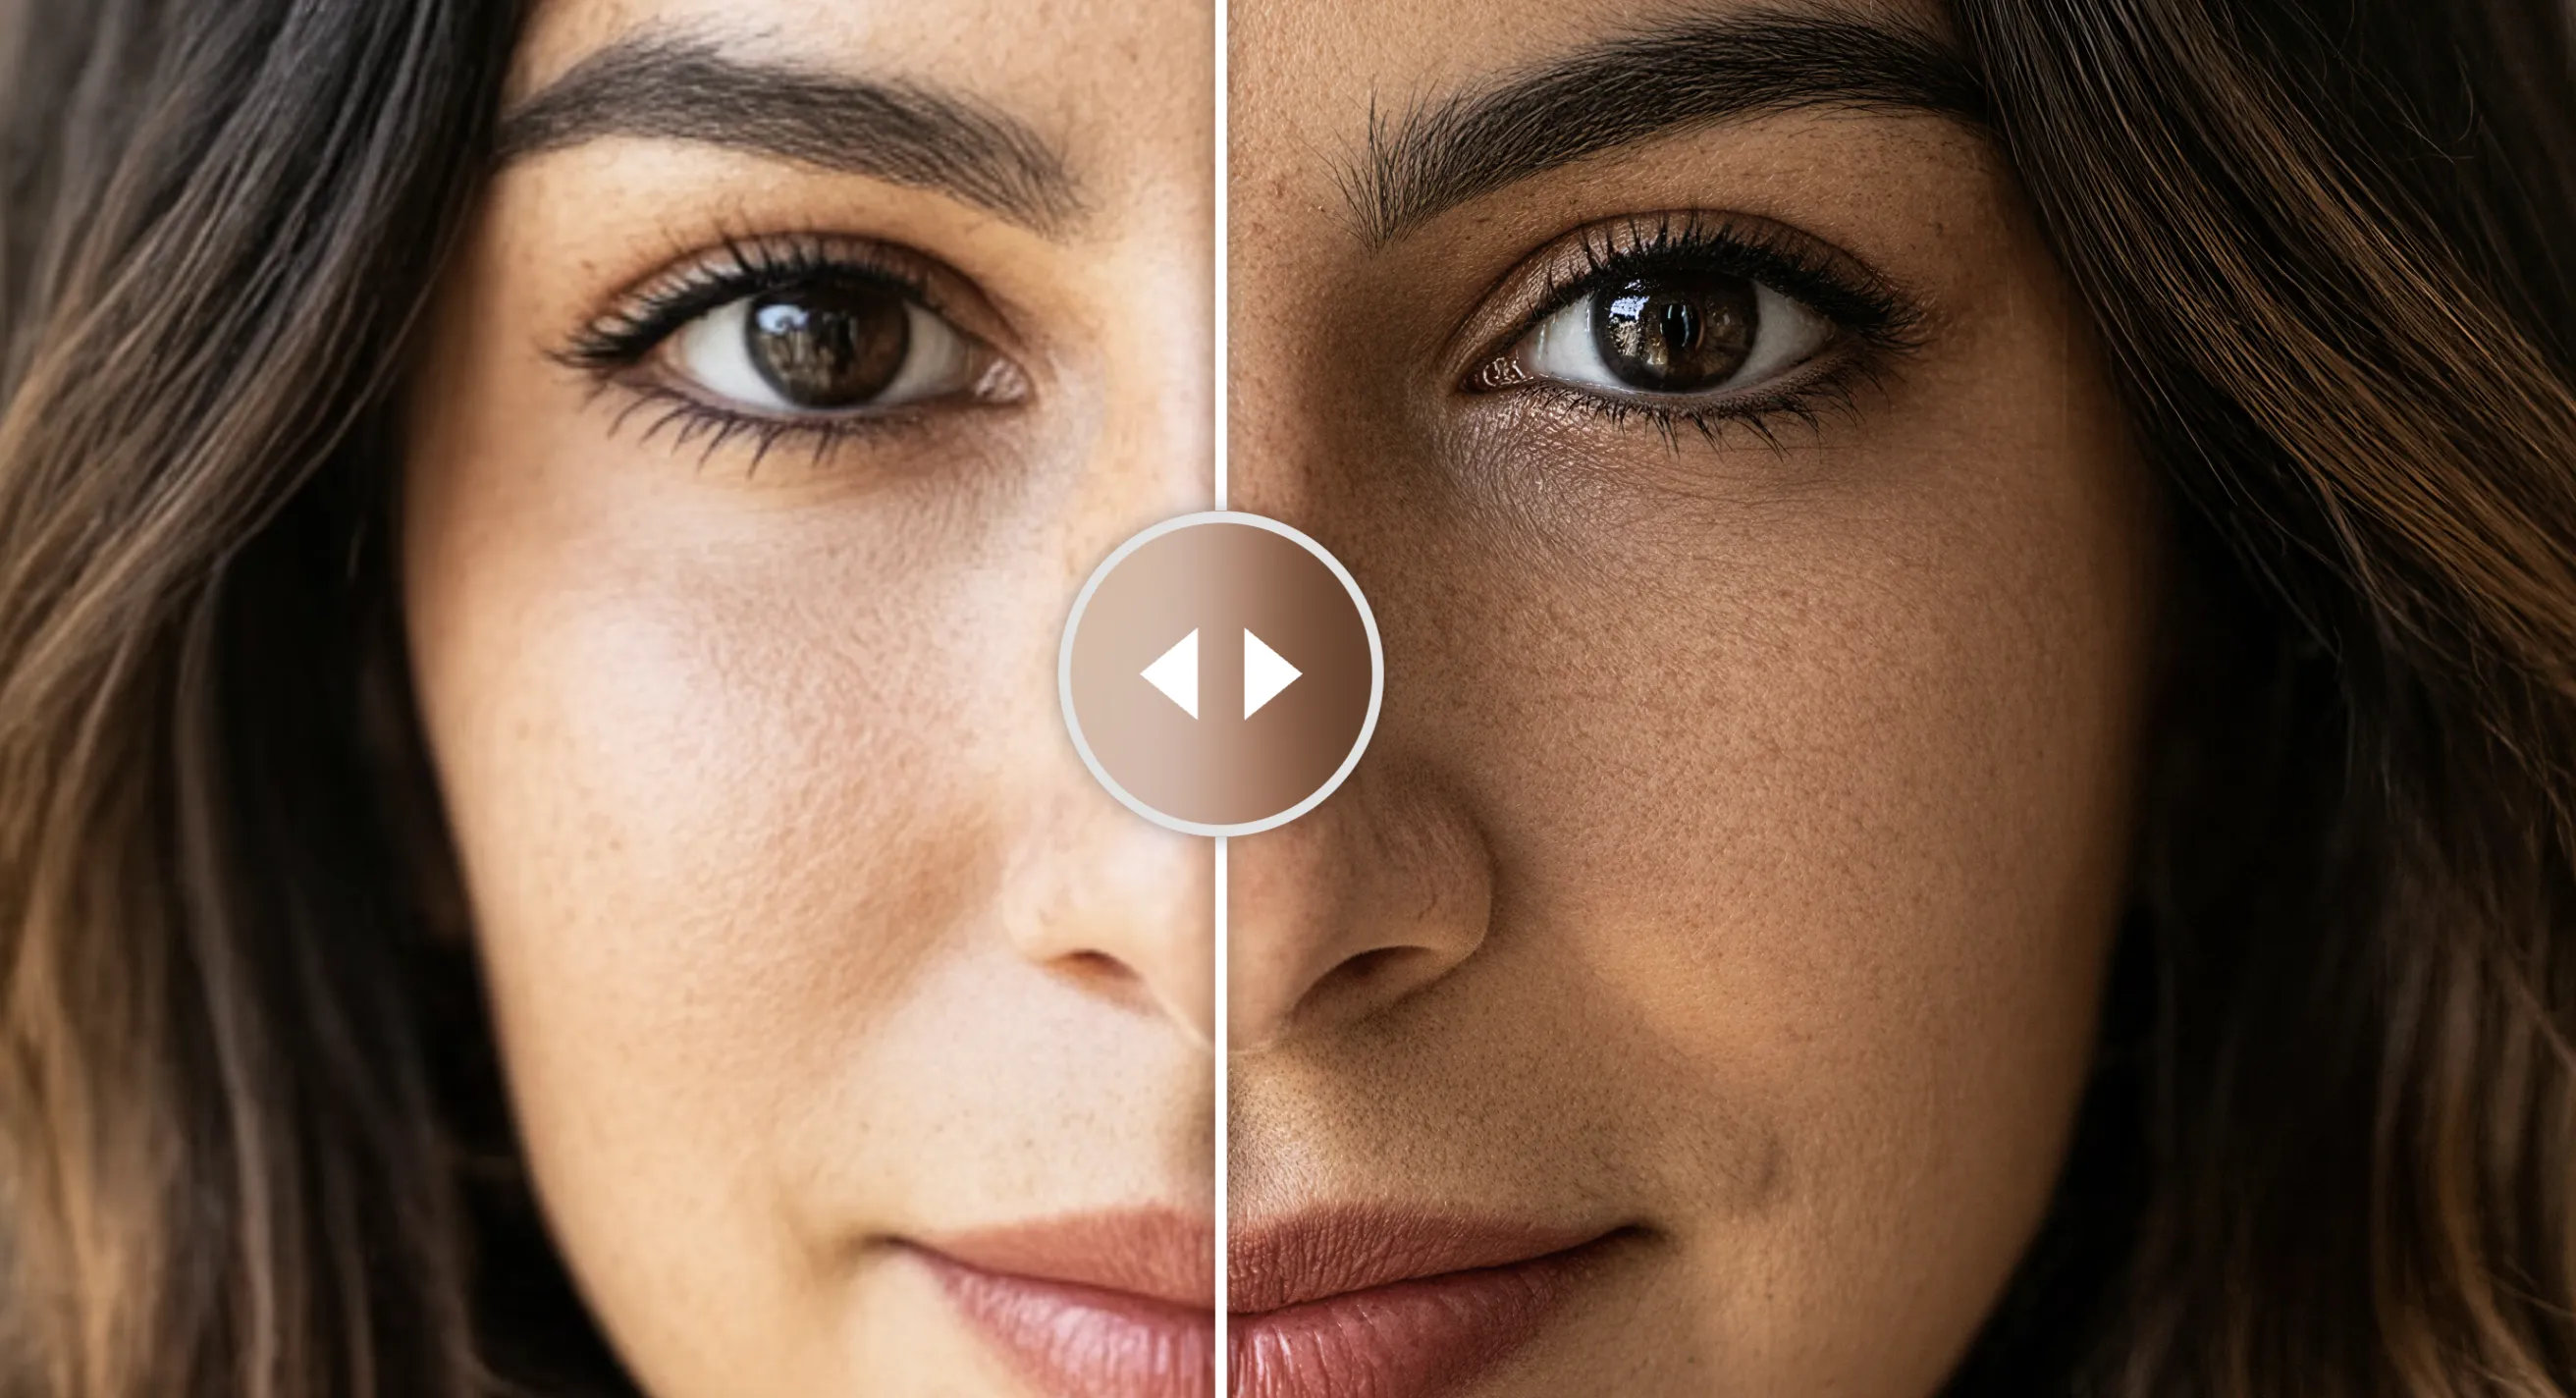 philz1337x/crystal-upscaler
Upscale without changing the original. Fastest, highest resolution and best quality on the market. Built for fashion, products and architecture.
Updated 11 months, 3 weeks ago
1.4M runs
 bytedance/seedream-4
Unified text-to-image generation and precise single-sentence editing at up to 4K resolution
Updated 11 months, 3 weeks ago
40.3M runs
 hyper3d/rodin
Generate complex 3D models from images with Rodin Gen-2
Updated 11 months, 3 weeks ago
25.4K runs
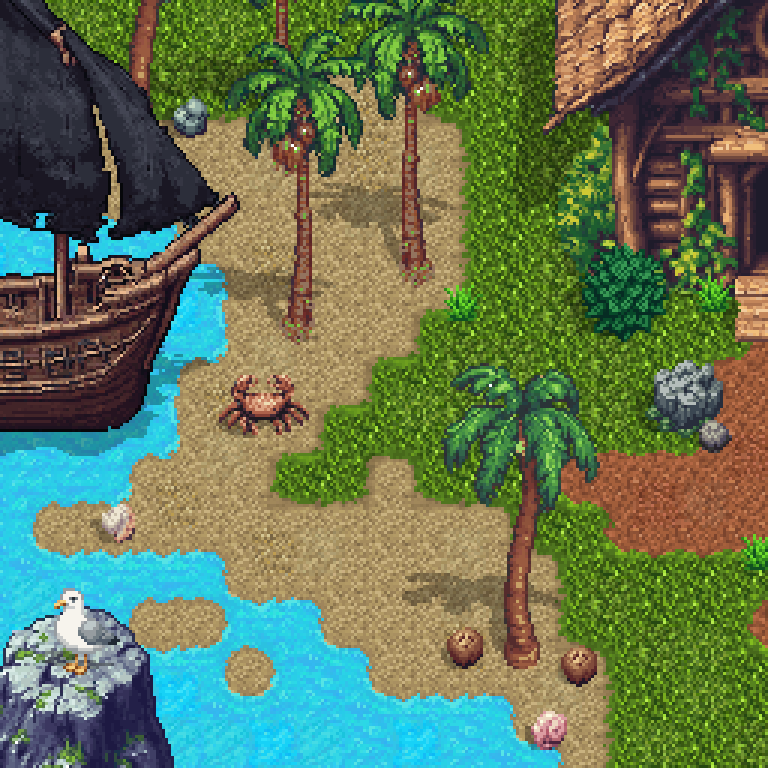
 retro-diffusion/rd-tile
All the tools you need for generating pixel art tilesets
Updated 11 months, 3 weeks ago
16.8K runs
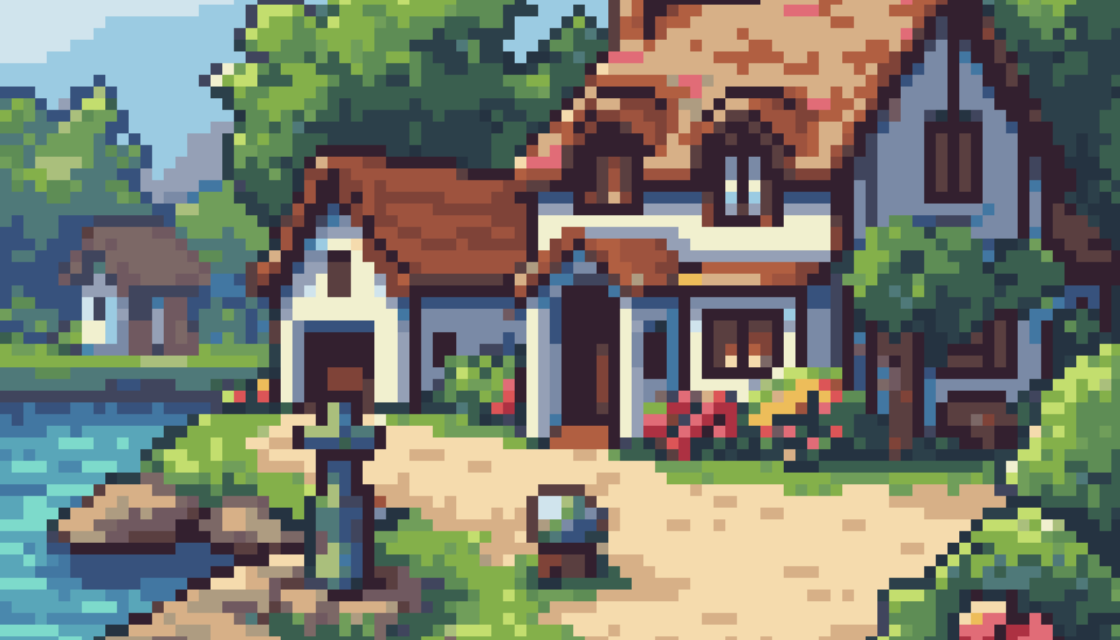 retro-diffusion/rd-plus
High quality and authentic pixel art image generation
Updated 11 months, 3 weeks ago
84.7K runs
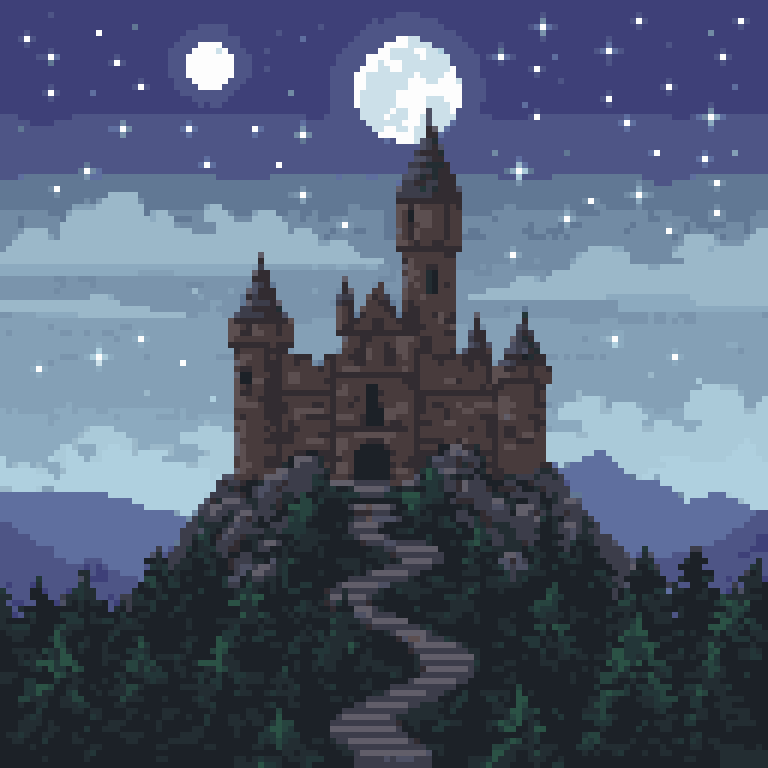 retro-diffusion/rd-fast
Fast pixel art image generation
Updated 11 months, 3 weeks ago
46.8K runs
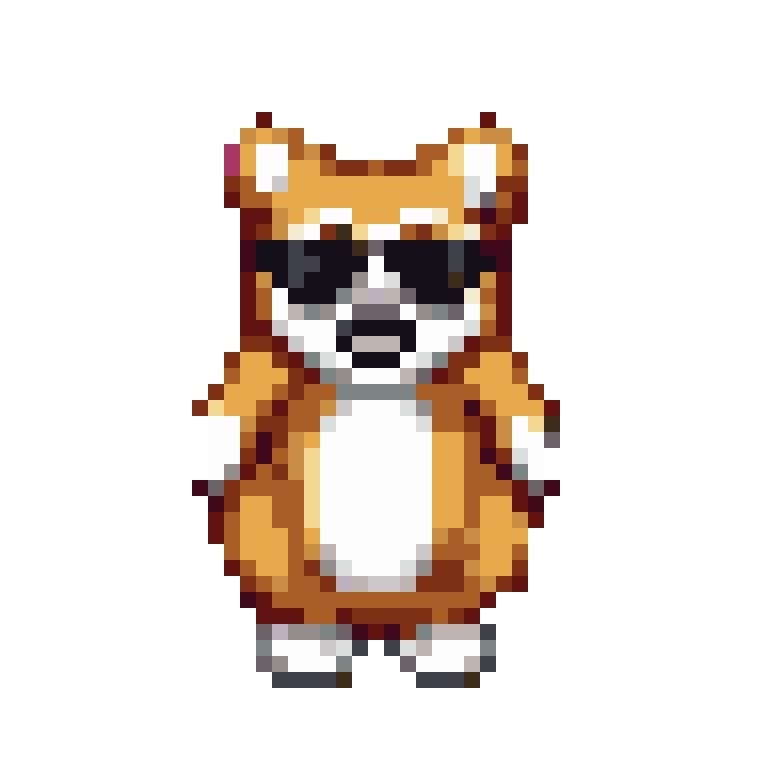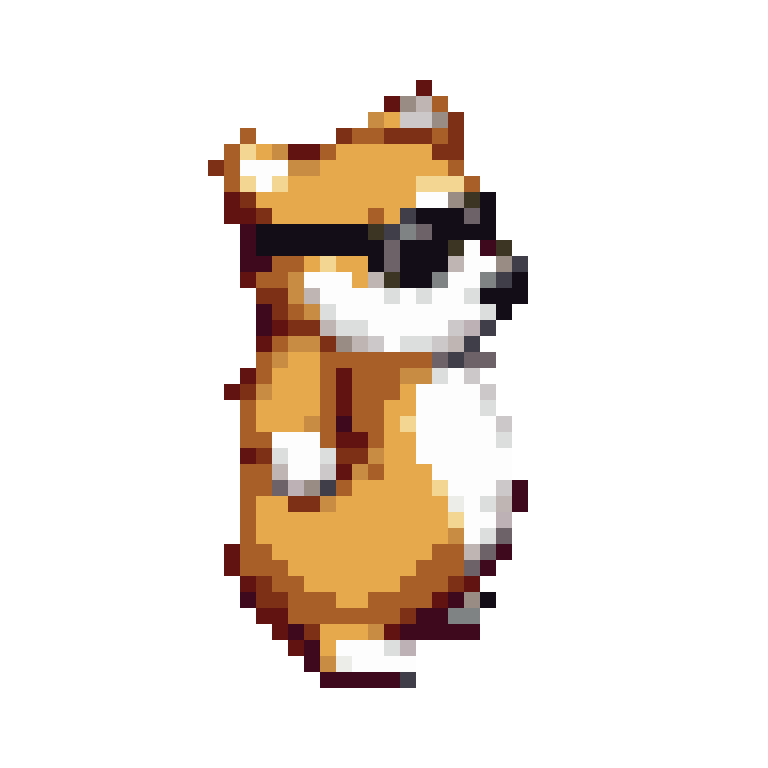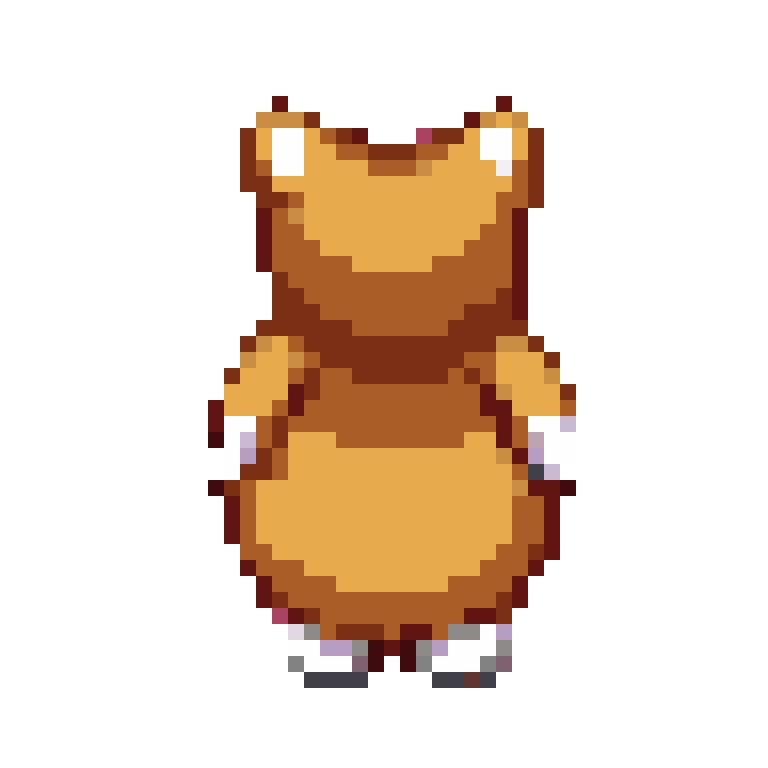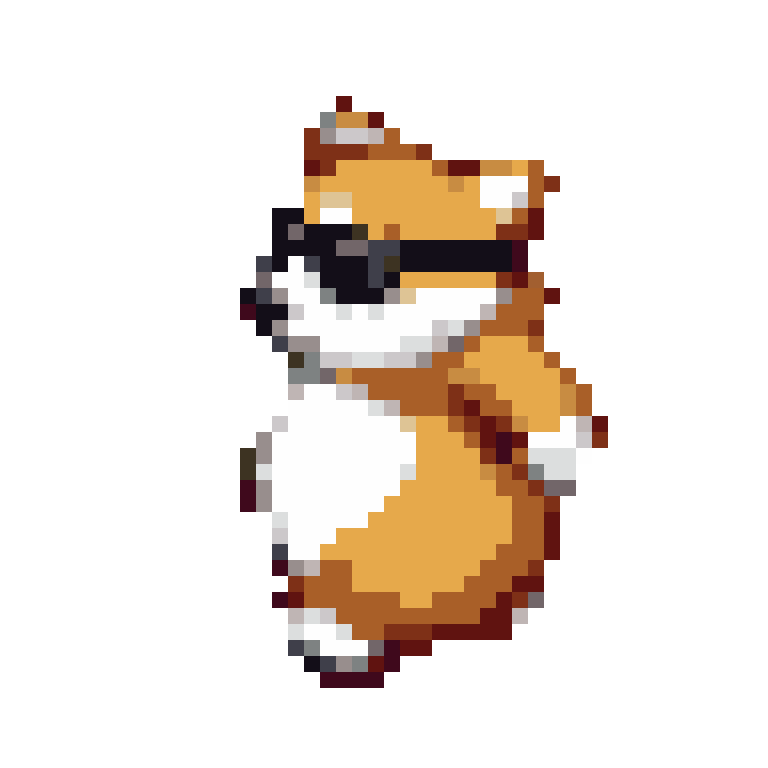 retro-diffusion/rd-animation
Style consistent animated pixel art sprite generation
Updated 11 months, 3 weeks ago
21.1K runs
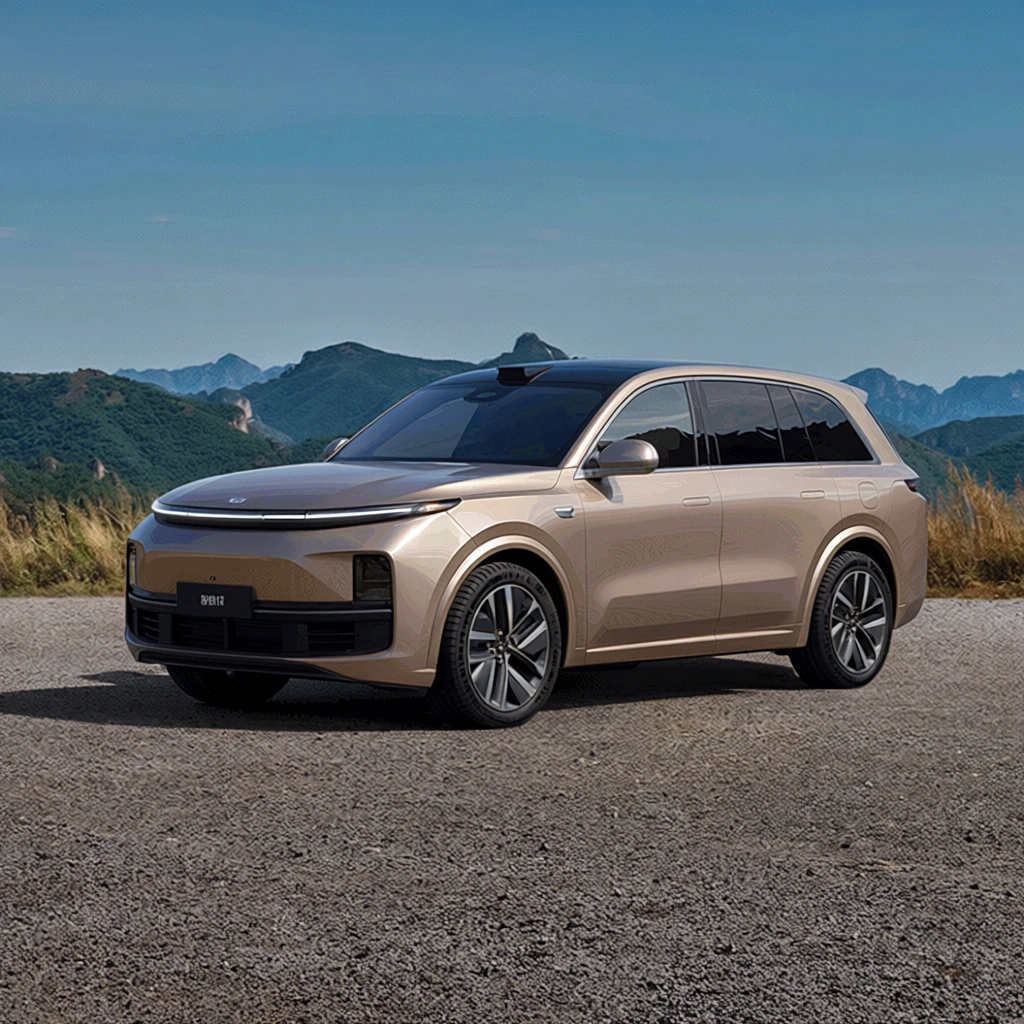
Fusion – Product/object blending that fixes perspective and lighting so the subject melts into a new background via the Fusion LoRA.
Updated 1 year ago
2.2K runs
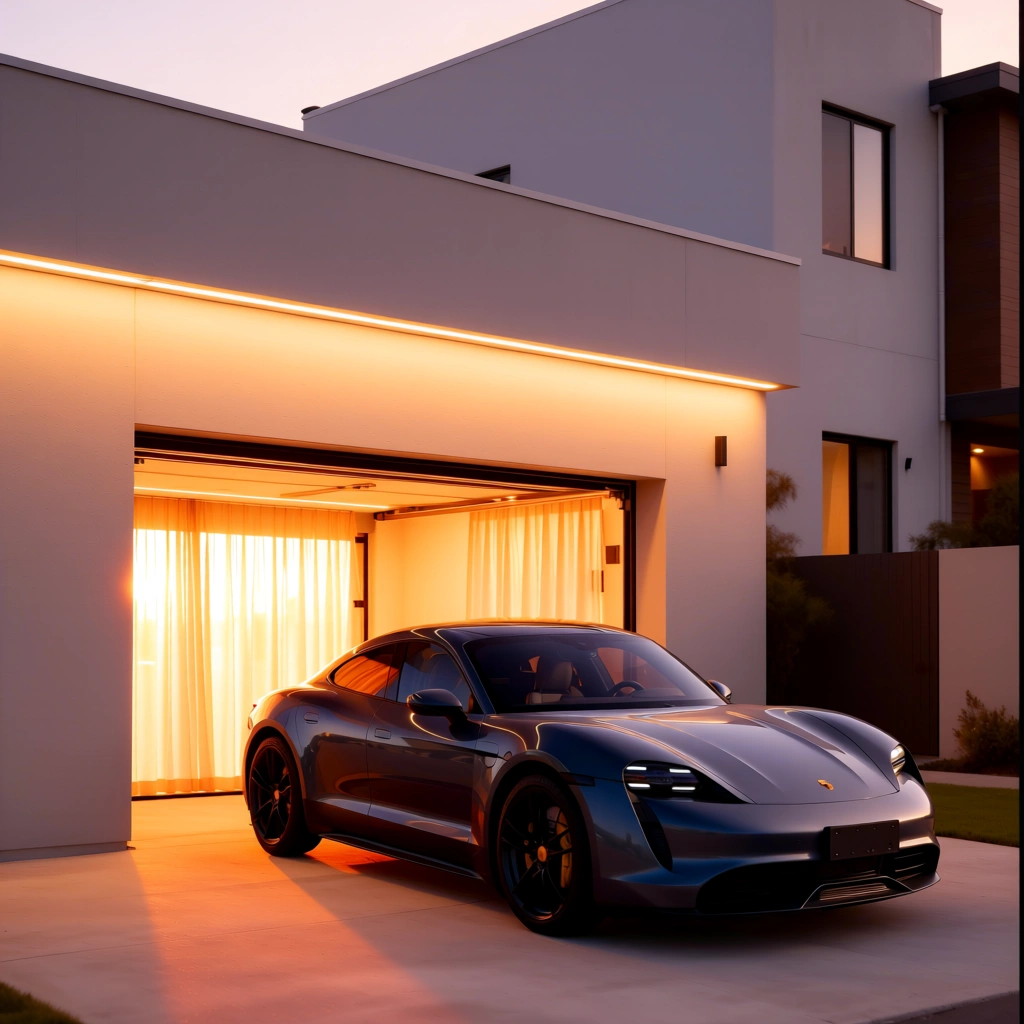
Relight – Soft, curtain-filtered relighting that repaints the scene with golden-hour or moody tones using the Relight LoRA.
Updated 1 year ago
5.6K runs
Upscale – Detail-loving upscale/restore pass that sharpens textures and color fidelity with the Upscale LoRA.
Updated 1 year ago
2.6K runs

Next Scene – “Next beat” cinematic edits that keep subject identity while steering to the next camera move via the Next Scene LoRA
Updated 1 year ago
5.2K runs
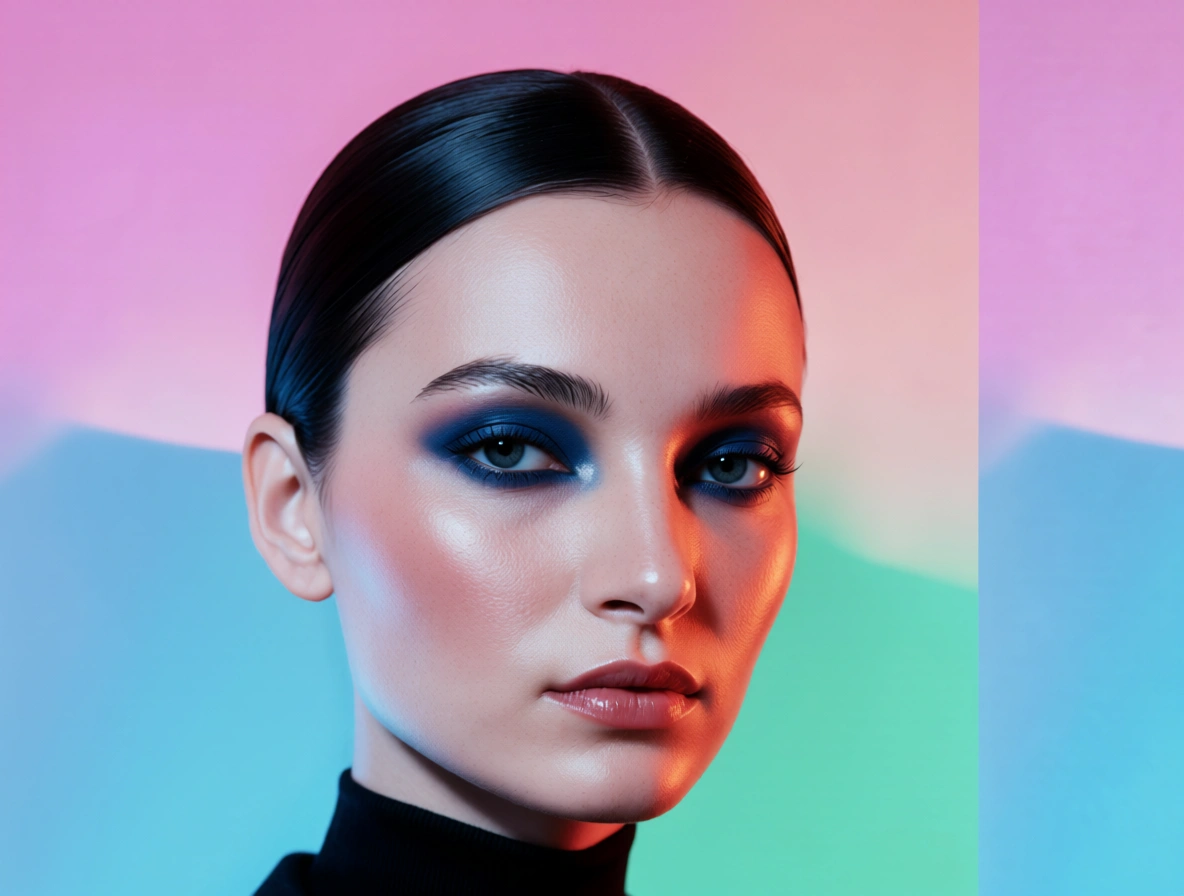
Skin – Natural beauty retouch that enhances pores and tonal variation (no plastic skin) via the Skin LoRA.
Updated 1 year ago
16.1K runs
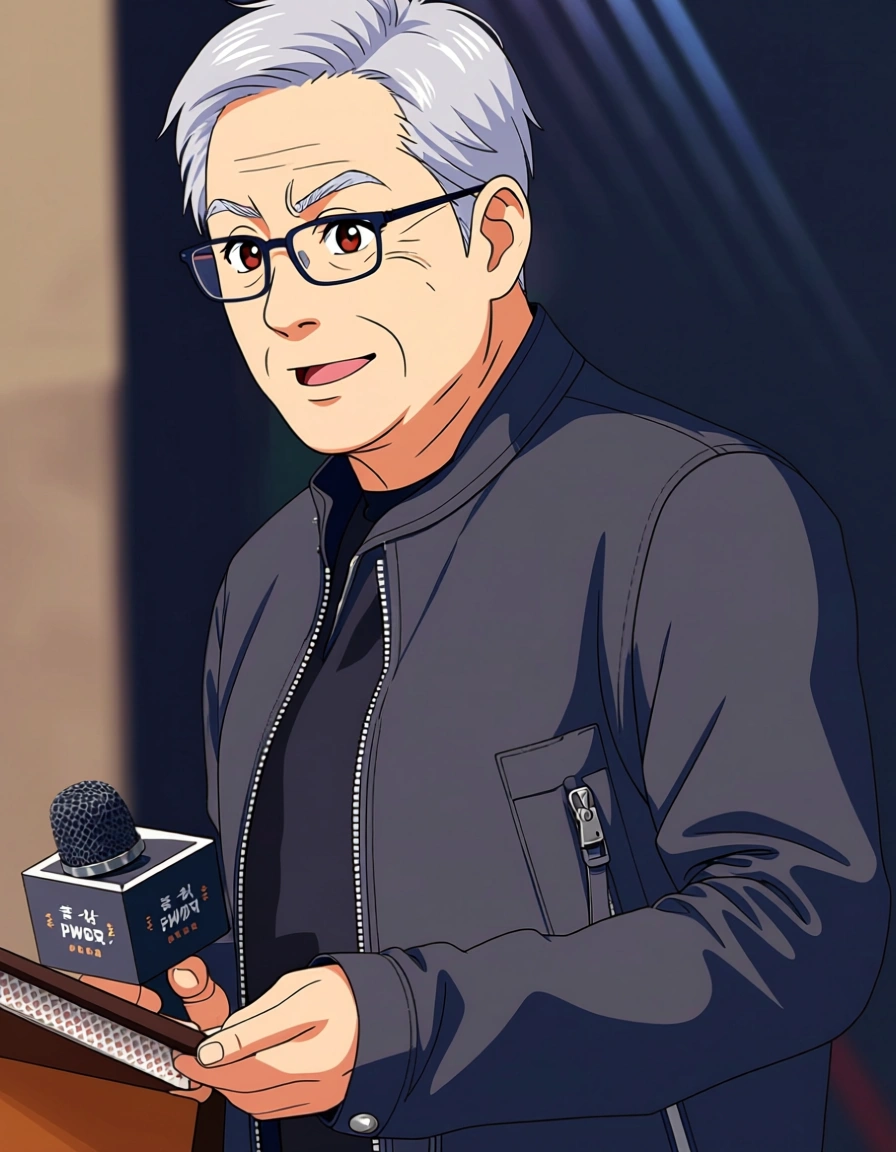
Photo to Anime – Stylized conversion that turns photos into crisp cel-shaded anime frames using the Photo-to-Anime LoRA.
Updated 1 year ago
3.9K runs
 mirelo/video-to-sfx-v1.5
Generate synced sounds for any video and return it with its new soundtrack - now enhanced in version 1.5 for improved sound synchronization and realism
Updated 1 year ago
143.4K runs
mirelo/video-to-sfx-v1Generate synced sounds for any video, and return it with its new sound track
Updated 1 year ago
6K runs
 perceptron-ai-inc/isaac-0.1
an open-source, 2B-parameter model built for real-world applications
Updated 1 year ago
67.5K runs
 qwen/qwen-image-edit-plus-lora
Qwen Image Edit 2509 LoRA explorer, uses HuggingFace URLs to load any safetensor
Updated 1 year ago
667.6K runs
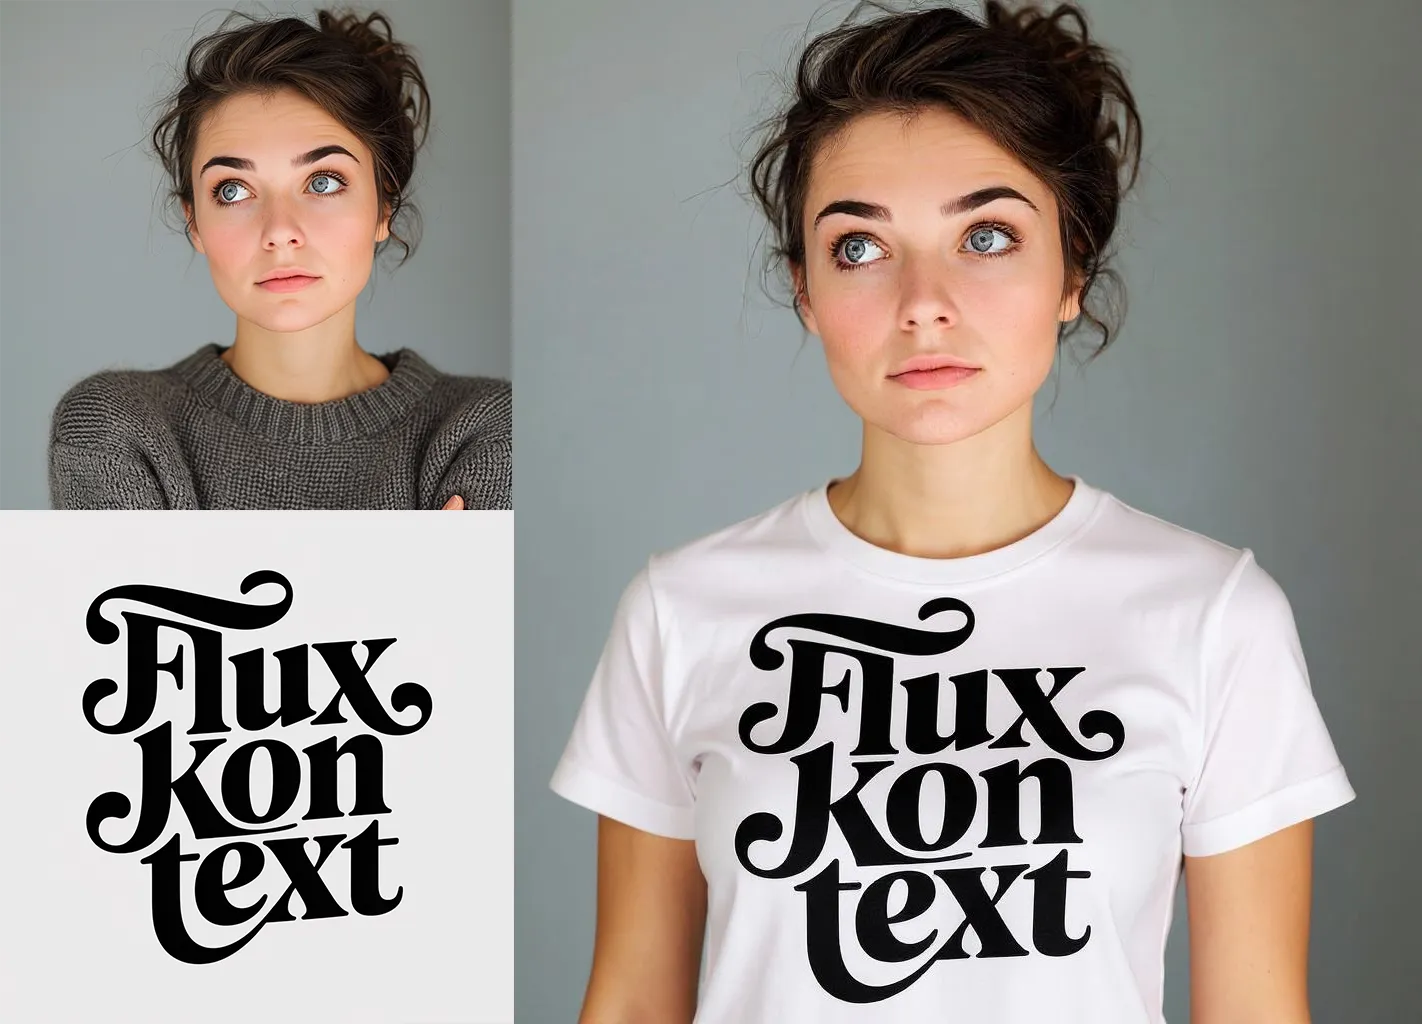
 flux-kontext-apps/multi-image-kontext-max
An experimental FLUX Kontext model that can combine two input images
Updated 1 year ago
257K runs
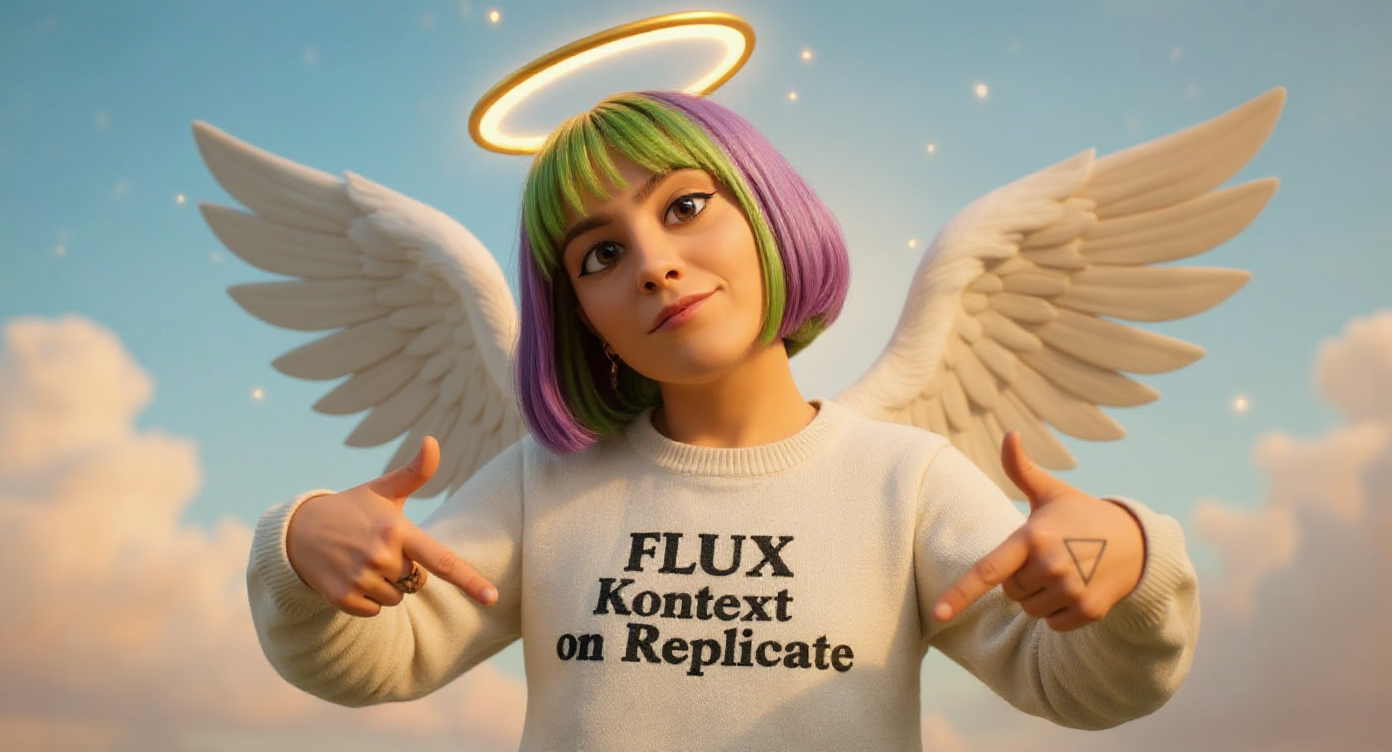 flux-kontext-apps/face-to-many-kontext
Become a character, in style
Updated 1 year ago
109.6K runs
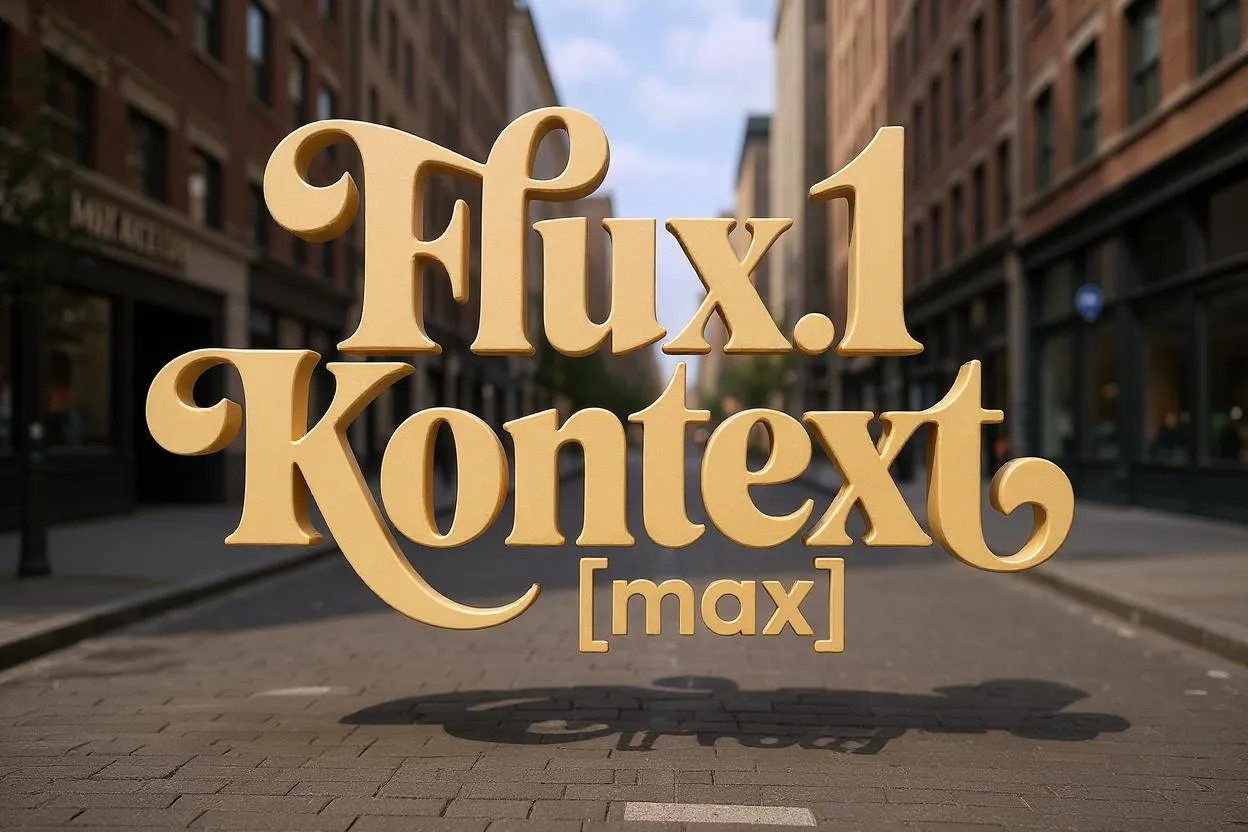 black-forest-labs/flux-kontext-max
A premium text-based image editing model that delivers maximum performance and improved typography generation for transforming images through natural language prompts
Updated 1 year ago
12.7M runs
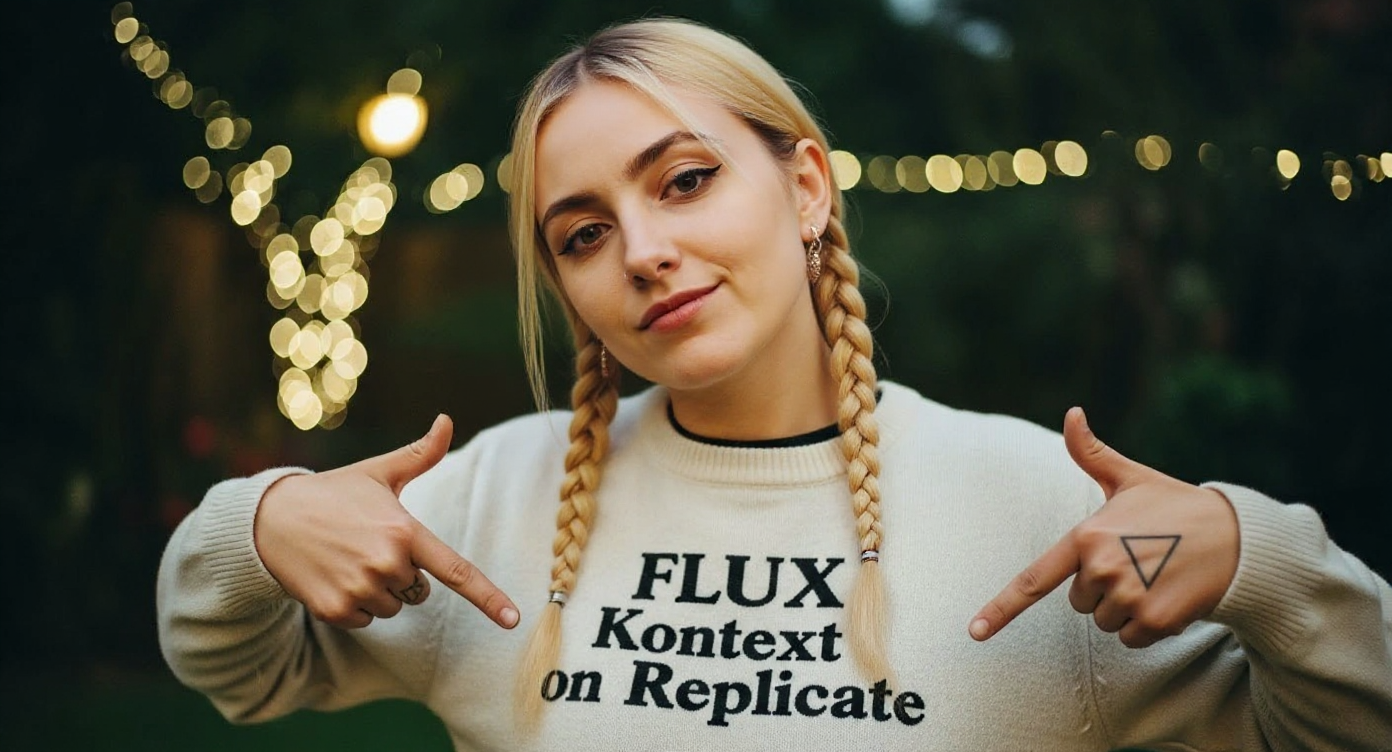 flux-kontext-apps/change-haircut
Quickly change someone's hair style and hair color, powered by FLUX.1 Kontext [pro]
Updated 1 year ago
222.8K runs
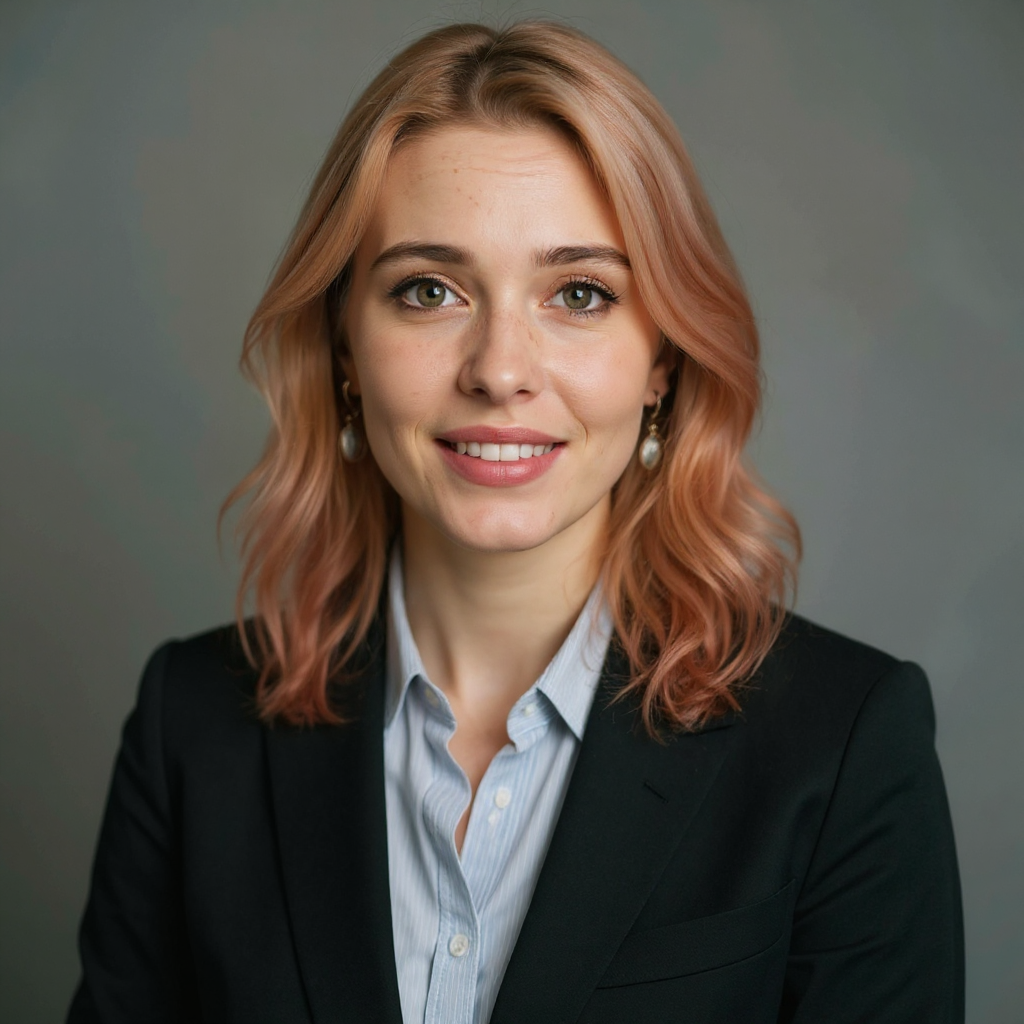 flux-kontext-apps/professional-headshot
Create a professional headshot photo from any single image
Updated 1 year ago
85K runs
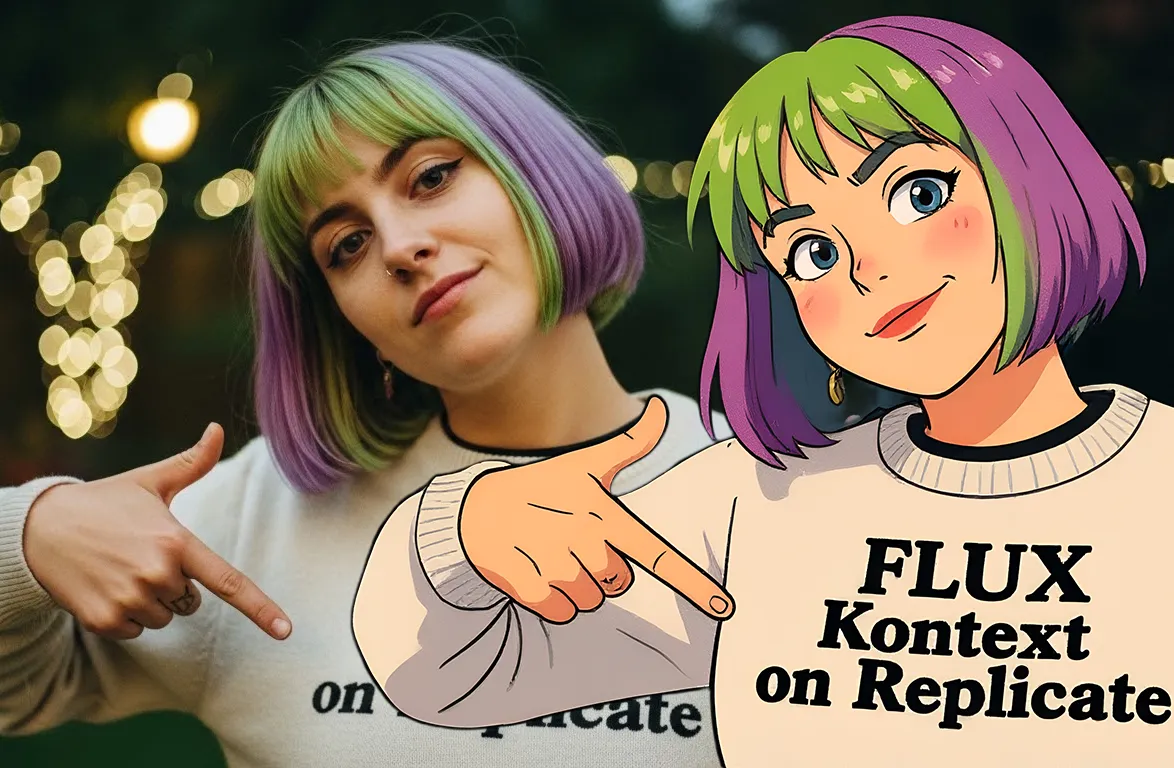 black-forest-labs/flux-kontext-pro
A state-of-the-art text-based image editing model that delivers high-quality outputs with excellent prompt following and consistent results for transforming images through natural language
Updated 1 year ago
54.6M runs
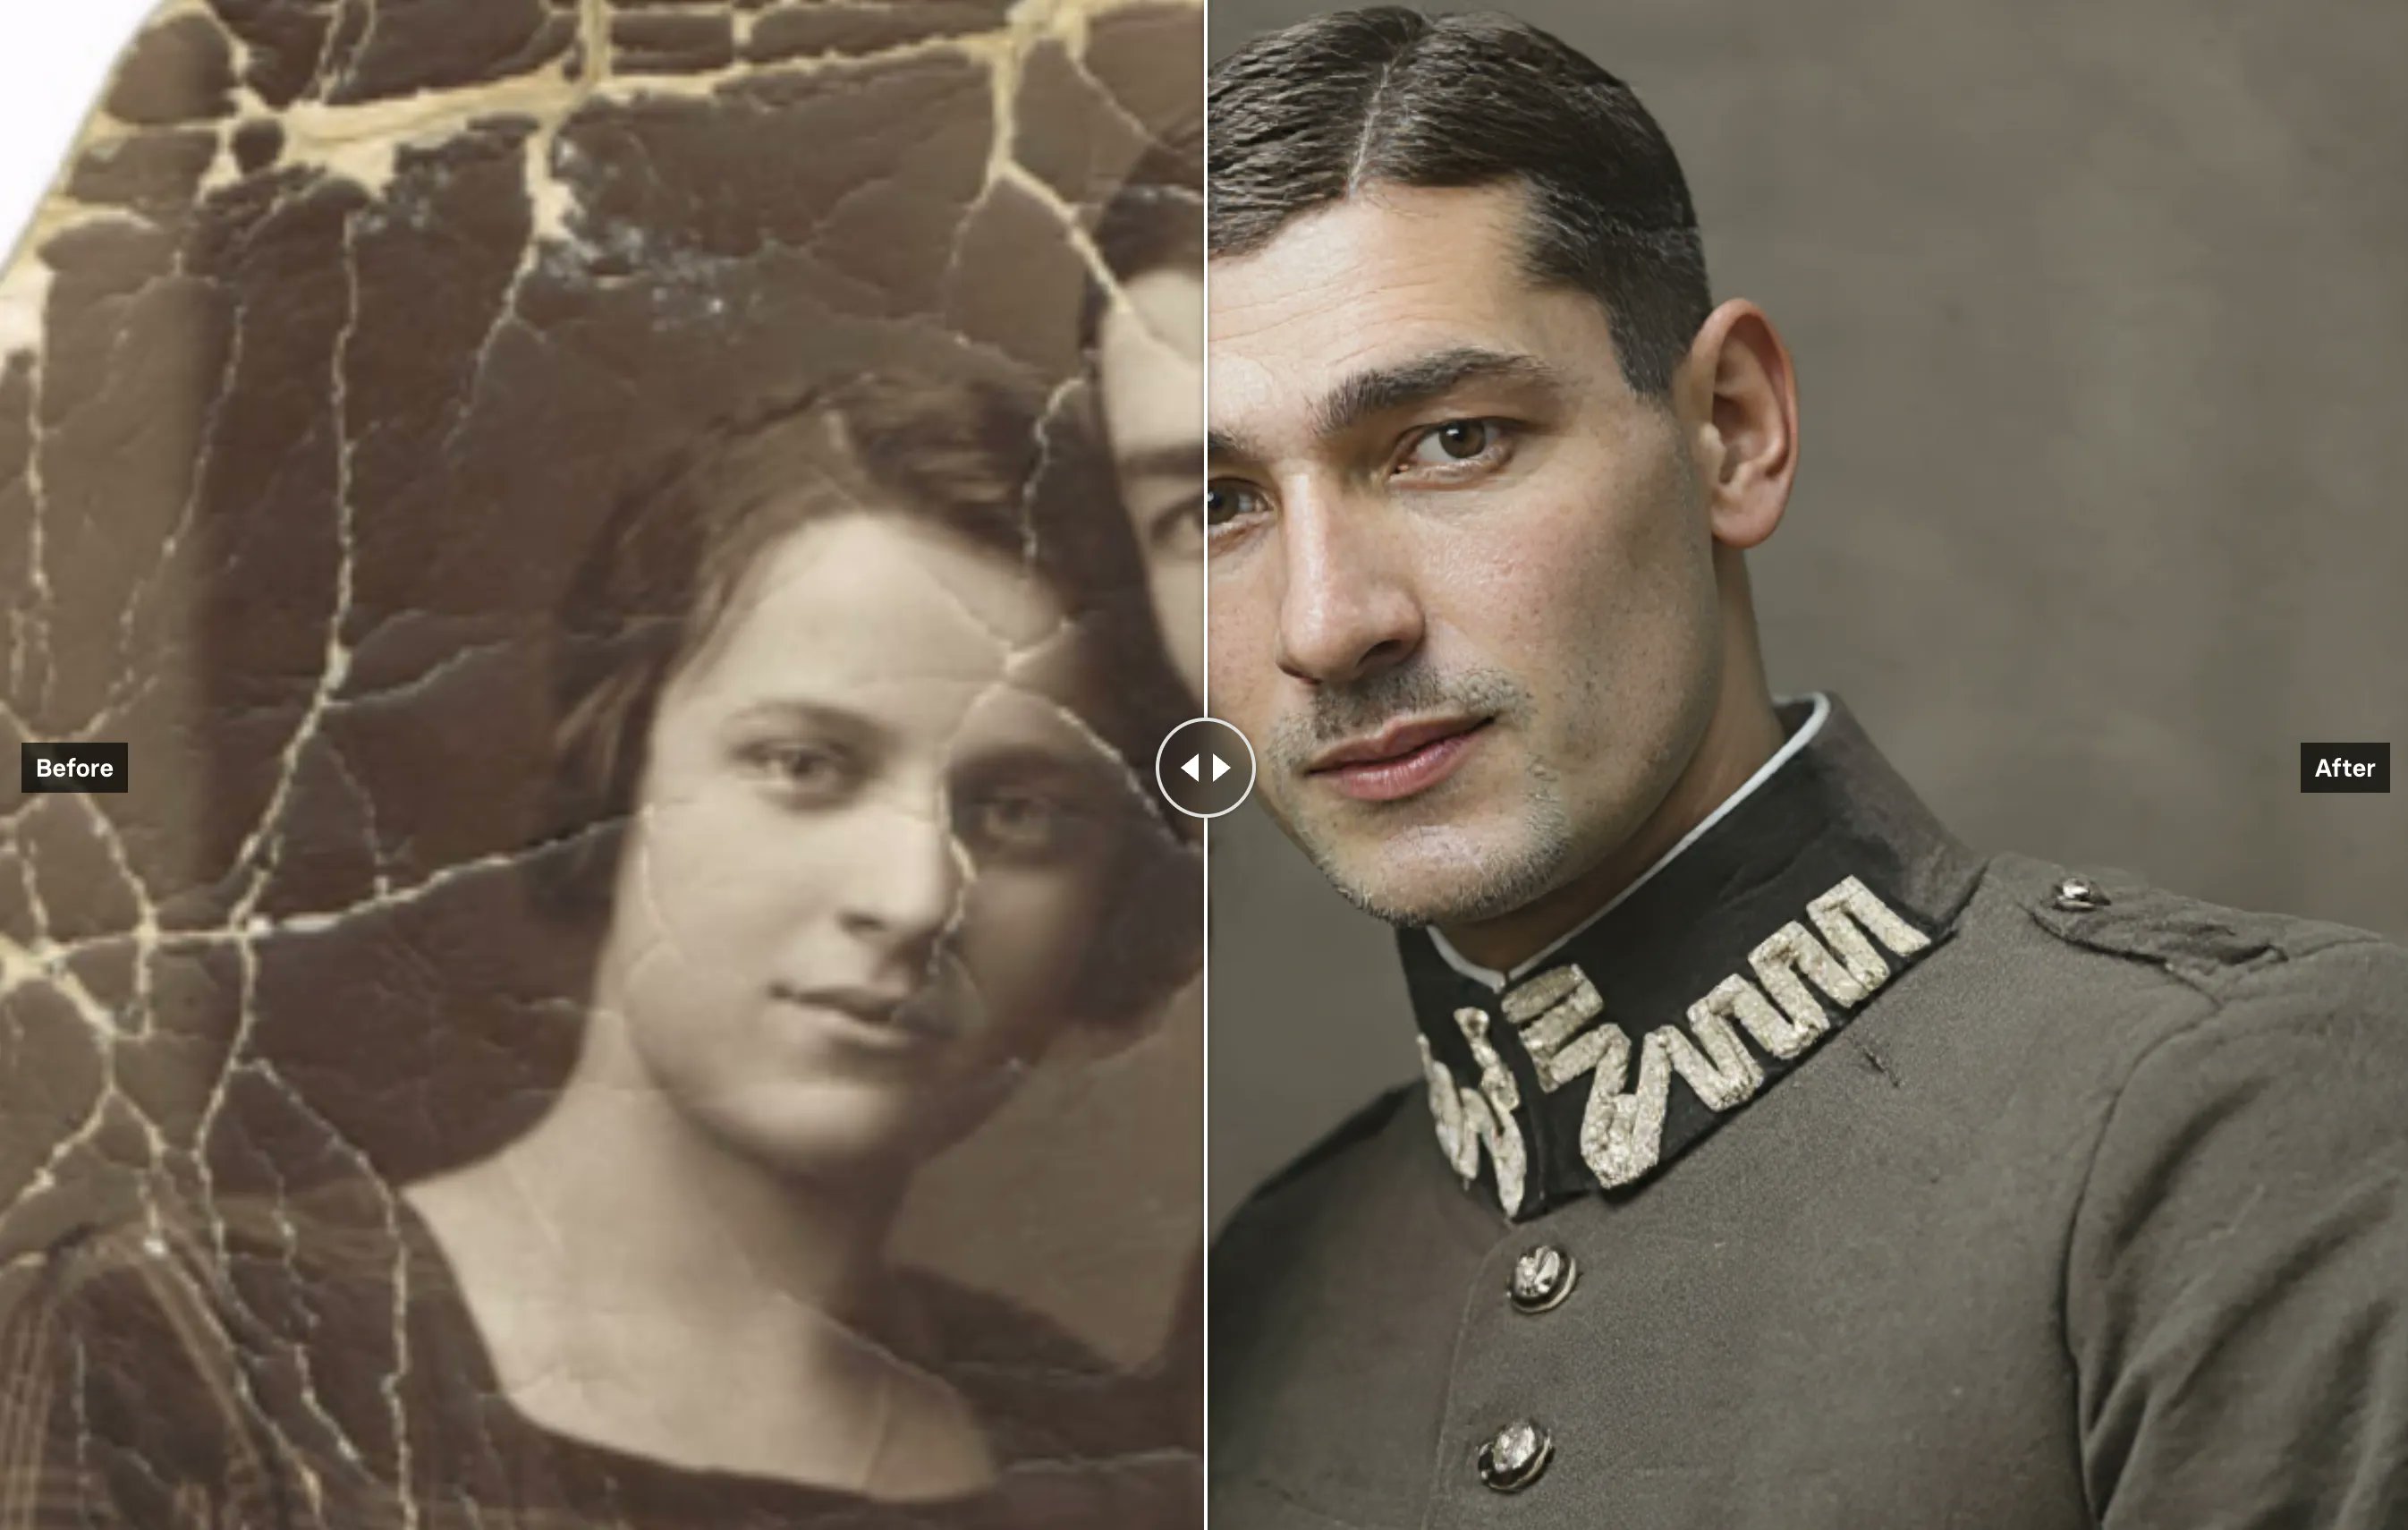 flux-kontext-apps/restore-image
Use FLUX Kontext to restore, fix scratches and damage, and colorize old photos
Updated 1 year ago
1.4M runs
 flux-kontext-apps/restyle-video-frame
Use flux-kontext-pro to change the first or last frame of a video. Useful to use as inputs for restyling an entire video in a certain way
Updated 1 year ago
673 runs
 flux-kontext-apps/text-removal
Remove all text from an image with FLUX.1 Kontext
Updated 1 year ago
204.7K runs
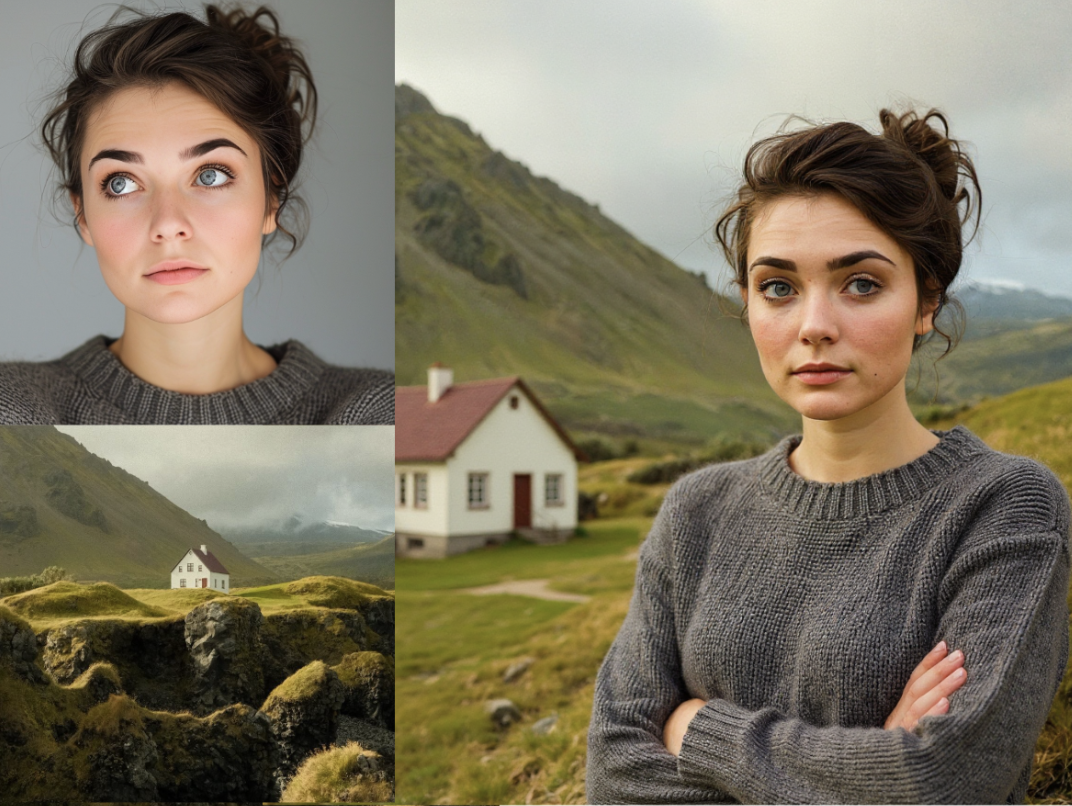 flux-kontext-apps/multi-image-kontext-pro
An experimental model with FLUX Kontext Pro that can combine two input images
Updated 1 year ago
2.4M runs
 flux-kontext-apps/portrait-series
Create a series of portrait photos from a single image
Updated 1 year ago
96.2K runs
 flux-kontext-apps/depth-of-field
Bring your subjects into focus with FLUX.1 Kontext [pro]
Updated 1 year ago
2.9K runs
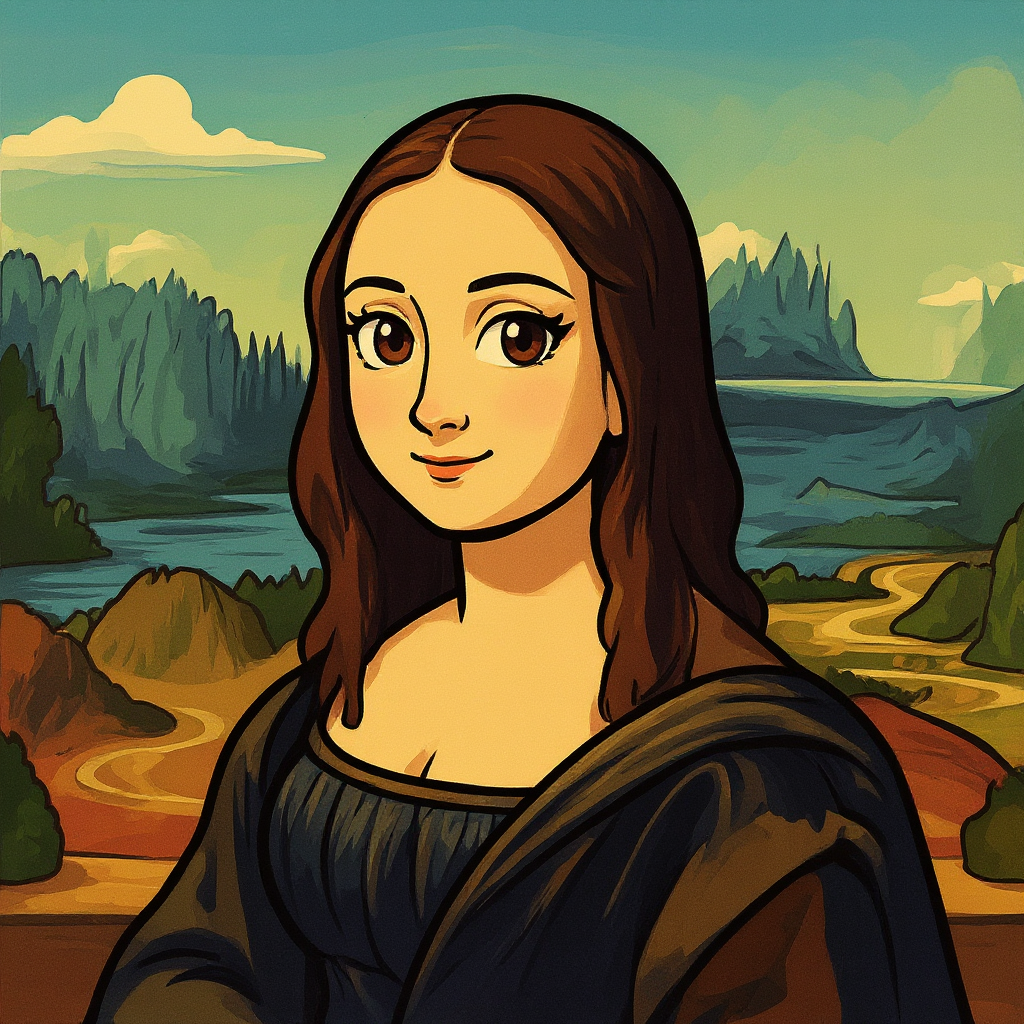 flux-kontext-apps/cartoonify
Turn your image into a cartoon with FLUX.1 Kontext [pro]
Updated 1 year ago
198.3K runs
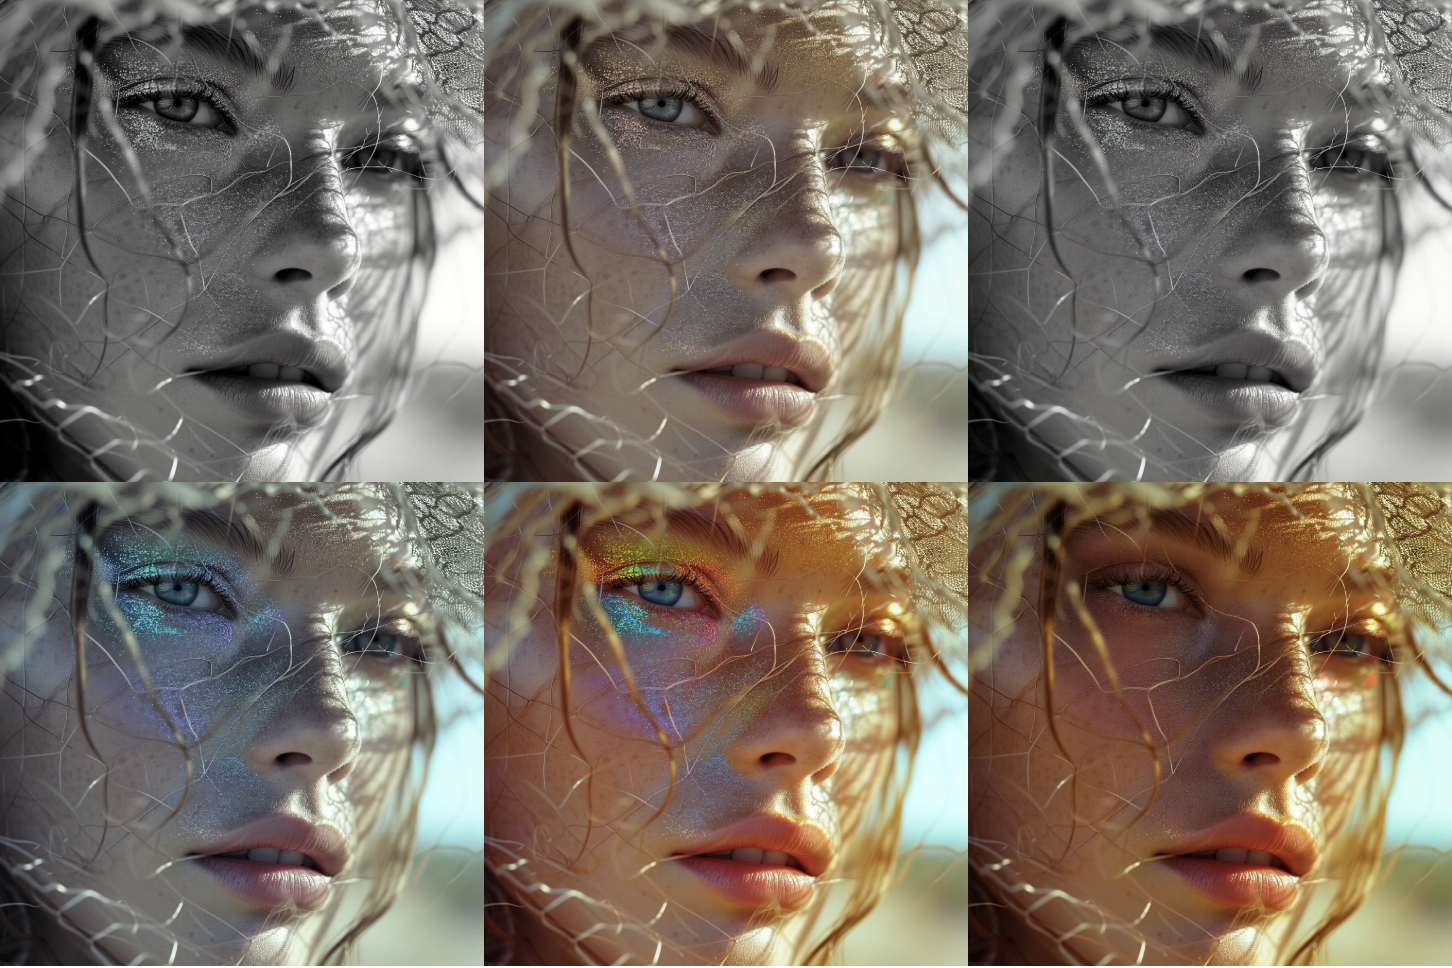 flux-kontext-apps/filters
Add simple filters to your images
Updated 1 year ago
9.4K runs
 flux-kontext-apps/multi-image-list
FLUX Kontext max with list input for multiple images
Updated 1 year ago
187.4K runs
 flux-kontext-apps/impossible-scenarios
Experience impossible adventures and extreme scenarios from a single image
Updated 1 year ago
6.6K runs
 flux-kontext-apps/iconic-locations
Put yourself in an iconic location around the world from a single image
Updated 1 year ago
38.5K runs
 qwen/qwen-edit-multiangle
Camera-aware edits for Qwen/Qwen-Image-Edit-2509 with Lightning + multi-angle LoRA
Updated 1 year ago
930.6K runs
 black-forest-labs/flux-1.1-pro-ultra-finetuned
Inference model for FLUX 1.1 [pro] Ultra using custom `finetune_id`. Supports 4MP images and raw mode for realism
Updated 1 year ago
111.4K runs
 black-forest-labs/flux-1.1-pro
Faster, better FLUX Pro. Text-to-image model with excellent image quality, prompt adherence, and output diversity.
Updated 1 year ago
74M runs
 black-forest-labs/flux-pro
State-of-the-art image generation with top of the line prompt following, visual quality, image detail and output diversity.
Updated 1 year ago
14.2M runs
 bytedance/seedance-1-pro
A pro version of Seedance that offers text-to-video and image-to-video support for 5s or 10s videos, at 480p and 1080p resolution
Updated 1 year ago
2.5M runs
 bytedance/seedream-3
A text-to-image model with support for native high-resolution (2K) image generation
Updated 1 year ago
3.4M runs
bytedance/seedance-1-pro-fastA faster and cheaper version of Seedance 1 Pro
Updated 1 year ago
2.1M runs
 openai/gpt-4o-mini-transcribe
A speech-to-text model that uses GPT-4o mini to transcribe audio
Updated 1 year ago
41.4K runs
 openai/gpt-4o-transcribe
A speech-to-text model that uses GPT-4o to transcribe audio
Updated 1 year ago
100K runs
 leonardoai/motion-2.0
Create 5s 480p videos from a text prompt
Updated 1 year ago
12.5K runs
 leonardoai/phoenix-1.0
Leonardo AI’s first foundational model produces images up to 5 megapixels (fast, quality and ultra modes)
Updated 1 year ago
40.3K runs
 ideogram-ai/ideogram-v3-turbo
Turbo is the fastest and cheapest Ideogram v3. v3 creates images with stunning realism, creative designs, and consistent styles
Updated 1 year ago
9.6M runs
 ideogram-ai/ideogram-v2a-turbo
Like Ideogram v2 turbo, but now faster and cheaper
Updated 1 year ago
392.8K runs
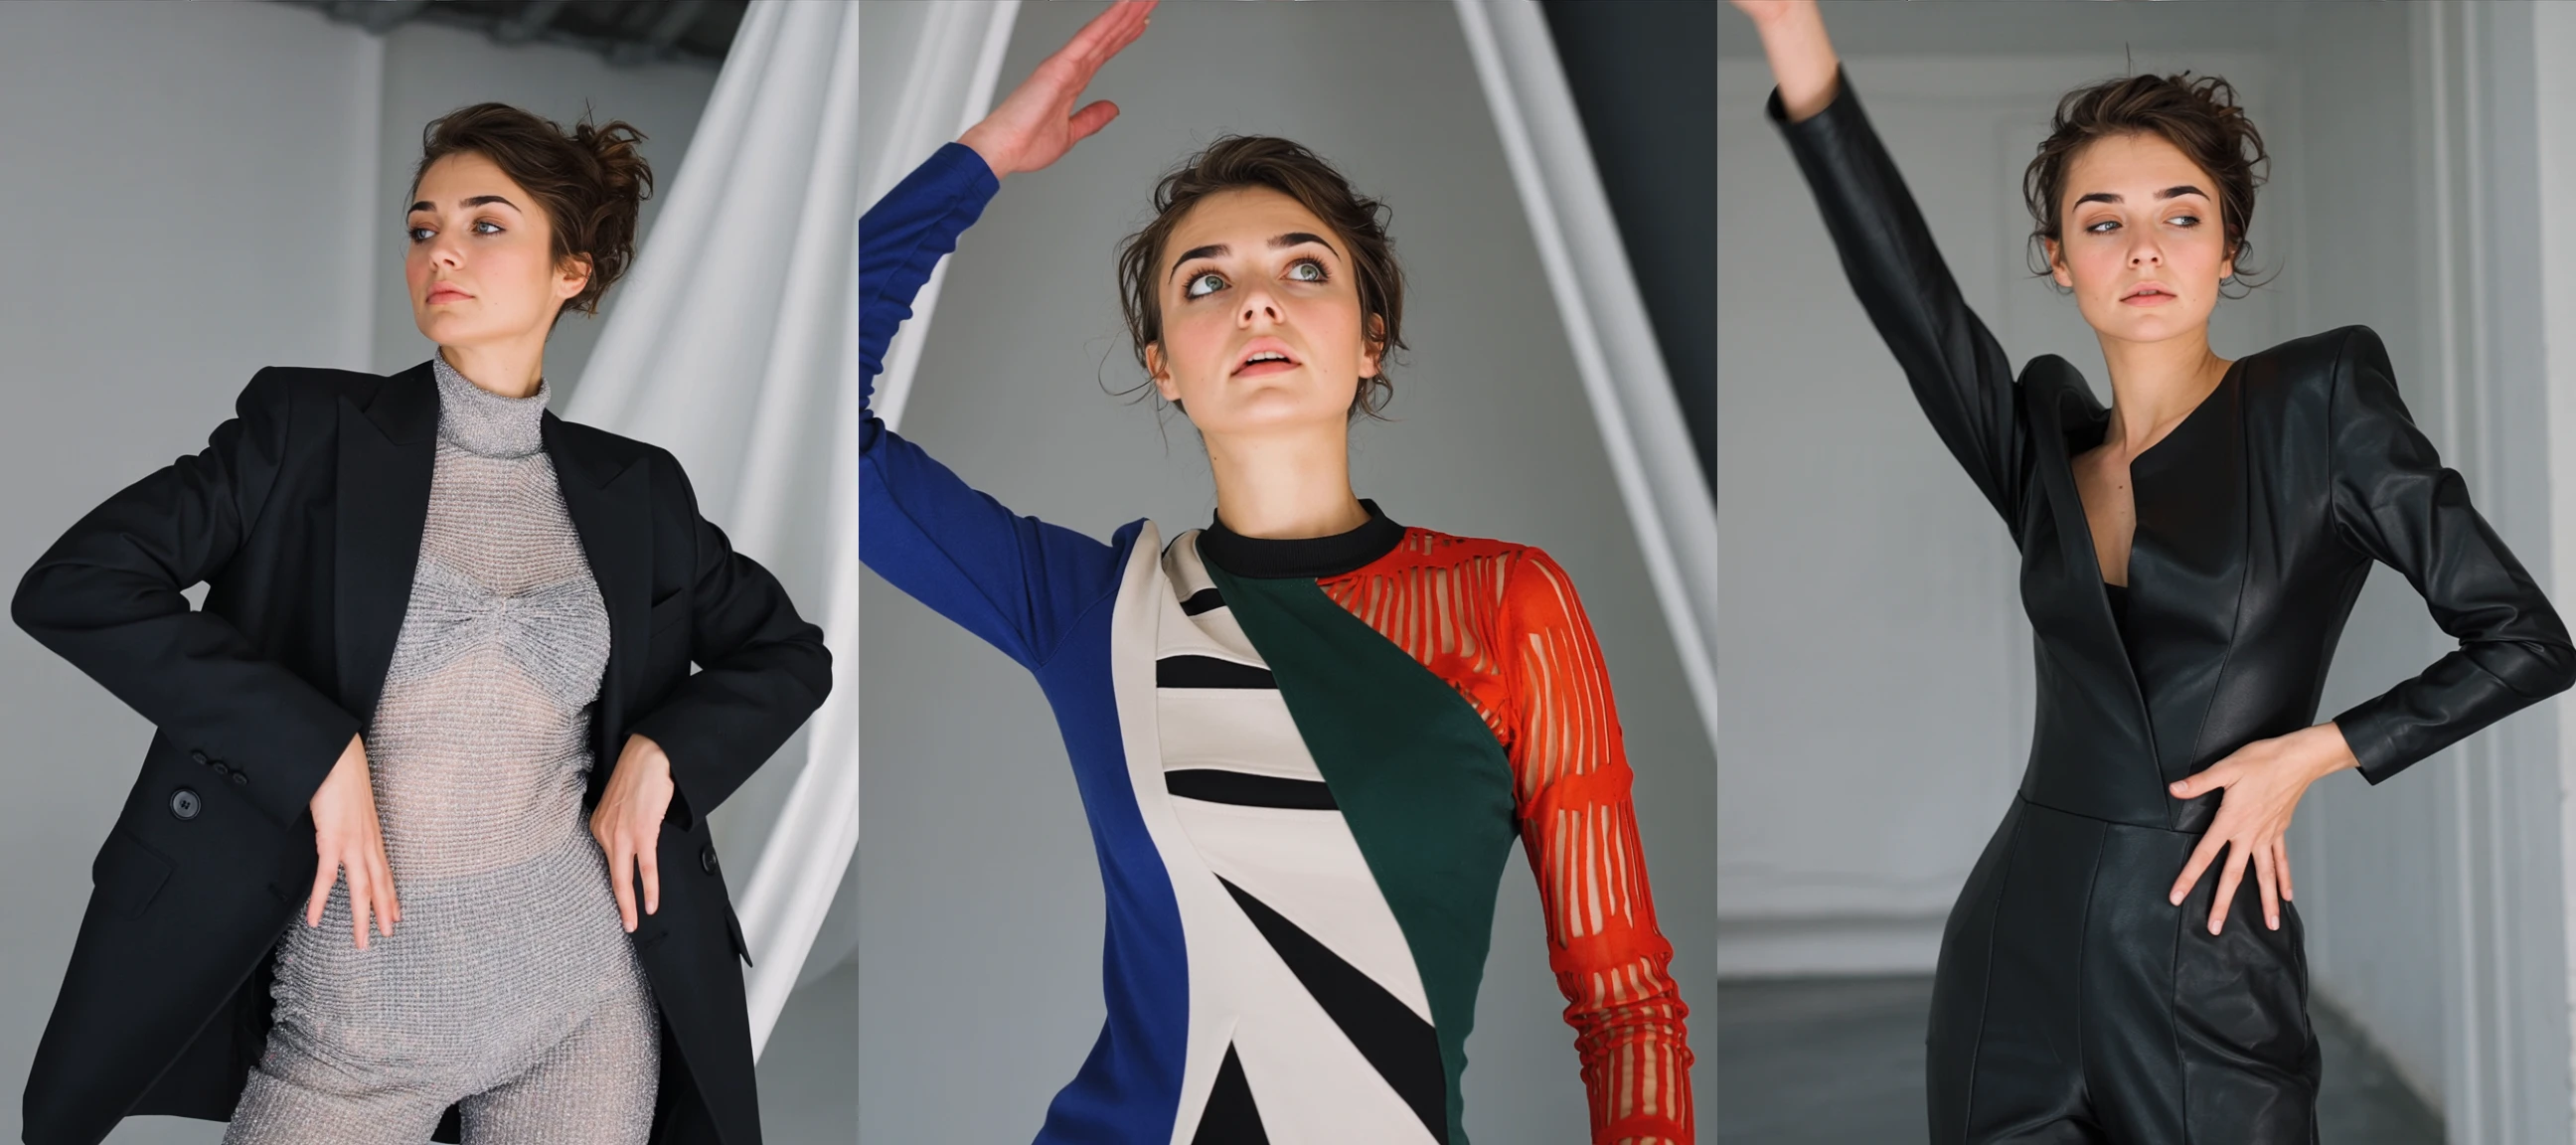 ideogram-ai/ideogram-character
Generate consistent characters from a single reference image. Outputs can be in many styles. You can also use inpainting to add your character to an existing image.
Updated 1 year ago
605.4K runs
kwaivgi/kling-lip-syncAdd lip-sync to any video with an audio file or text
Updated 1 year ago
64.1K runs
 ideogram-ai/ideogram-v2
An excellent image model with state of the art inpainting, prompt comprehension and text rendering
Updated 1 year ago
2.9M runs
 ideogram-ai/ideogram-v3-quality
The highest quality Ideogram v3 model. v3 creates images with stunning realism, creative designs, and consistent styles
Updated 1 year ago
2.4M runs
 ideogram-ai/ideogram-v2a
Like Ideogram v2, but faster and cheaper
Updated 1 year ago
2.2M runs
 ideogram-ai/ideogram-v3-balanced
Balance speed, quality and cost. Ideogram v3 creates images with stunning realism, creative designs, and consistent styles
Updated 1 year ago
504.8K runs
 ideogram-ai/ideogram-v2-turbo
A fast image model with state of the art inpainting, prompt comprehension and text rendering.
Updated 1 year ago
2.9M runs
 luma/modify-video
Modify a video with style transfer and prompt-based editing
Updated 1 year ago
15.4K runs
wan-video/wan-2.5-i2v-fastWan 2.5 image-to-video, optimized for speed
Updated 1 year ago
78.4K runs
 wavespeedai/wan-2.1-t2v-480p
Accelerated inference for Wan 2.1 14B text to video, a comprehensive and open suite of video foundation models that pushes the boundaries of video generation.
Updated 1 year ago
197.2K runs

 stability-ai/stable-diffusion-3.5-medium
2.5 billion parameter image model with improved MMDiT-X architecture
Updated 1 year ago
125.5K runs
 luma/reframe-video
Change the aspect ratio of any video up to 30 seconds long, outputs will be 720p
Updated 1 year ago
103.8K runs
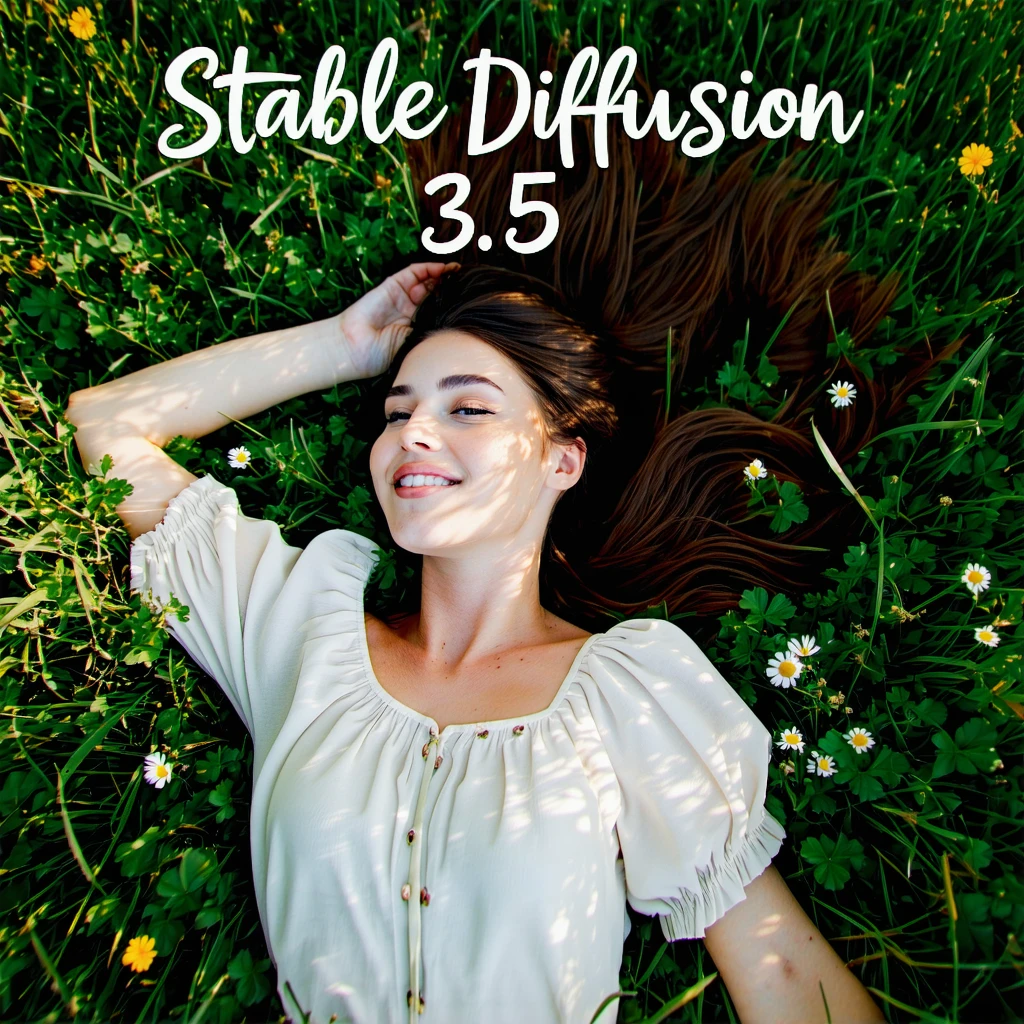 stability-ai/stable-diffusion-3.5-large
A text-to-image model that generates high-resolution images with fine details. It supports various artistic styles and produces diverse outputs from the same prompt, thanks to Query-Key Normalization.
Updated 1 year ago
2.2M runs
 stability-ai/stable-diffusion-3.5-large-turbo
A text-to-image model that generates high-resolution images with fine details. It supports various artistic styles and produces diverse outputs from the same prompt, with a focus on fewer inference steps
Updated 1 year ago
1.2M runs
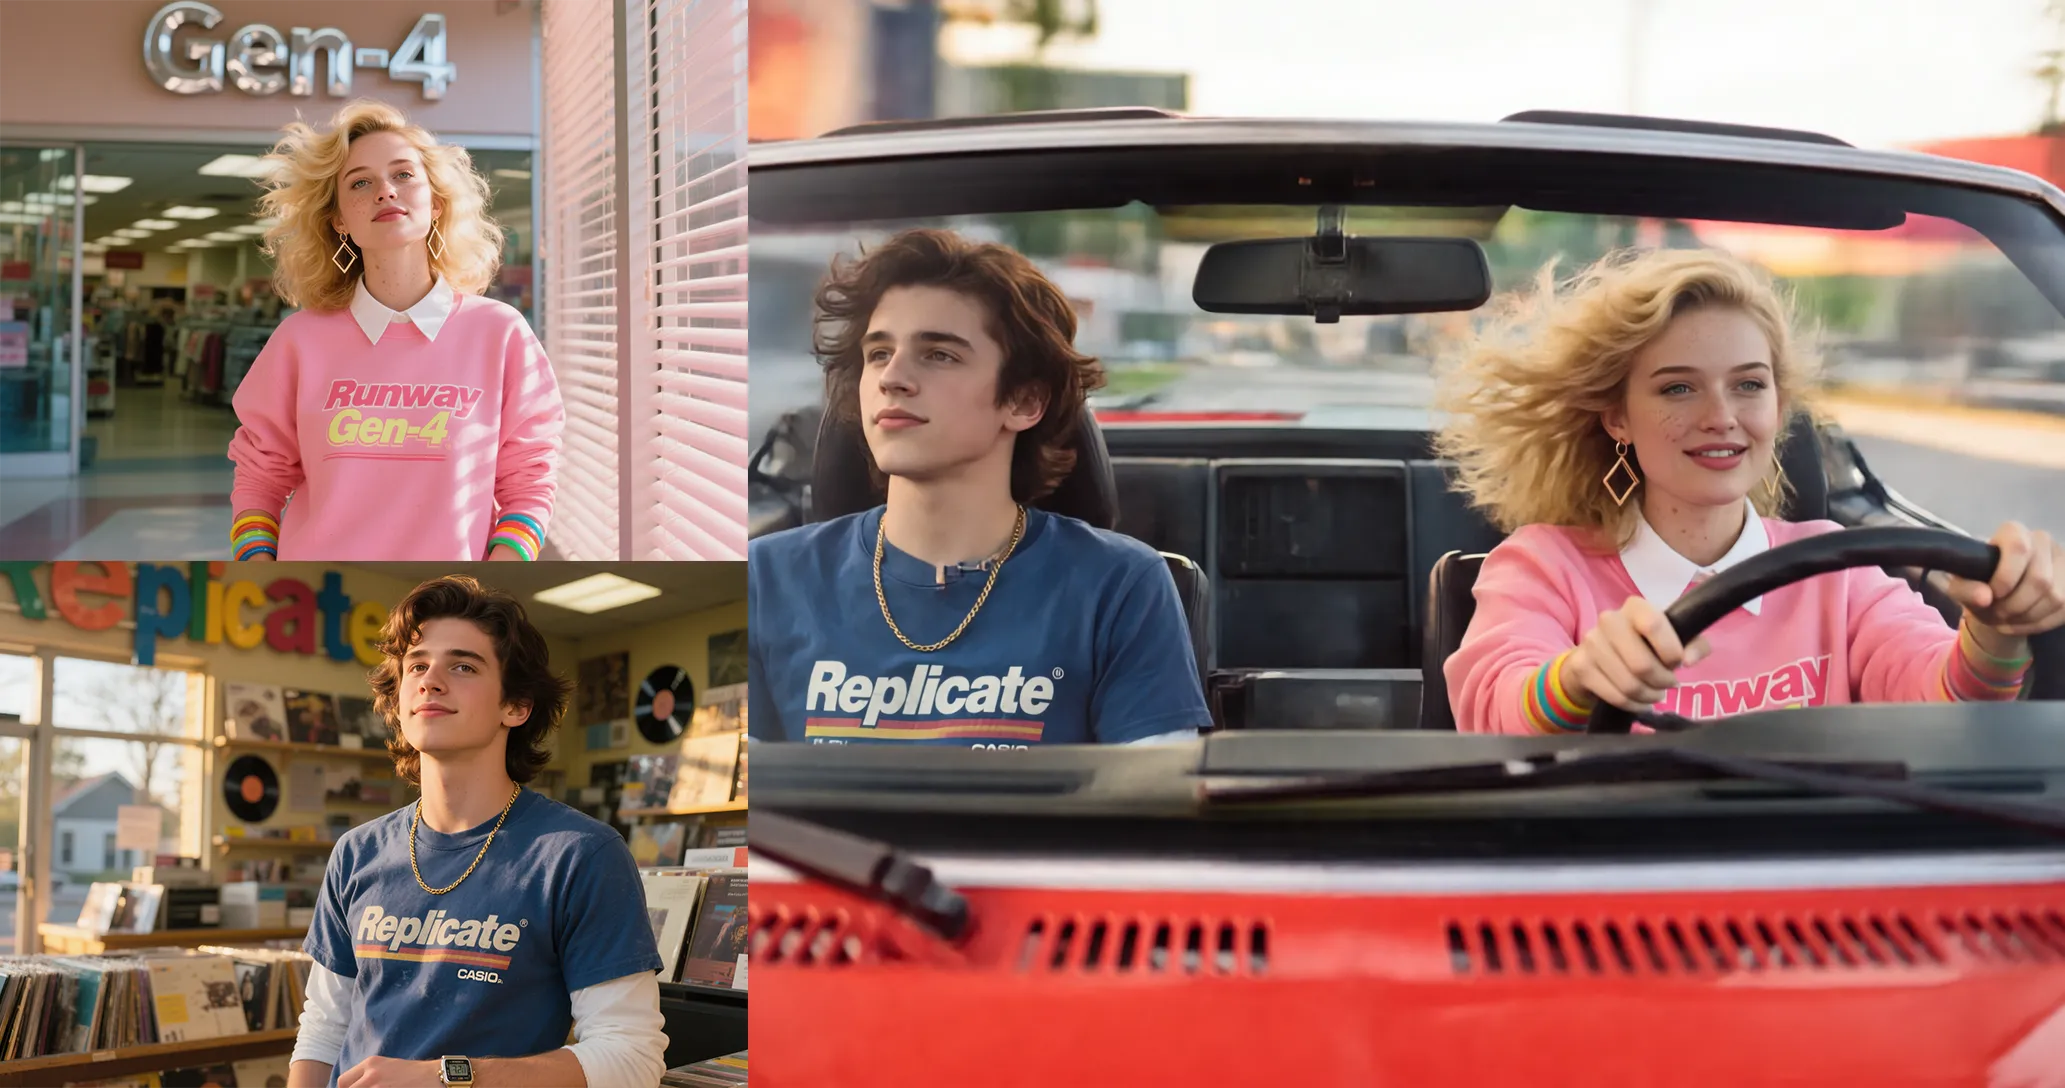 runwayml/gen4-image-turbo
Gen-4 Image Turbo is cheaper and 2.5x faster than Gen-4 Image. An image model with references, use up to 3 reference images to create the exact image you need. Capture every angle.
Updated 1 year ago
130.5K runs
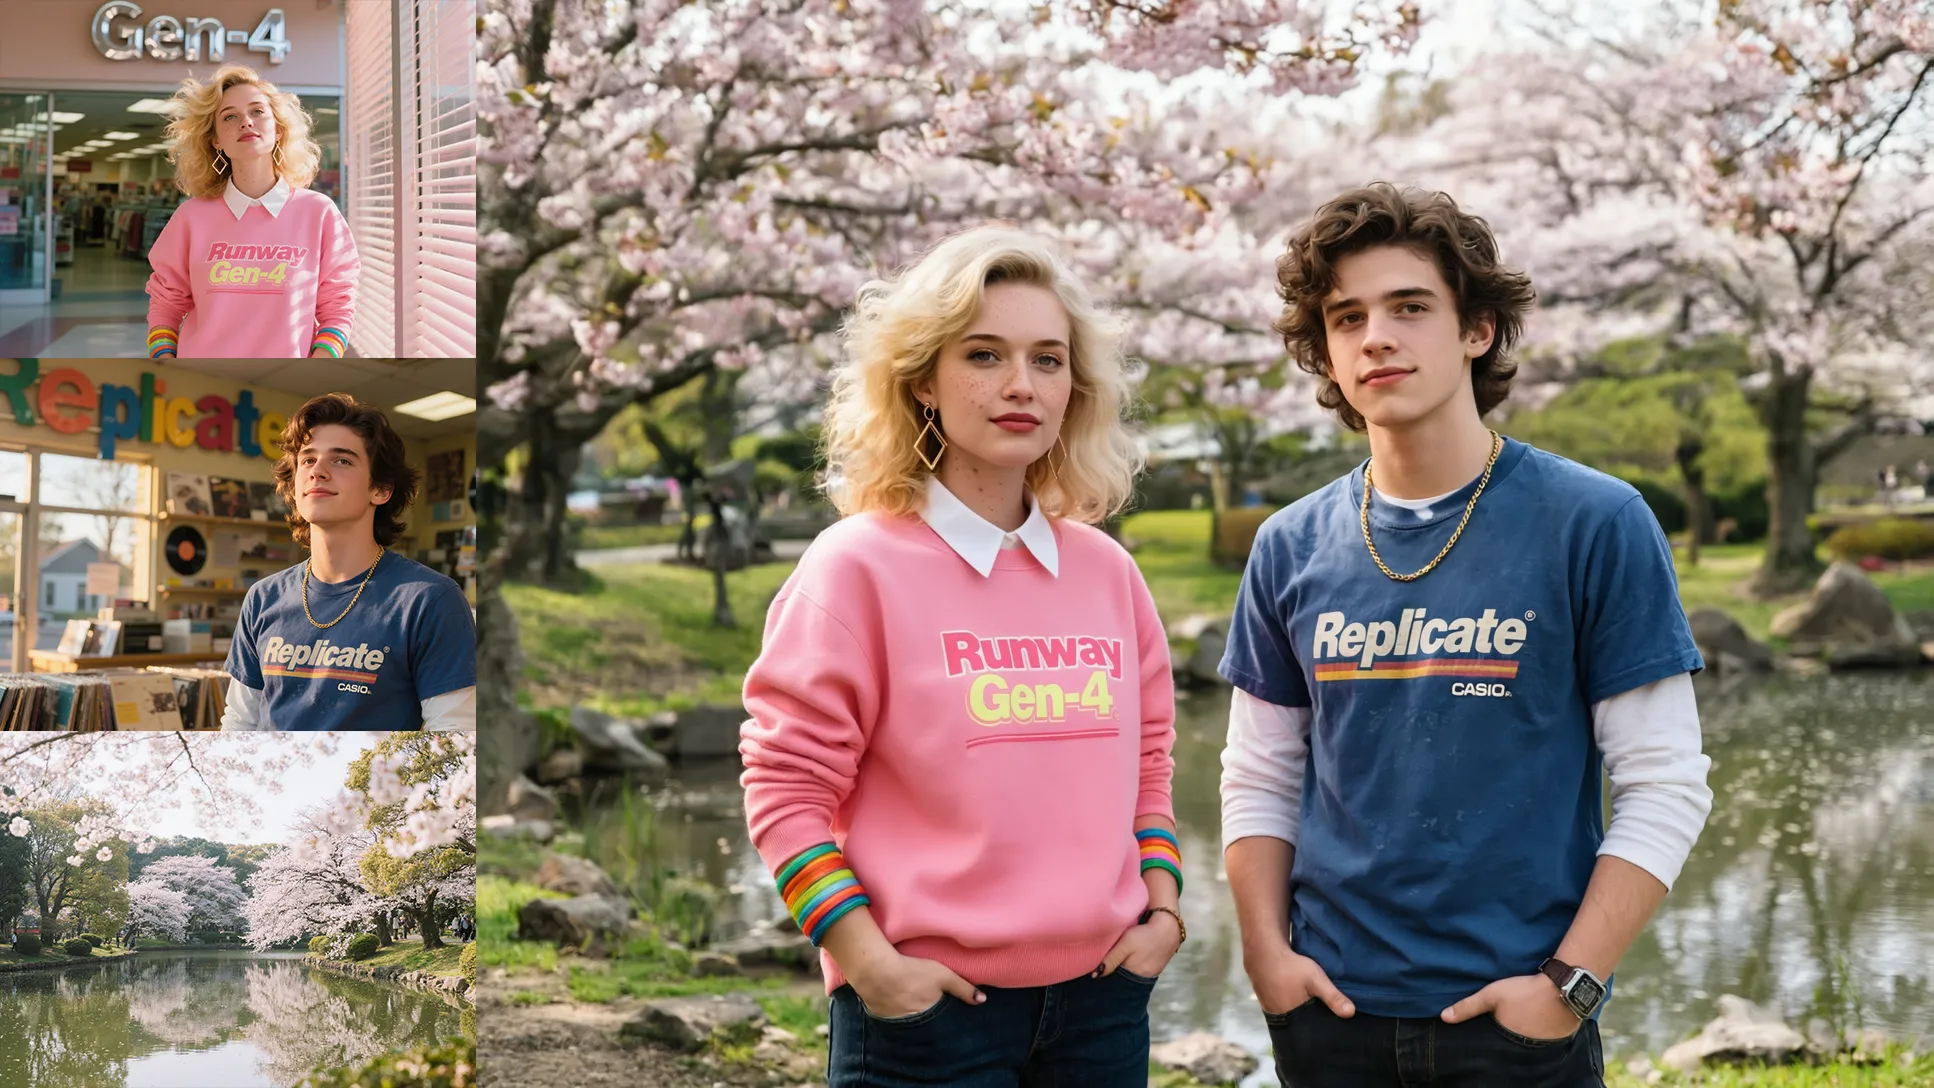 runwayml/gen4-image
Runway's Gen-4 Image model with references. Use up to 3 reference images to create the exact image you need. Capture every angle.
Updated 1 year ago
1.2M runs
 minimax/voice-cloning
Clone voices to use with Minimax's speech-02-hd and speech-02-turbo
Updated 1 year ago
90.3K runs
runwayml/gen4-turboGenerate 5s and 10s 720p videos fast
Updated 1 year ago
139.5K runs
 luma/photon-flash
Accelerated variant of Photon prioritizing speed while maintaining quality
Updated 1 year ago
2.6M runs
 stability-ai/stable-audio-2.5
Generate high-quality music and sound from text prompts
Updated 1 year ago
129.7K runs
 black-forest-labs/flux-canny-pro
Professional edge-guided image generation. Control structure and composition using Canny edge detection
Updated 1 year ago
455.6K runs
 black-forest-labs/flux-depth-pro
Professional depth-aware image generation. Edit images while preserving spatial relationships.
Updated 1 year ago
354.8K runs
 elevenlabs/music
Compose a song from a prompt or a composition plan
Updated 1 year ago
211.2K runs
 qwen/qwen-image-lora-trainer-legacy
Fine-tunable Qwen Image model with exceptional composition abilities - train custom LoRAs for any style or subject
Updated 1 year ago
2.2K runs
 nightmareai/real-esrgan
Real-ESRGAN with optional face correction and adjustable upscale
Updated 1 year ago
104.1M runs
 elevenlabs/turbo-v2.5
High quality, low latency text to speech in 32 languages
Updated 1 year ago
137.8K runs
 elevenlabs/v2-multilingual
Generate multilingual text-to-speech audio in over 30 languages
Updated 1 year ago
44.7K runs
 elevenlabs/flash-v2.5
ElevenLabs's fastest speech synthesis model
Updated 1 year ago
114.5K runs
 datalab-to/marker
Convert PDF to markdown + JSON quickly with high accuracy
Updated 1 year ago
88.8K runs
 datalab-to/ocr
Detect and transcribe text in images with accurate bounding boxes, layout analysis, reding order, and table recognition, in 90 languages
Updated 1 year ago
270.2K runs
 anthropic/claude-4.5-haiku
Claude Haiku 4.5 gives you similar levels of coding performance but at one-third the cost and more than twice the speed
Updated 1 year, 1 month ago
2.3M runs
 tencent/hunyuan-image-3
A powerful native multimodal model for image generation (PrunaAI squeezed)
Updated 1 year, 1 month ago
102.2K runs
 character-ai/ovi-i2v
Ovi: generate videos with audio from image and text inputs
Updated 1 year, 1 month ago
14.9K runs
 anthropic/claude-4.5-sonnet
Claude Sonnet 4.5 is the best coding model to date, with significant improvements across the entire development lifecycle
Updated 1 year, 1 month ago
2.3M runs
wan-video/wan-2.2-animate-animationUse Wan 2.2 Animate to copy the motion of a video to another scene
Updated 1 year, 1 month ago
34.4K runs
 qwen/qwen-image-edit-plus
The latest Qwen-Image’s iteration with improved multi-image editing, single-image consistency, and native support for ControlNet
Updated 1 year, 1 month ago
12M runs
 ibm-granite/granite-3.3-8b-instruct
Granite-3.3-8B-Instruct is a 8-billion parameter 128K context length language model fine-tuned for improved reasoning and instruction-following capabilities.
Updated 1 year, 1 month ago
1.8M runs
 intelligent-utilities/html-to-image
Updated 1 year, 1 month ago
844 runs
 tencent/hunyuan-image-2.1
Generate high-quality 2K resolution images from text prompts
Updated 1 year, 2 months ago
26.7K runs
wan-video/wan-2.2-s2vGenerate a video from an audio clip and a reference image
Updated 1 year, 2 months ago
161.5K runs
 bria/product-shadow
Add consistent, customizable shadows to product cutouts for enhanced visual appeal
Updated 1 year, 2 months ago
4.7K runs
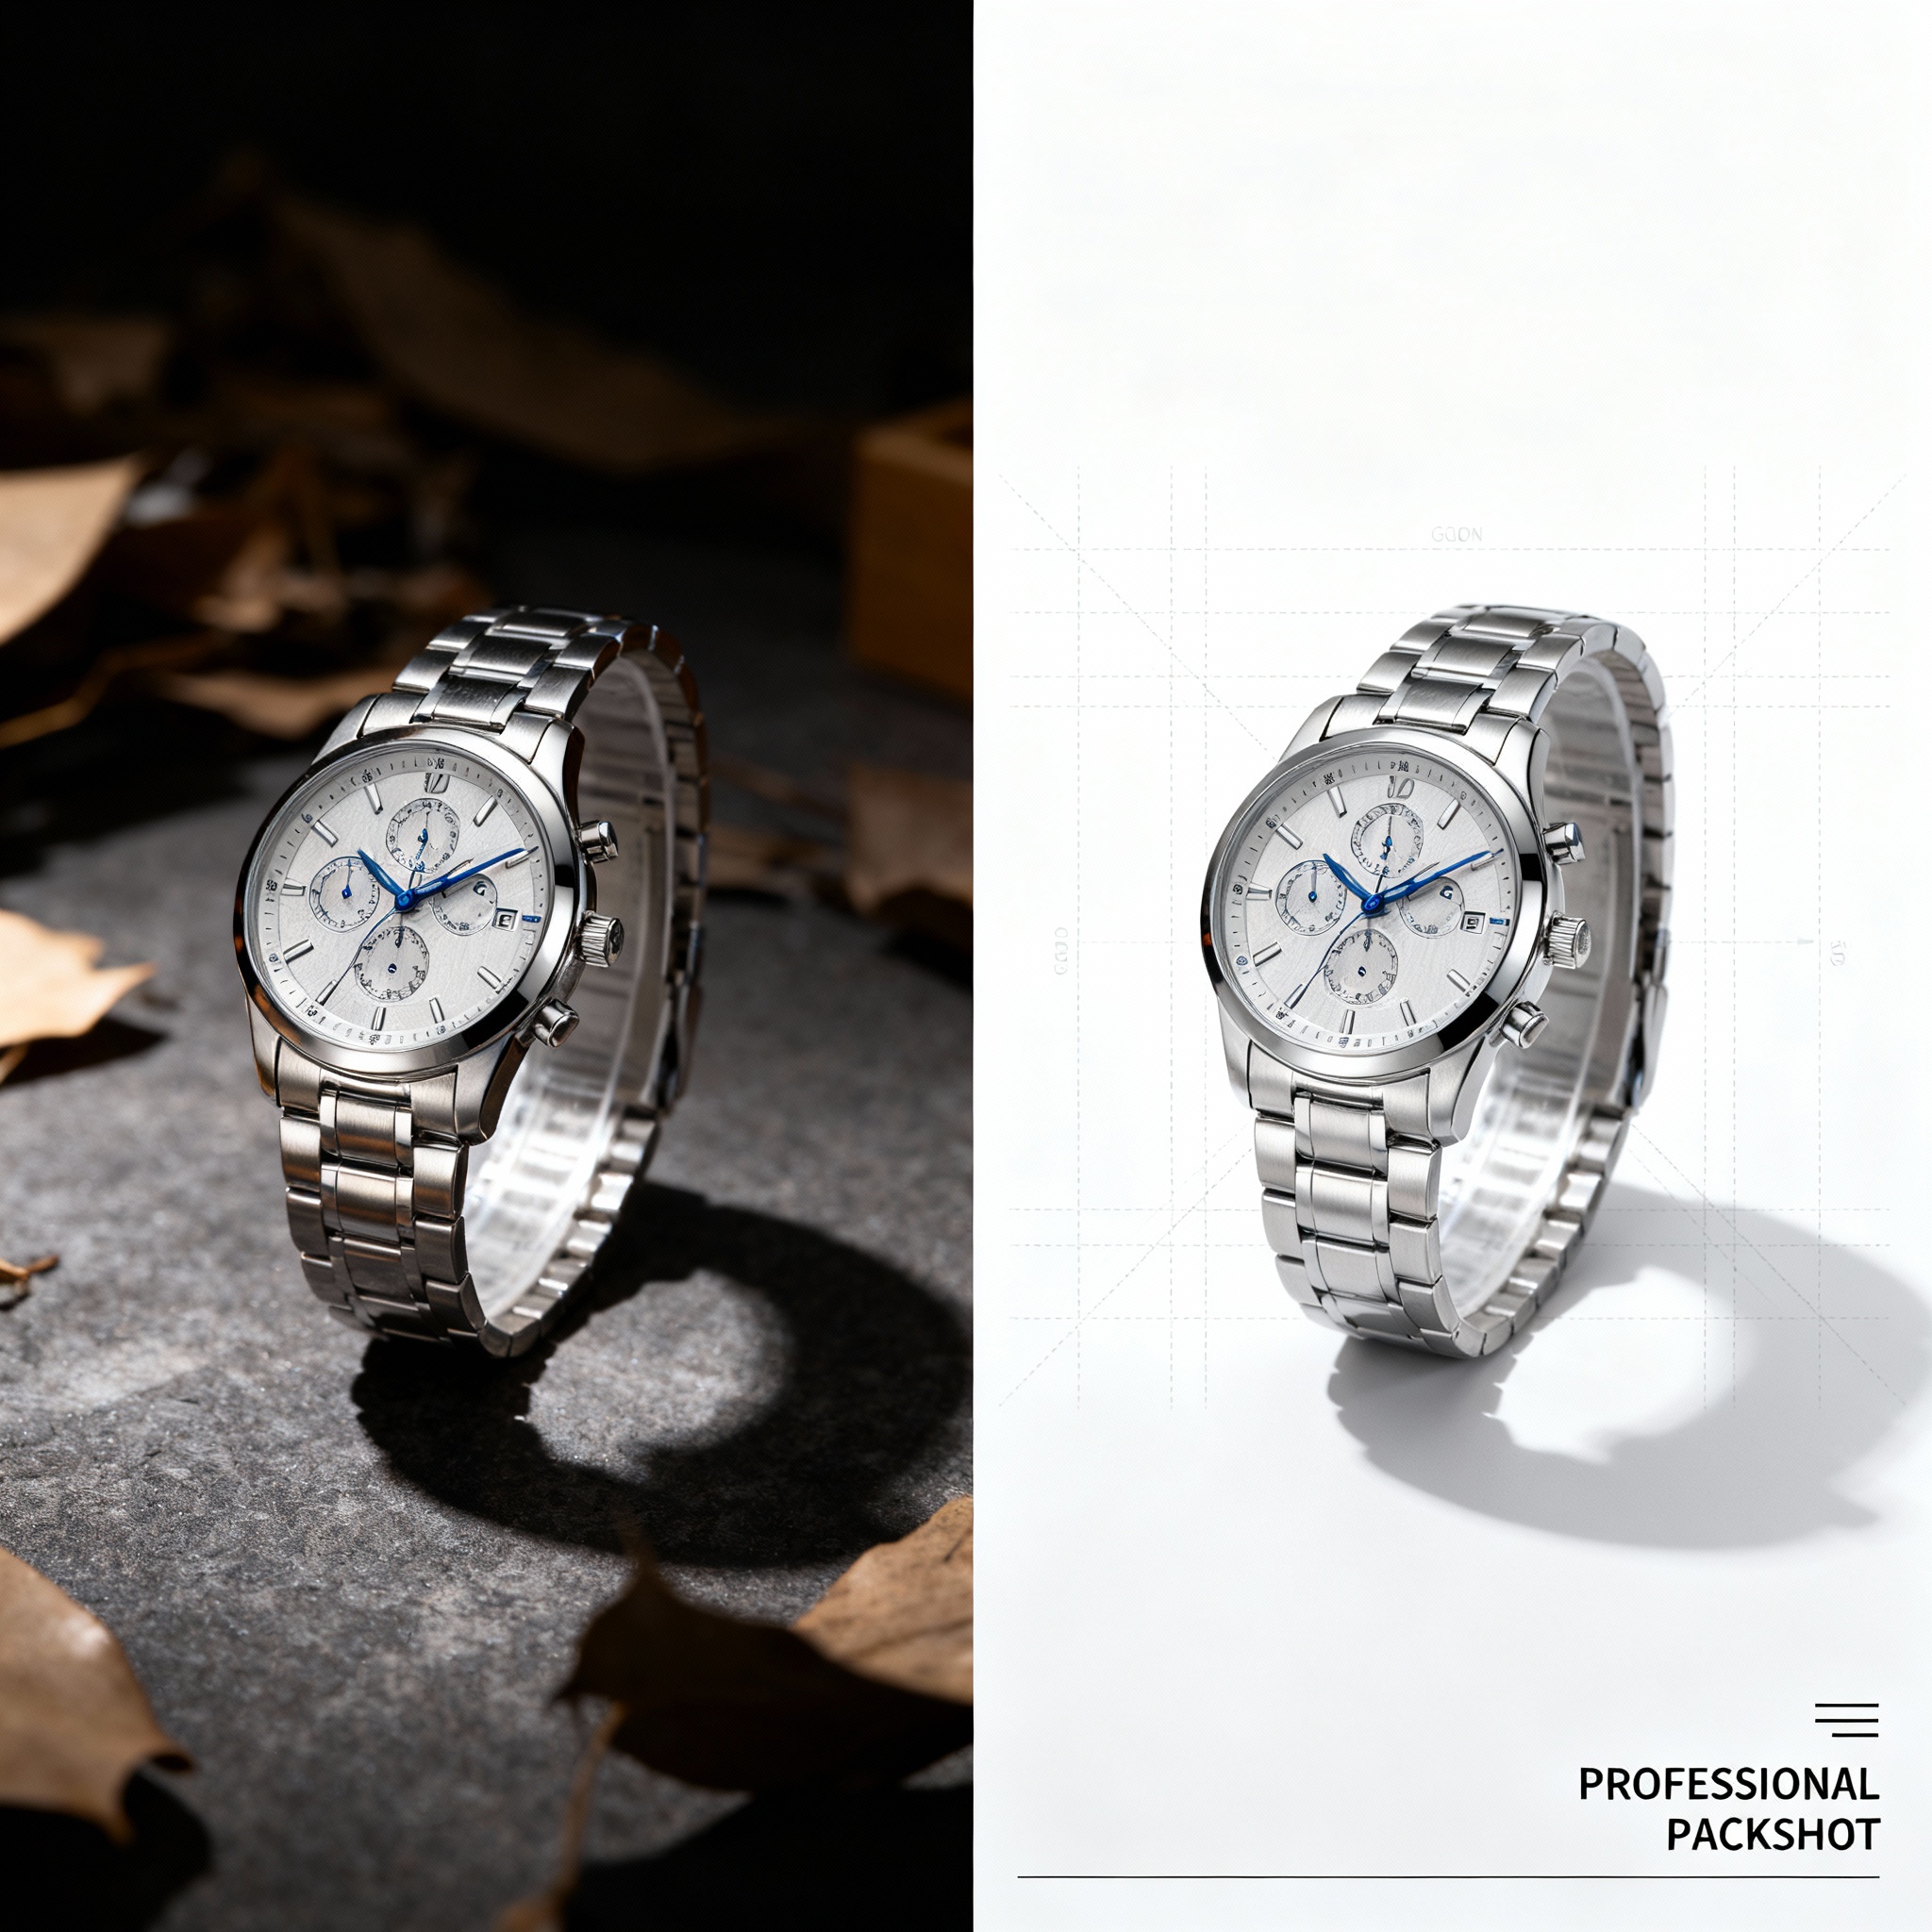 bria/product-packshot
Transform any product photo into professional 2000x2000px packshots with optimal positioning
Updated 1 year, 2 months ago
2K runs
 bria/product-cutout
Precise AI-powered product cutout with 256-level transparency for eCommerce
Updated 1 year, 2 months ago
4.1K runs
 qwen/qwen-image-edit
Edit images using a prompt. This model extends Qwen-Image’s unique text rendering capabilities to image editing tasks, enabling precise text editing
Updated 1 year, 2 months ago
2.1M runs
 fofr/color-matcher
Color match and white balance fixes for images
Updated 1 year, 3 months ago
238K runs
 wan-video/wan-2.2-i2v-a14b
Image-to-video at 720p and 480p with Wan 2.2 A14B
Updated 1 year, 3 months ago
64.3K runs
wan-video/wan-2.2-5b-fastThe fastest Wan 2.2 text-to-image and image-to-video model
Updated 1 year, 3 months ago
1.1M runs
 openai/clip
Official CLIP models, generate CLIP (clip-vit-large-patch14) text & image embeddings
Updated 1 year, 3 months ago
10.5M runs
 black-forest-labs/flux-krea-dev
An opinionated text-to-image model from Black Forest Labs in collaboration with Krea that excels in photorealism. Creates images that avoid the oversaturated "AI look".
Updated 1 year, 3 months ago
3.1M runs
 ibm-granite/granite-speech-3.3-8b
Granite-speech-3.3-8b is a compact and efficient speech-language model, specifically designed for automatic speech recognition (ASR) and automatic speech translation (AST).
Updated 1 year, 3 months ago
20.7K runs
 ibm-granite/granite-vision-3.3-2b
Granite-vision-3.3-2b is a compact and efficient vision-language model, specifically designed for visual document understanding, enabling automated content extraction from tables, charts, infographics, plots, diagrams, and more.
Updated 1 year, 3 months ago
288K runs
 black-forest-labs/flux-kontext-dev-lora
FLUX.1 Kontext[dev] image editing model for running lora finetunes
Updated 1 year, 3 months ago
288.7K runs
 prunaai/wan-2.2-image
This model generates beautiful cinematic 2 megapixel images in 3-4 seconds and is derived from the Wan 2.2 model through optimisation techniques from the pruna package
Updated 1 year, 3 months ago
1.3M runs
 black-forest-labs/flux-kontext-dev
Open-weight version of FLUX.1 Kontext
Updated 1 year, 4 months ago
8.1M runs
 black-forest-labs/flux-dev-lora
A version of flux-dev, a text to image model, that supports fast fine-tuned lora inference
Updated 1 year, 4 months ago
6.3M runs
 black-forest-labs/flux-dev
A 12 billion parameter rectified flow transformer capable of generating images from text descriptions
Updated 1 year, 4 months ago
53.3M runs
 black-forest-labs/flux-schnell
The fastest image generation model tailored for local development and personal use
Updated 1 year, 4 months ago
701.8M runs
 black-forest-labs/flux-schnell-lora
The fastest image generation model tailored for fine-tuned use
Updated 1 year, 4 months ago
3.8M runs
 resemble-ai/chatterbox
Generate expressive, natural speech. Features unique emotion control, instant voice cloning from short audio, and built-in watermarking.
Updated 1 year, 4 months ago
486K runs
 resemble-ai/chatterbox-pro
Generate expressive, natural speech with Resemble AI's Chatterbox.
Updated 1 year, 4 months ago
21.7K runs
 ibm-granite/granite-embedding-278m-multilingual
Granite-Embedding-278M-Multilingual is a 278M parameter model from the Granite Embeddings suite that can be used to generate high quality text embeddings
Updated 1 year, 5 months ago
6.2K runs
 topazlabs/image-upscale
Professional-grade image upscaling, from Topaz Labs
Updated 1 year, 6 months ago
3.8M runs
 black-forest-labs/flux-fill-dev
Open-weight inpainting model for editing and extending images. Guidance-distilled from FLUX.1 Fill [pro].
Updated 1 year, 7 months ago
2M runs
 black-forest-labs/flux-redux-schnell
Fast, efficient image variation model for rapid iteration and experimentation.
Updated 1 year, 7 months ago
93.7K runs
 black-forest-labs/flux-redux-dev
Open-weight image variation model. Create new versions while preserving key elements of your original.
Updated 1 year, 7 months ago
368.2K runs
 black-forest-labs/flux-depth-dev
Open-weight depth-aware image generation. Edit images while preserving spatial relationships.
Updated 1 year, 8 months ago
1.4M runs
 black-forest-labs/flux-canny-dev
Open-weight edge-guided image generation. Control structure and composition using Canny edge detection.
Updated 1 year, 8 months ago
266.6K runs
 ibm-granite/granite-3.2-8b-instruct
Granite-3.2-8B-Instruct is a 8-billion parameter 128K context length language model fine-tuned for reasoning and instruction-following capabilities.
Updated 1 year, 8 months ago
462.2K runs
 wan-video/wan-2.1-1.3b
Generate 5s 480p videos. Wan is an advanced and powerful visual generation model developed by Tongyi Lab of Alibaba Group
Updated 1 year, 8 months ago
51.7K runs
 ibm-granite/granite-3.1-8b-instruct
Granite-3.1-8B-Instruct is a lightweight and open-source 8B parameter model is designed to excel in instruction following tasks such as summarization, problem-solving, text translation, reasoning, code tasks, function-calling, and more.
Updated 1 year, 10 months ago
778.4K runs
 ibm-granite/granite-3.1-2b-instruct
Granite-3.1-2B-Instruct is a lightweight and open-source 2B parameter model designed to excel in instruction following tasks such as summarization, problem-solving, text translation, reasoning, code tasks, function-calling, and more.
Updated 1 year, 10 months ago
9.6K runs
 luma/photon
High-quality image generation model optimized for creative professional workflows and ultra-high fidelity outputs
Updated 1 year, 11 months ago
3.3M runs
 ibm-granite/granite-8b-code-instruct-128k
Join the Granite community where you can find numerous recipe workbooks to help you get started with a wide variety of use cases using this model. https://github.com/ibm-granite-community
Updated 2 years, 2 months ago
556.3K runs
 stability-ai/stable-diffusion-3
A text-to-image model with greatly improved performance in image quality, typography, complex prompt understanding, and resource-efficiency
Updated 2 years, 3 months ago
1.9M runs
 meta/meta-llama-3-70b
Base version of Llama 3, a 70 billion parameter language model from Meta.
Updated 2 years, 6 months ago
878.2K runs
 meta/meta-llama-3-70b-instruct
A 70 billion parameter language model from Meta, fine tuned for chat completions
Updated 2 years, 6 months ago
171.7M runs
 meta/meta-llama-3-8b-instruct
An 8 billion parameter language model from Meta, fine tuned for chat completions
Updated 2 years, 6 months ago
432.4M runs
 meta/meta-llama-3-8b
Base version of Llama 3, an 8 billion parameter language model from Meta.
Updated 2 years, 6 months ago
51.7M runs

 falcons-ai/nsfw_image_detection
Fine-Tuned Vision Transformer (ViT) for NSFW Image Classification
Updated 2 years, 11 months ago
190.8M runs
 meta/llama-2-7b-chat
A 7 billion parameter language model from Meta, fine tuned for chat completions
Updated 3 years ago
18.6M runs
 mistralai/mistral-7b-v0.1
A 7 billion parameter language model from Mistral.
Updated 3 years, 1 month ago
1.9M runs
 meta/llama-2-70b
Base version of Llama 2, a 70 billion parameter language model from Meta.
Updated 3 years, 2 months ago
620.2K runs
 meta/llama-2-13b-chat
A 13 billion parameter language model from Meta, fine tuned for chat completions
Updated 3 years, 2 months ago
4.9M runs
 meta/llama-2-13b
Base version of Llama 2 13B, a 13 billion parameter language model
Updated 3 years, 2 months ago
209.4K runs
 meta/llama-2-7b
Base version of Llama 2 7B, a 7 billion parameter language model
Updated 3 years, 2 months ago
660.2K runs